Autonomous Action and Interaction under Uncertainty
Assistant Professor Zachary Sunberg
University of Colorado Boulder
October 9th, 2026
Perspectives:
- Mathematical Theory
- Numerical Simulation
- Real-World Experiments


Motivating Applications
Single-Agent POMPDs
Multi-Agent Games
Autonomy and People
Open Questions

The ADCL studies decision making under uncertainty for (semi) autonomous systems.
Motivating Applications
Single-Agent POMPDs
Multi-Agent Games
Autonomy and People
Open Questions
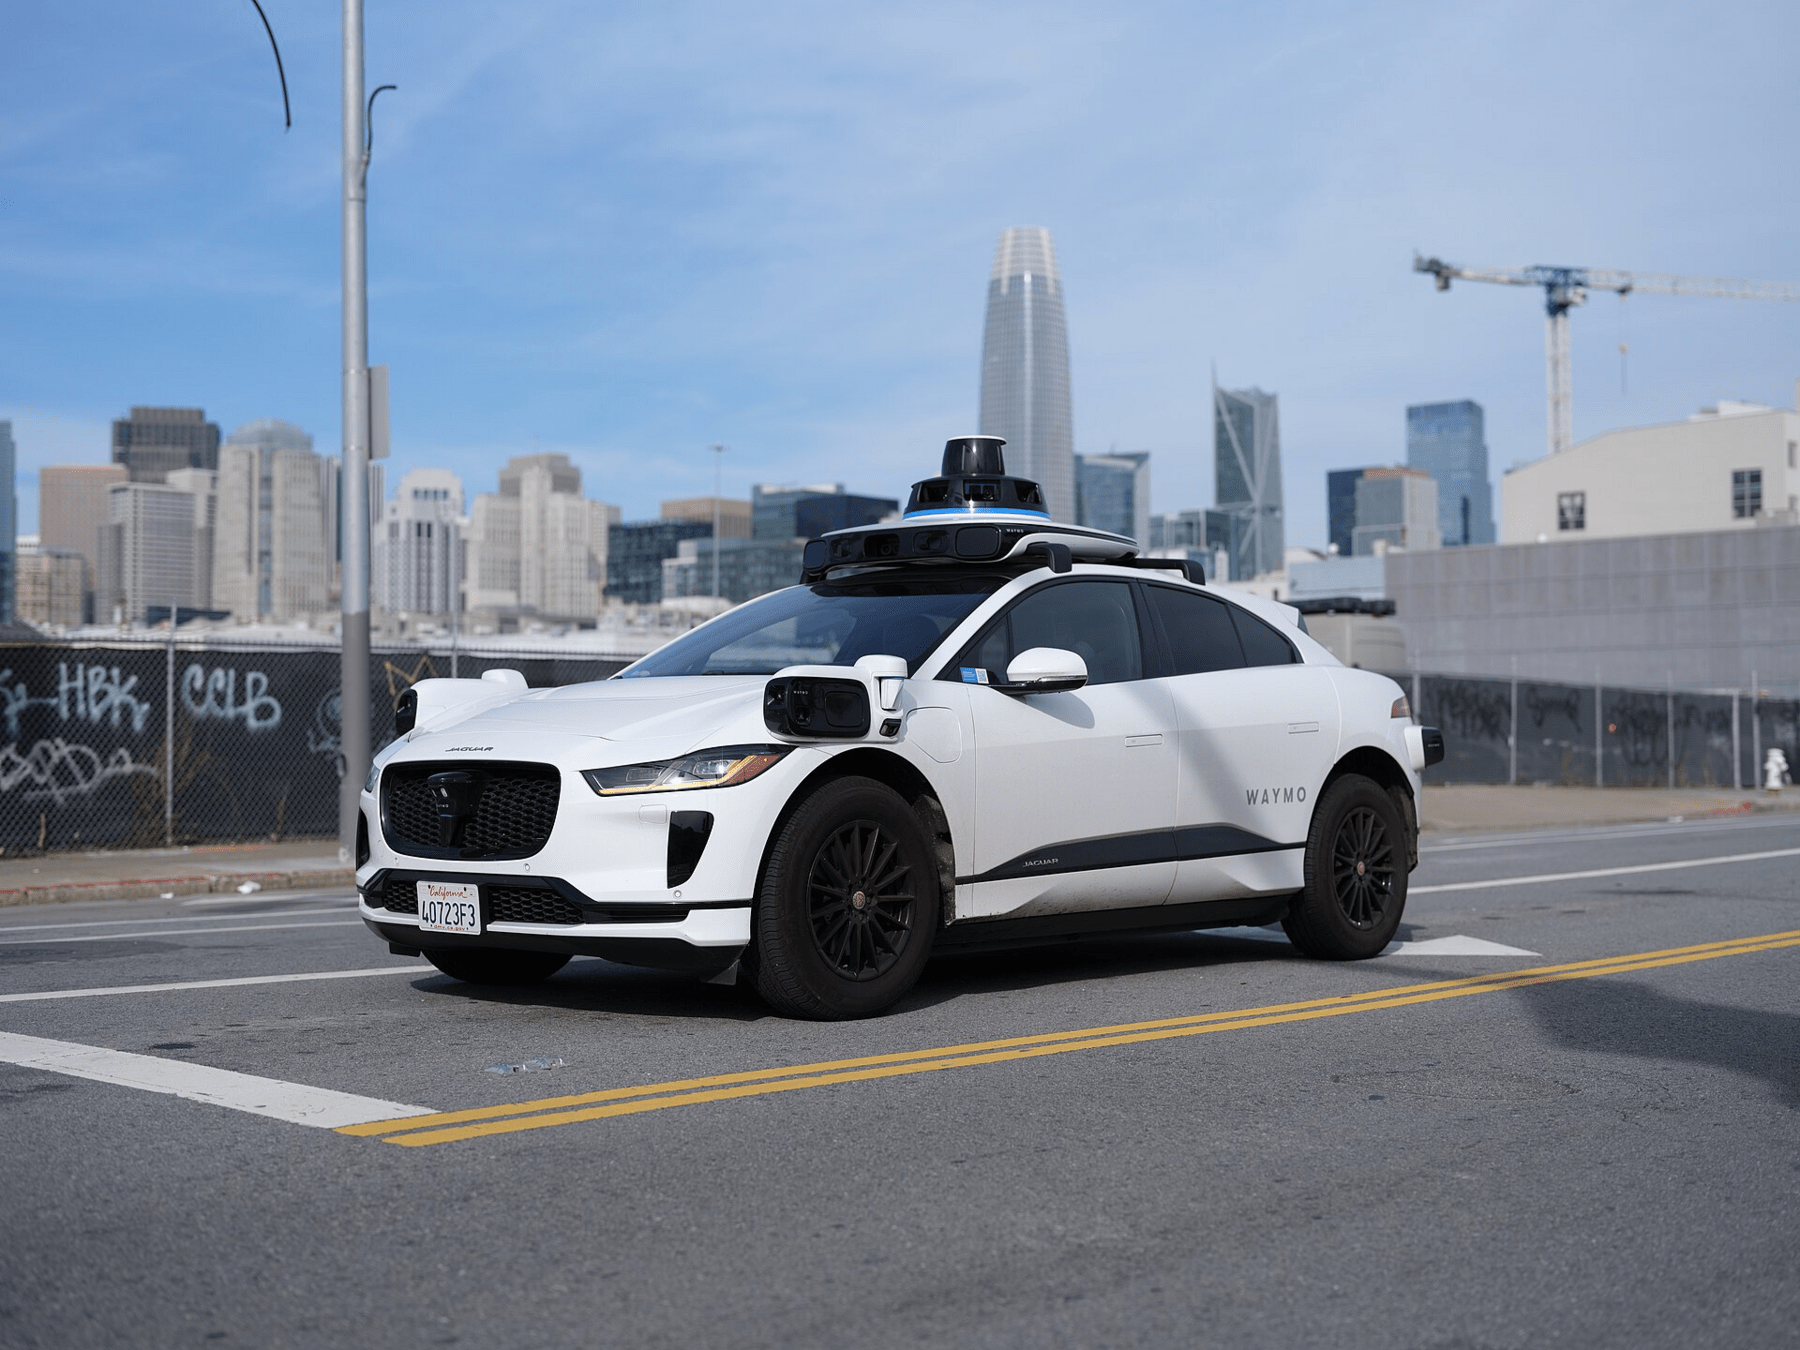
Application 1: Mobility
Waymo: over 94% reduction in serious injury crash rates (regardless of fault)
Two days ago:
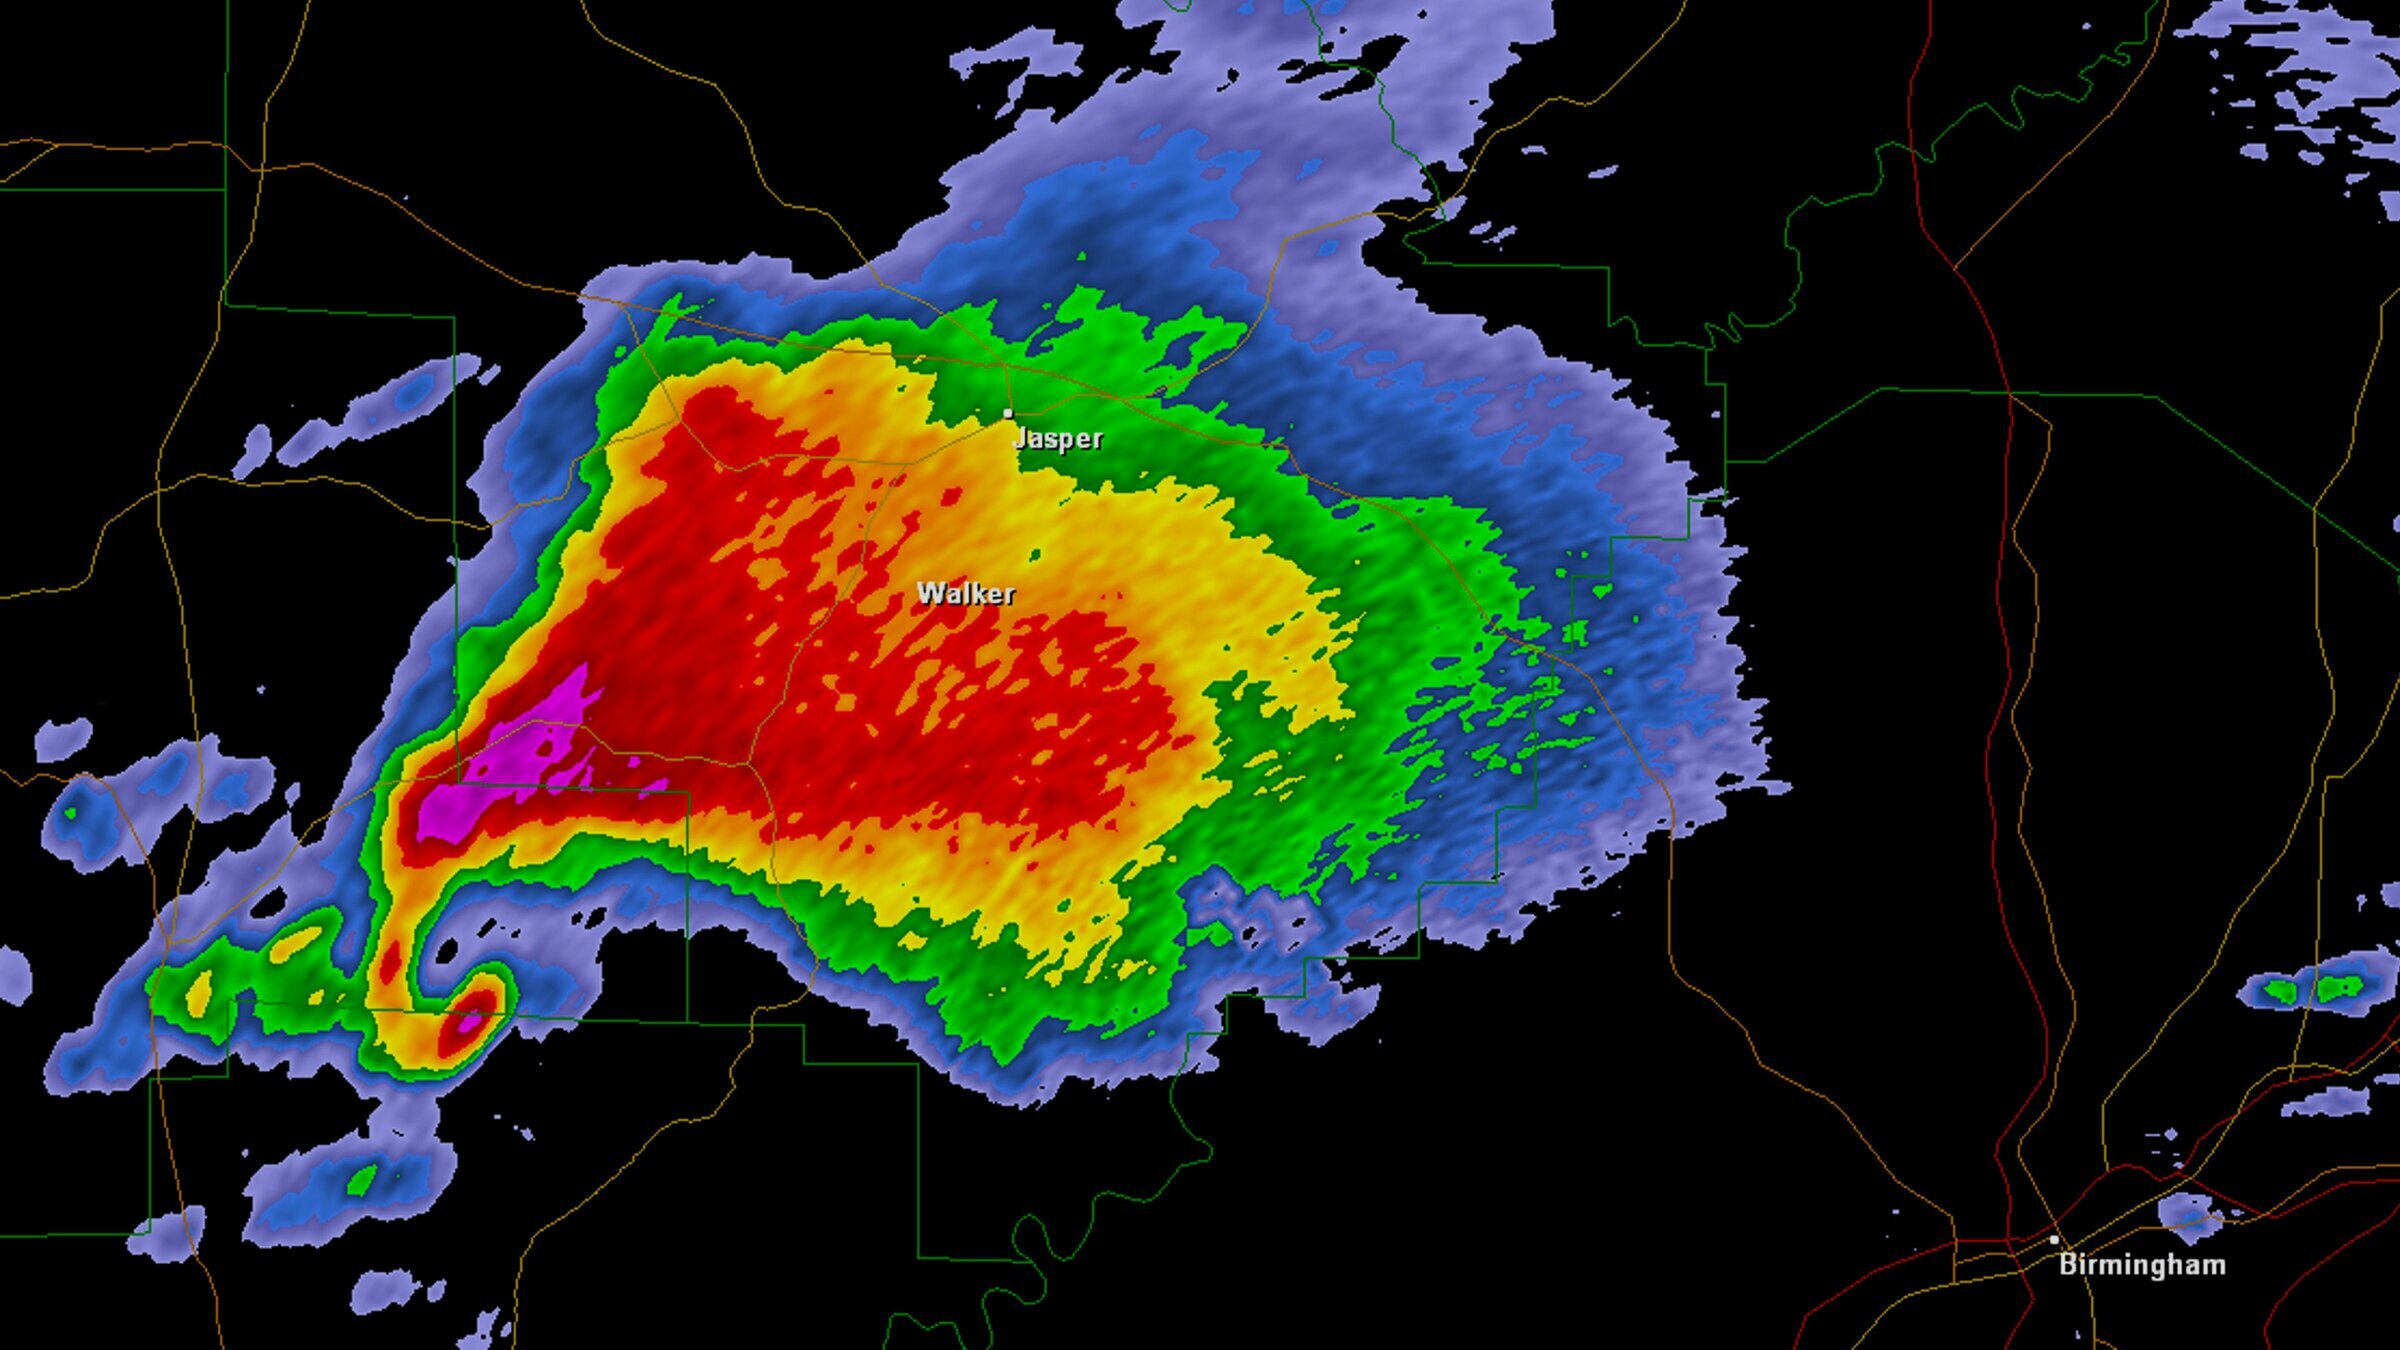
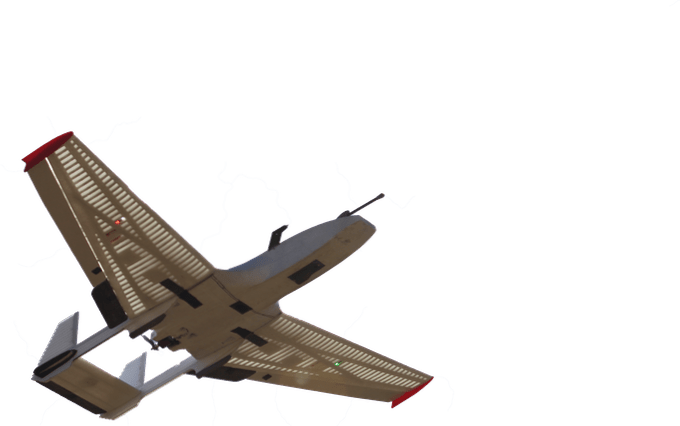
Application 2: Science
Application 3: Defense
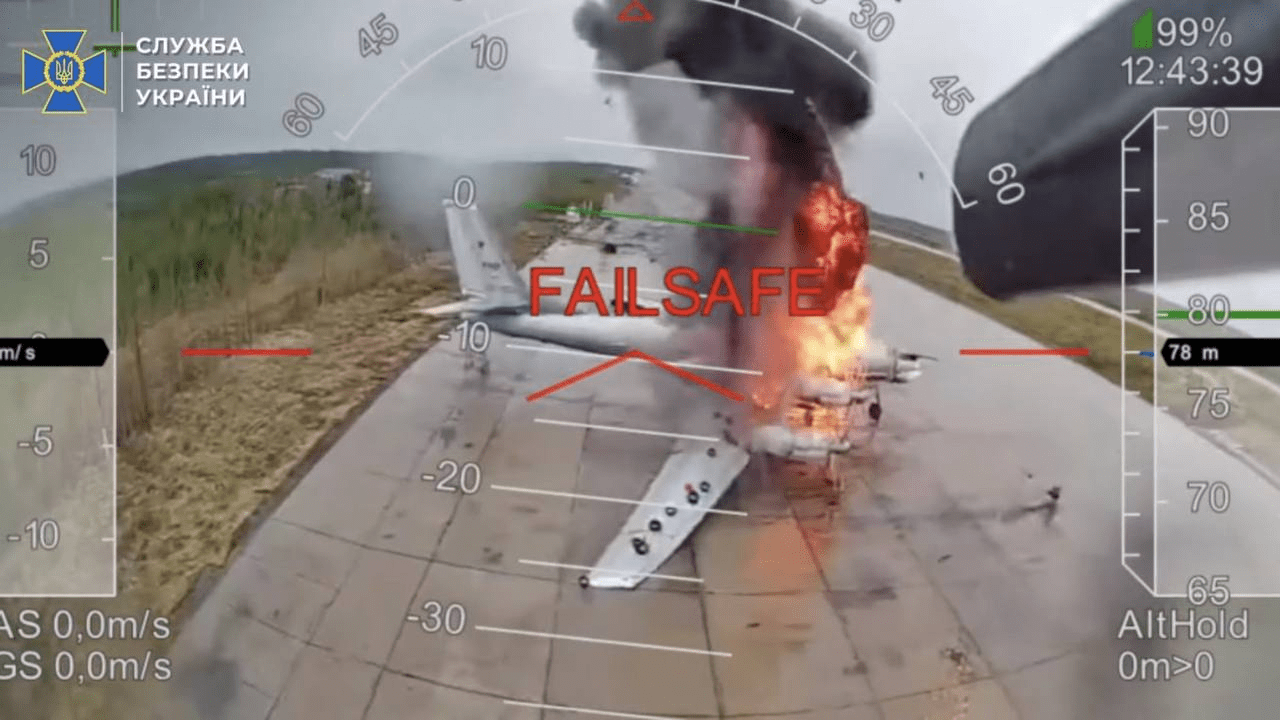
By Ssu.gov.ua, CC BY 4.0, https://commons.wikimedia.org/w/index.php?curid=166885128
By дизайн – Тетяна Балута.Скульптор: Володимир Дем`яненкоНаціональний банк України - https://bank.gov.ua/files/coins_images/8GJr0.png?v=14, Public Domain, https://commons.wikimedia.org/w/index.php?curid=175872503
"Our weapon is our intellect"

Motivating Applications
Single-Agent POMPDs
Multi-Agent Games
Autonomy and People
Open Questions
Single-Agent POMPDs
Multi-Agent Games
Autonomy and People
Open Questions
Motivating Applications
A Mathematical Model: The POMDP
(Partially Observable Markov Decision Process)
state observation decision reward
Dynamic Decision Networks
\(m_{t}\)
\(o_{t}\)
\(a_{t}\)
\(s_{t}\)
\(r_{t}\)
\(m_{t+1}\)
\(o_{t+1}\)
\(a_{t+1}\)
\(s_{t+1}\)
\(r_{t+1}\)
\(\cdots\)
\(\cdots\)
step t
step t+1
\(m_{t}\)
\(o_{t}\)
\(a_{t}\)
\(s_{t}\)
\(r_{t}\)
\(m_{t+1}\)
\(o_{t+1}\)
\(a_{t+1}\)
\(s_{t+1}\)
\(r_{t+1}\)
\(\cdots\)
\(\cdots\)
step t
step t+1
\(a\)
\(b\)
\(c\)
Chance nodes:
Random variables conditioned on parents
\[P(c \mid a, b)\]
Just like a Bayesian Network!
Decision Nodes:
An agent gets to choose the distribution
Utility Nodes:
An agent cares about these values
Time
A Mathematical Model: The POMDP
(Partially Observable Markov Decision Process)
state observation decision reward
\(m_{t}\)
\(o_{t}\)
\(a_{t}\)
\(s_{t}\)
\(r_{t}\)
\(m_{t+1}\)
\(o_{t+1}\)
\(a_{t+1}\)
\(s_{t+1}\)
\(r_{t+1}\)
\(\cdots\)
\(\cdots\)
step t
step t+1
\(m_{t}\)
\(o_{t}\)
\(a_{t}\)
\(s_{t}\)
\(r_{t}\)
\(m_{t+1}\)
\(o_{t+1}\)
\(a_{t+1}\)
\(s_{t+1}\)
\(r_{t+1}\)
\(\cdots\)
\(\cdots\)
step t
step t+1
State: \(s_t \in \mathcal{S}\)
Everything that changes or is unknown in the environment
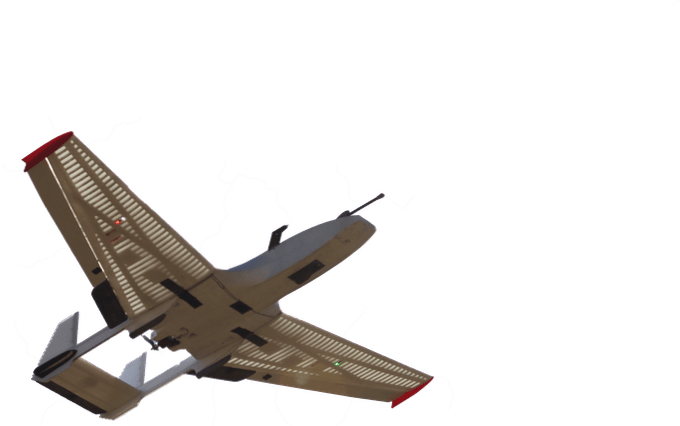
\(s = [x, y, z,\;\; \phi, \theta, \psi,\;\; u, v, w,\;\; p,q,r]\)
\(\mathcal{S} = \mathbb{R}^{12} \times \mathbb{R}^\infty\)
\(\mathcal{S} = \mathbb{R}^{12}\)
A Mathematical Model: The POMDP
(Partially Observable Markov Decision Process)
state observation decision reward
\(m_{t}\)
\(o_{t}\)
\(a_{t}\)
\(s_{t}\)
\(r_{t}\)
\(m_{t+1}\)
\(o_{t+1}\)
\(a_{t+1}\)
\(s_{t+1}\)
\(r_{t+1}\)
\(\cdots\)
\(\cdots\)
step t
step t+1
\(m_{t}\)
\(o_{t}\)
\(a_{t}\)
\(s_{t}\)
\(r_{t}\)
\(m_{t+1}\)
\(o_{t+1}\)
\(a_{t+1}\)
\(s_{t+1}\)
\(r_{t+1}\)
\(\cdots\)
\(\cdots\)
step t
step t+1
State: \(s_t \in \mathcal{S}\)
Action: \(a_t \in \mathcal{A}\)
What the agent does in the environment
- Throttle
- Ailerons
- Elevator
- Rudder
- Drifter deployment
A Mathematical Model: The POMDP
(Partially Observable Markov Decision Process)
state observation decision reward
\(m_{t}\)
\(o_{t}\)
\(a_{t}\)
\(s_{t}\)
\(r_{t}\)
\(m_{t+1}\)
\(o_{t+1}\)
\(a_{t+1}\)
\(s_{t+1}\)
\(r_{t+1}\)
\(\cdots\)
\(\cdots\)
step t
step t+1
\(m_{t}\)
\(o_{t}\)
\(a_{t}\)
\(s_{t}\)
\(r_{t}\)
\(m_{t+1}\)
\(o_{t+1}\)
\(a_{t+1}\)
\(s_{t+1}\)
\(r_{t+1}\)
\(\cdots\)
\(\cdots\)
step t
step t+1
State: \(s_t \in \mathcal{S}\)
Action: \(a_t \in \mathcal{A}\)
Observation: \(o_t \in \mathcal{O}\)
What the agent measures
Location (GPS), Temperature and Pressure at Location
A Mathematical Model: The POMDP
(Partially Observable Markov Decision Process)
state observation decision reward
\(m_{t}\)
\(o_{t}\)
\(a_{t}\)
\(s_{t}\)
\(r_{t}\)
\(m_{t+1}\)
\(o_{t+1}\)
\(a_{t+1}\)
\(s_{t+1}\)
\(r_{t+1}\)
\(\cdots\)
\(\cdots\)
step t
step t+1
\(m_{t}\)
\(o_{t}\)
\(a_{t}\)
\(s_{t}\)
\(r_{t}\)
\(m_{t+1}\)
\(o_{t+1}\)
\(a_{t+1}\)
\(s_{t+1}\)
\(r_{t+1}\)
\(\cdots\)
\(\cdots\)
step t
step t+1
State: \(s_t \in \mathcal{S}\)
Action: \(a_t \in \mathcal{A}\)
Observation: \(o_t \in \mathcal{O}\)
Transition Distribution: \(T(s_{t+1} \mid s_t, a_t)\)
The (probabilistic) dynamics of the state
A Mathematical Model: The POMDP
(Partially Observable Markov Decision Process)
state observation decision reward
\(m_{t}\)
\(o_{t}\)
\(a_{t}\)
\(s_{t}\)
\(r_{t}\)
\(m_{t+1}\)
\(o_{t+1}\)
\(a_{t+1}\)
\(s_{t+1}\)
\(r_{t+1}\)
\(\cdots\)
\(\cdots\)
step t
step t+1
\(m_{t}\)
\(o_{t}\)
\(a_{t}\)
\(s_{t}\)
\(r_{t}\)
\(m_{t+1}\)
\(o_{t+1}\)
\(a_{t+1}\)
\(s_{t+1}\)
\(r_{t+1}\)
\(\cdots\)
\(\cdots\)
step t
step t+1
State: \(s_t \in \mathcal{S}\)
Action: \(a_t \in \mathcal{A}\)
Observation: \(o_t \in \mathcal{O}\)
Transition Distribution: \(T(s_{t+1} \mid s_t, a_t)\)
Observation Distribution: \(Z(o_{t} \mid s_{t})\)
The measurement process (may also depend on \(a_t\))
A Mathematical Model: The POMDP
(Partially Observable Markov Decision Process)
state observation decision reward
\(m_{t}\)
\(o_{t}\)
\(a_{t}\)
\(s_{t}\)
\(r_{t}\)
\(m_{t+1}\)
\(o_{t+1}\)
\(a_{t+1}\)
\(s_{t+1}\)
\(r_{t+1}\)
\(\cdots\)
\(\cdots\)
step t
step t+1
\(m_{t}\)
\(o_{t}\)
\(a_{t}\)
\(s_{t}\)
\(r_{t}\)
\(m_{t+1}\)
\(o_{t+1}\)
\(a_{t+1}\)
\(s_{t+1}\)
\(r_{t+1}\)
\(\cdots\)
\(\cdots\)
step t
step t+1
State: \(s_t \in \mathcal{S}\)
Action: \(a_t \in \mathcal{A}\)
Observation: \(o_t \in \mathcal{O}\)
Transition Distribution: \(T(s_{t+1} \mid s_t, a_t)\)
Observation Distribution: \(Z(o_{t} \mid s_{t})\)
Reward Function: \(r_t = R(s_t, a_t)\)
\[\underset{\pi(a_t \mid o_{1:t})}{\text{maximize}} \quad \text{E}\left[ \sum_{t=0}^\infty R(s_t, a_t) \right]\]
Objective:
A Mathematical Model: The POMDP
(Partially Observable Markov Decision Process)
state observation decision reward
\(m_{t}\)
\(o_{t}\)
\(a_{t}\)
\(s_{t}\)
\(r_{t}\)
\(m_{t+1}\)
\(o_{t+1}\)
\(a_{t+1}\)
\(s_{t+1}\)
\(r_{t+1}\)
\(\cdots\)
\(\cdots\)
step t
step t+1
\(m_{t}\)
\(o_{t}\)
\(a_{t}\)
\(s_{t}\)
\(r_{t}\)
\(m_{t+1}\)
\(o_{t+1}\)
\(a_{t+1}\)
\(s_{t+1}\)
\(r_{t+1}\)
\(\cdots\)
\(\cdots\)
step t
step t+1
State: \(s_t \in \mathcal{S}\)
Action: \(a_t \in \mathcal{A}\)
Observation: \(o_t \in \mathcal{O}\)
Transition Distribution: \(T(s_{t+1} \mid s_t, a_t)\)
Observation Distribution: \(Z(o_{t} \mid s_{t})\)
Reward Function: \(r_t = R(s_t, a_t)\)
Memory: \(m_t\)
Typically a belief about the state \(b_t\)
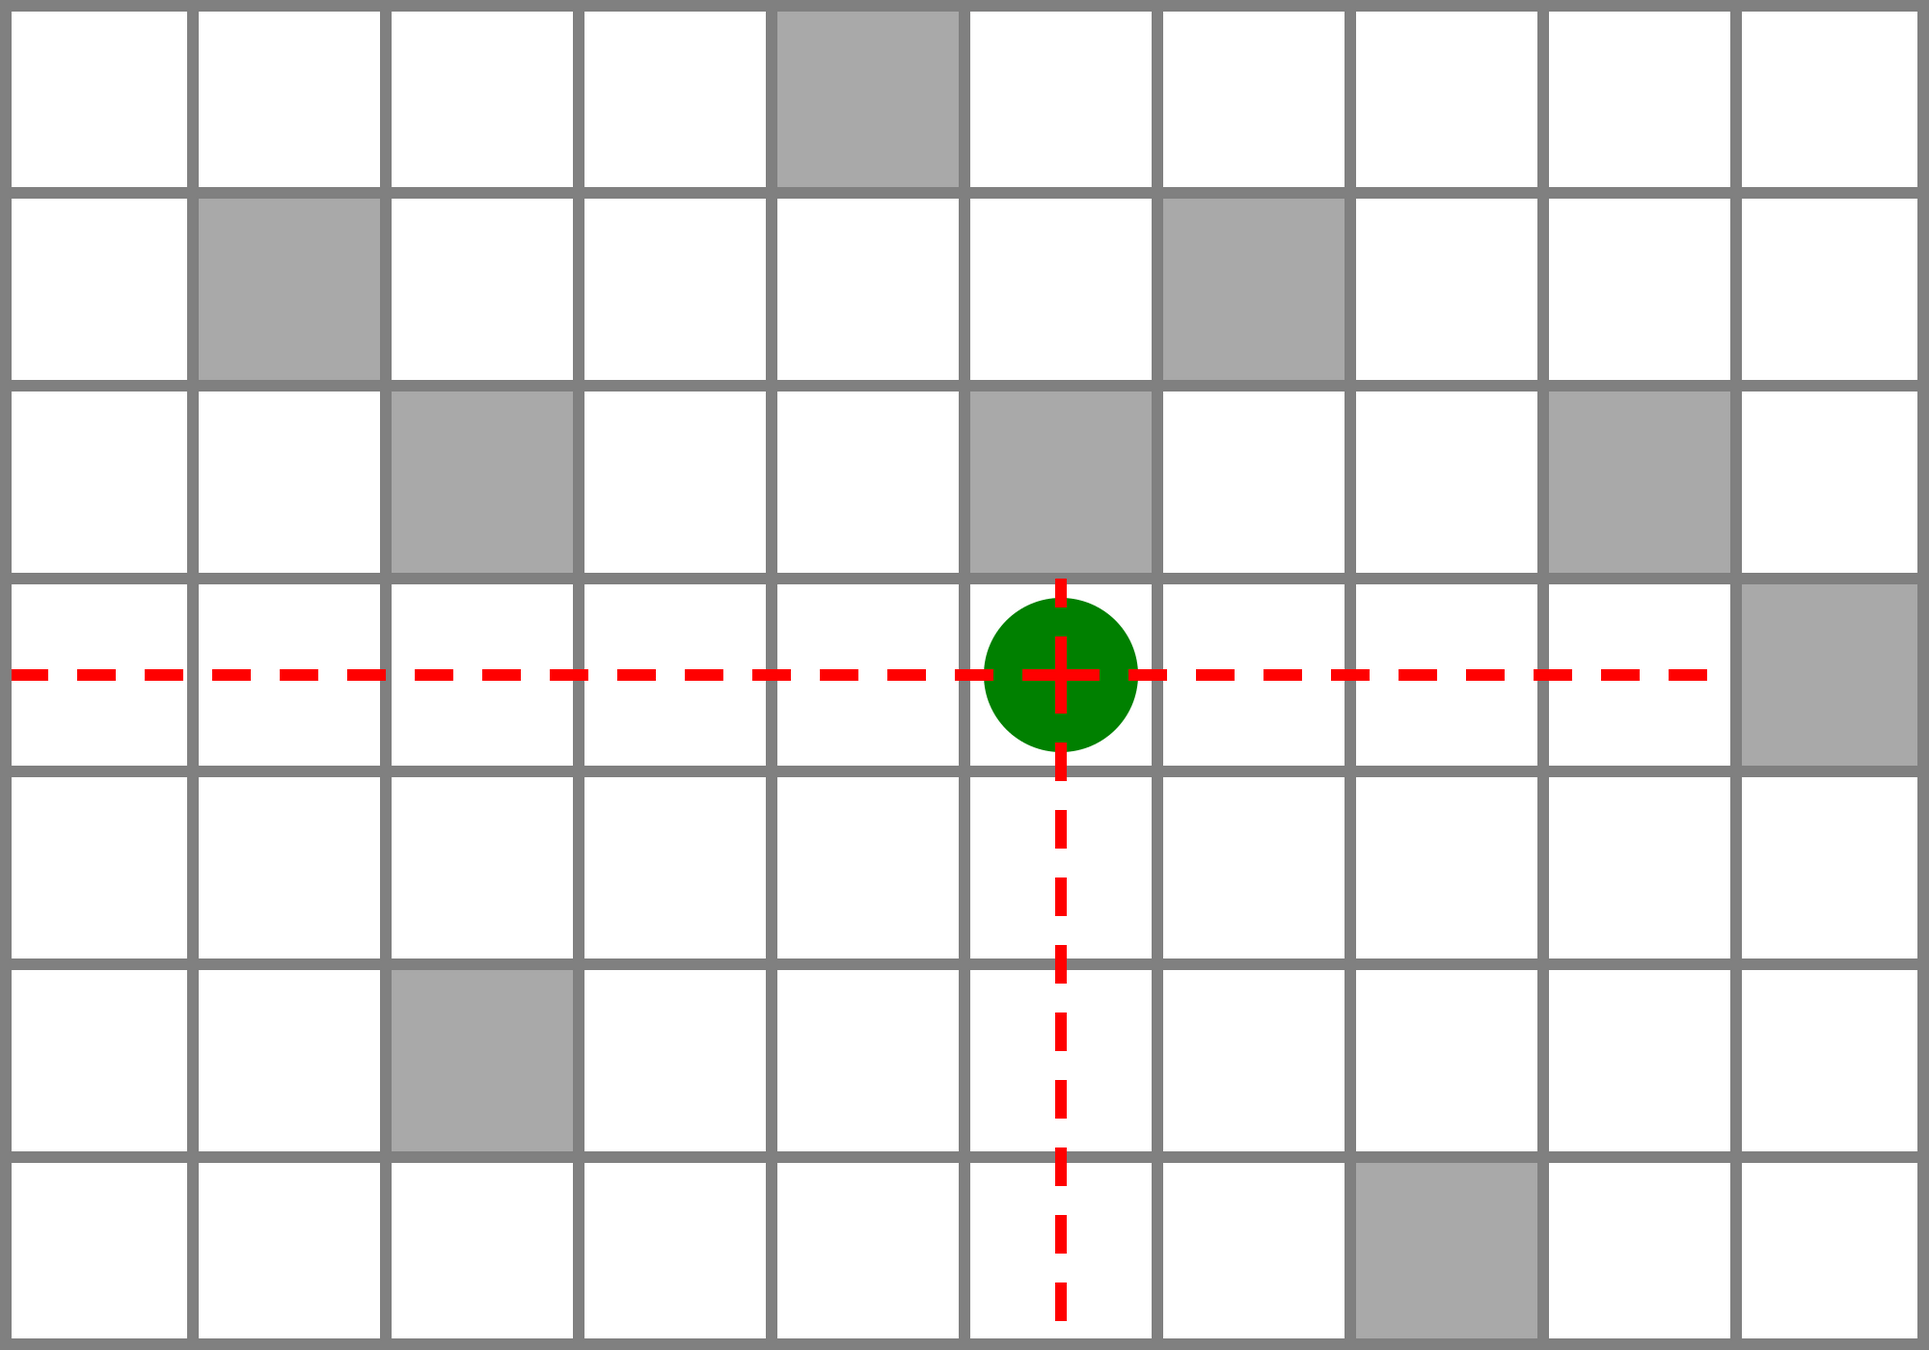
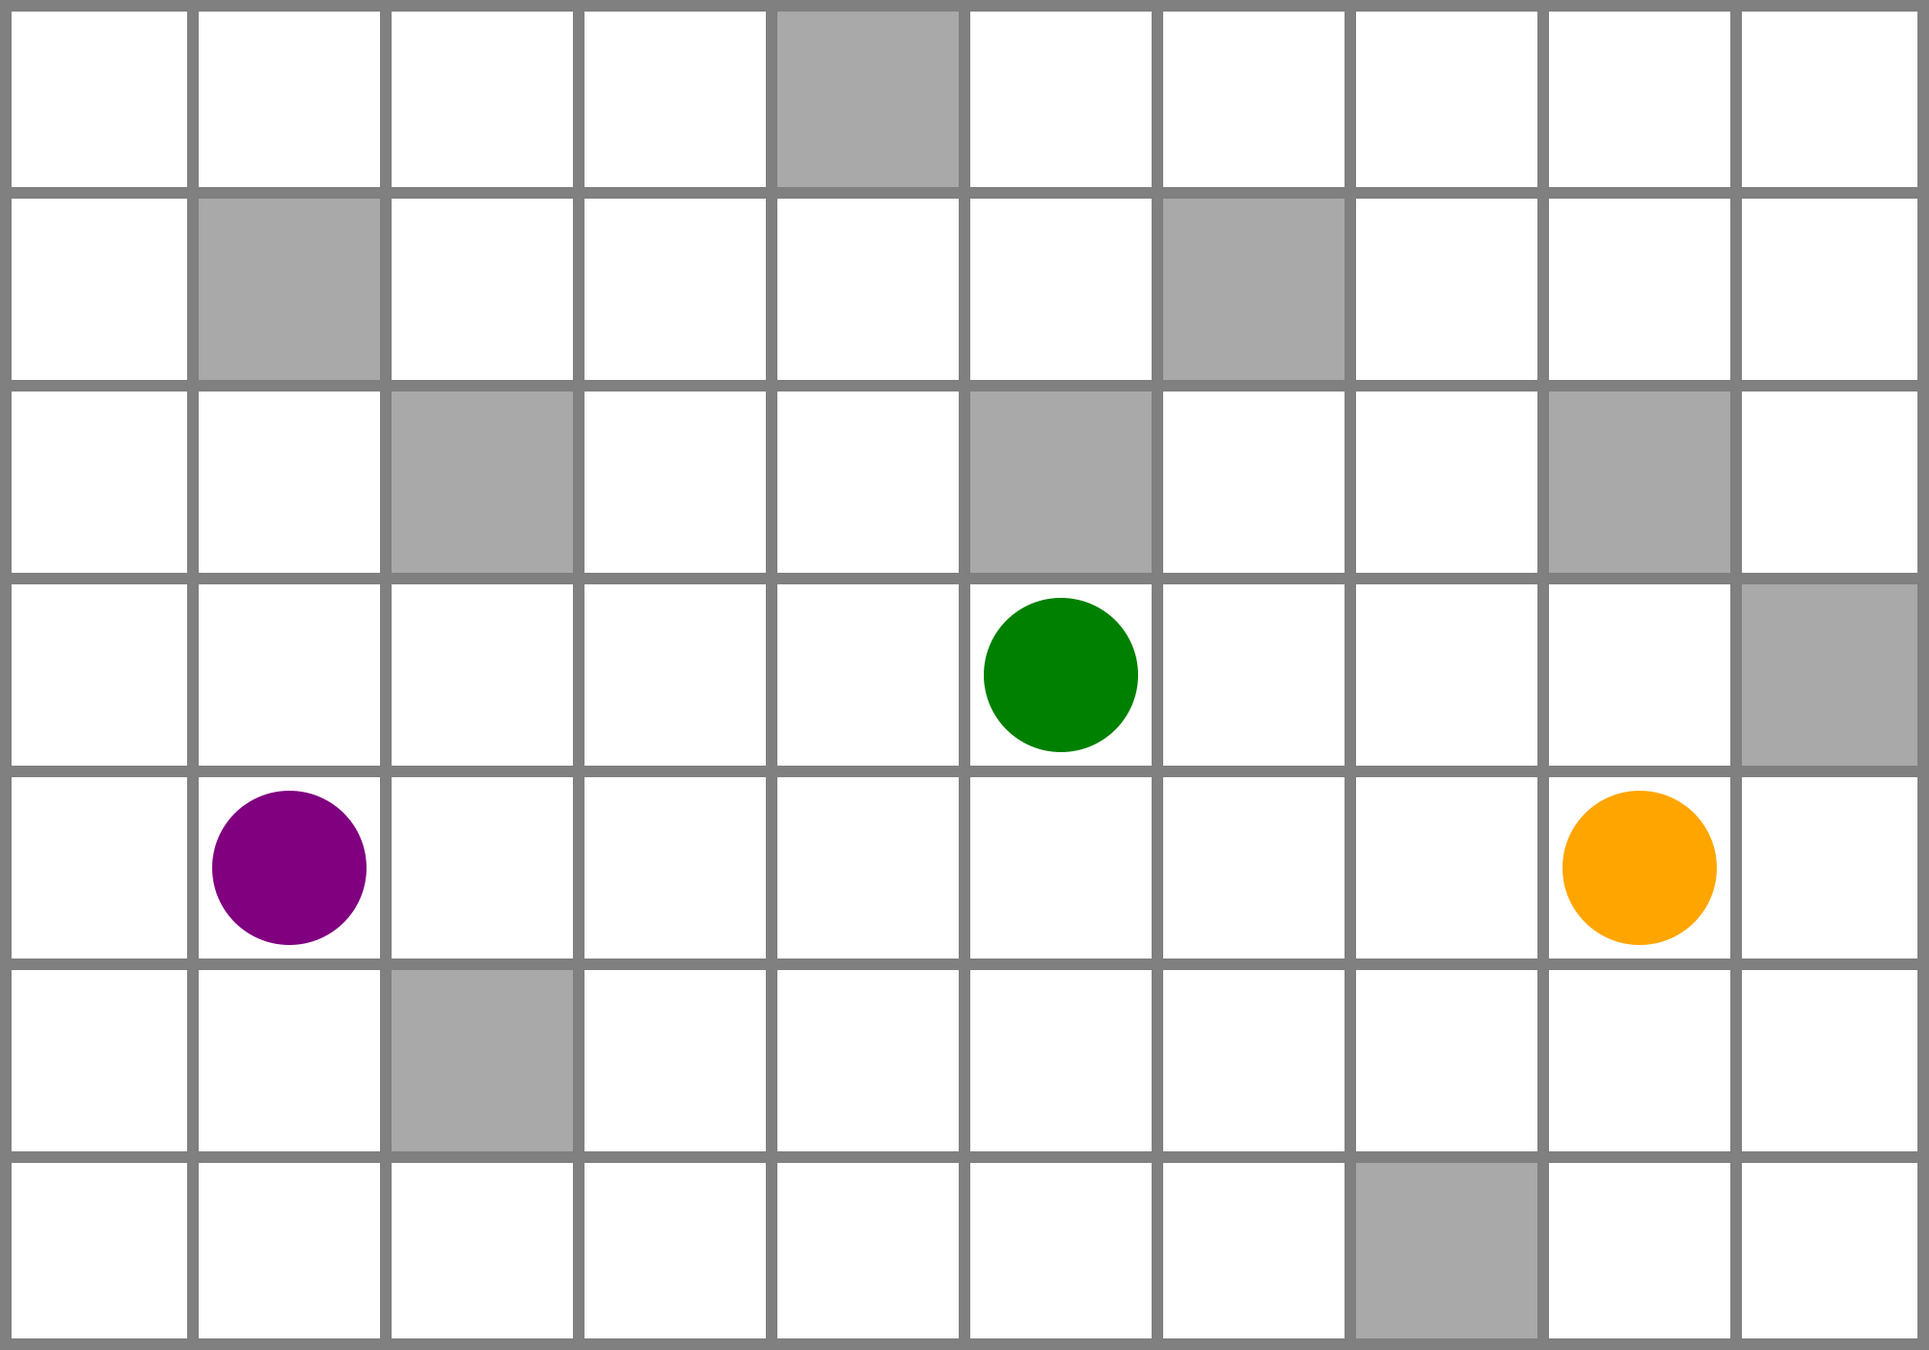
A POMDP Example from DMU: Laser Tag
"Some of the best homework assignments I have ever done." - A DMU Student's FCQ response
State
Agent
Target
Wanderer
Actions
Move
Measure
Observation
Lasers

POMDPs.jl
Environment
Belief Updater
Planner
True State
Observation
\(O(|\mathcal{S}|^2)\)
Solving a POMDP
\(m_t = b_t\)
\[b_t(s) = P\left(s_t = s \mid b_0, a_0, o_1 \ldots a_{t-1}, o_{t}\right)\]
\[ = P\left(s_t = s \mid b_{t-1}, a_{t-1}, o_{t}\right)\]
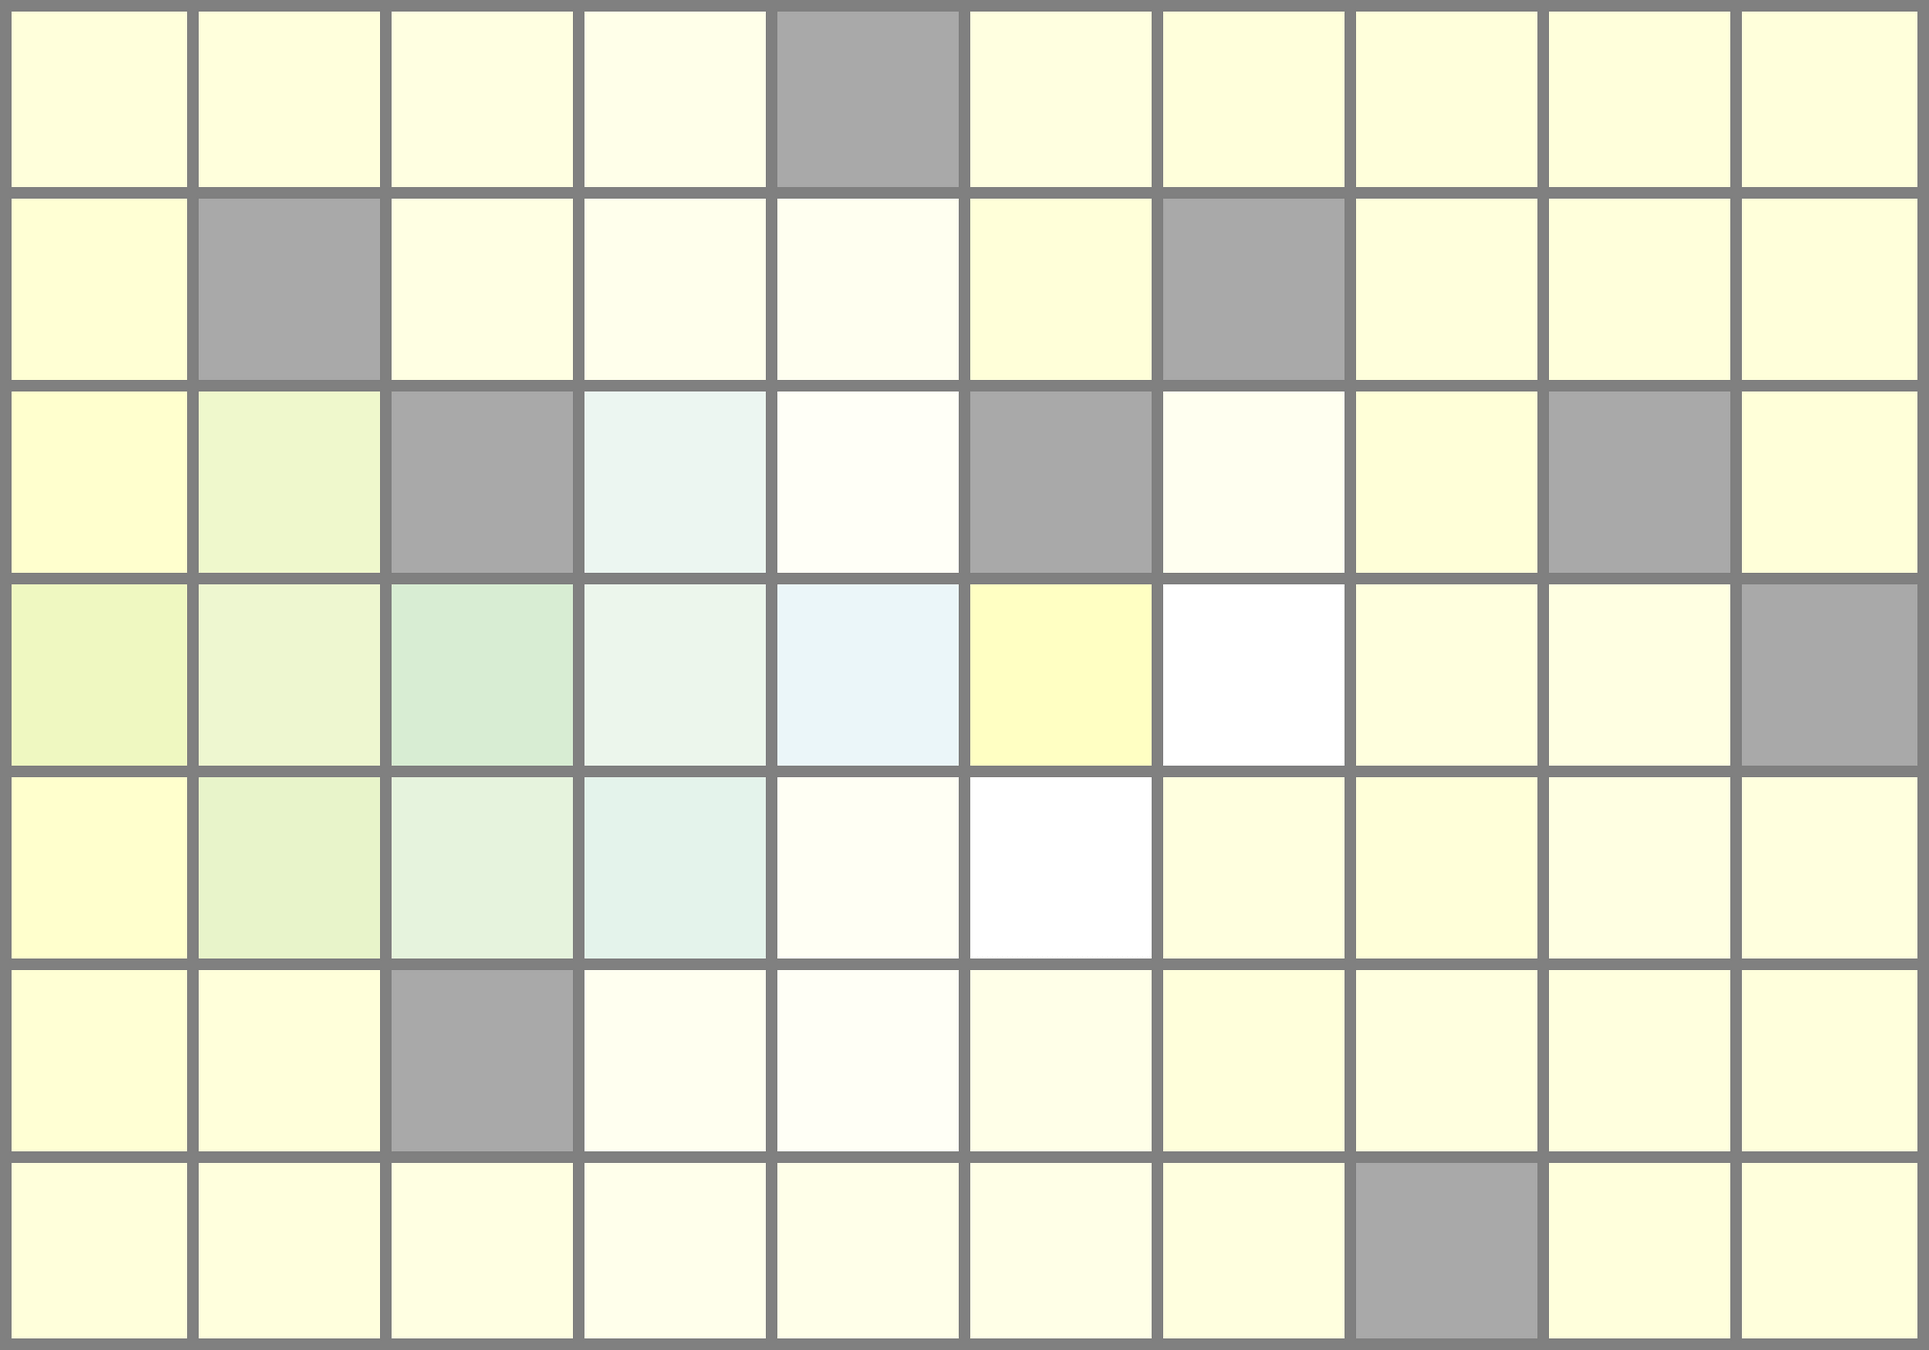
Belief
\(o_t\)
\(s_t\)
A POMDP Example from DMU: Laser Tag
State
Agent
Target
Wanderer
Actions
Move
Measure
Observation
Lasers
Belief
Target
Wanderer
Environment
Belief Updater
Planner
True State
Observation
Solving a POMDP
\(m_t = b_t\)
\[b_t(s) = P\left(s_t = s \mid b_0, a_0, o_1 \ldots a_{t-1}, o_{t}\right)\]
\[ = P\left(s_t = s \mid b_{t-1}, a_{t-1}, o_{t}\right)\]
Belief (Memory)
\(o_t\)
\(s_t\)
\(a =\, \uparrow\)
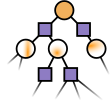
\(Q(b, a)\)
\(O(|\mathcal{S}|^2)\)
Why are POMDPs difficult?
- Curse of History
- Curse of dimensionality
- State space
- Observation space
- Action space
Tree size: \(O\left(\left(|A||O|\right)^D\right)\)
Curse of Dimensionality
\(d\) dimensions, \(k\) segments \(\,\rightarrow \, |S| = k^d\)


1 dimension
e.g. \(s = x \in S = \{1,2,3,4,5\}\)
\(|S| = 5\)
2 dimensions
e.g. \(s = (x,y) \in S = \{1,2,3,4,5\}^2\)
\(|S| = 25\)
3 dimensions
e.g. \(s = (x,y,x_h) \in S = \{1,2,3,4,5\}^3\)
\(|S| = 125\)
(Discretize each dimension into 5 segments)
\(x\)
\(y\)
\(x_h\)
Breaking the Curse: Monte Carlo Integration
Find \(\underset{s\sim b}{E}[R(s)]\)
\[=\sum_{s \in S} R(s) b(s)\]
Monte Carlo Integration
\(Q_N \equiv \frac{1}{N} \sum_{i=1}^N R(s_i)\)
\(s_i \sim b\) i.i.d.
\(\text{Var}(Q_N) = \text{Var}\left(\frac{1}{N} \sum_{i=1}^N R(s_i)\right)\)
\(= \frac{1}{N^2} \sum_{i=1}^N\text{Var}\left(R(s_i)\right)\)
\(= \frac{1}{N} \text{Var}\left(R(s_i)\right)\)
\[P(|Q_N - E[R(s_i)]| \geq \epsilon) \leq \frac{\text{Var}(R(s_i))}{N \epsilon^2}\]
(Bienayme)
(Chebyshev)
Curse of dimensionality!
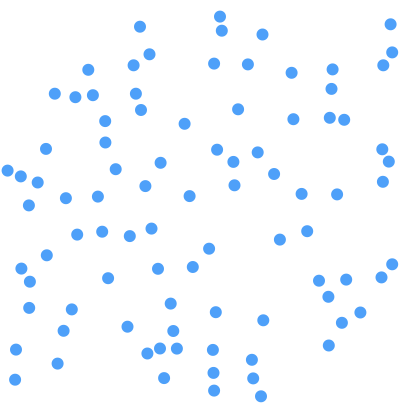
Doesn't depend on size of \(S\)
\[b(s) \approx \sum_{i=1}^N \delta_{s}(s_i)\; w_i\]
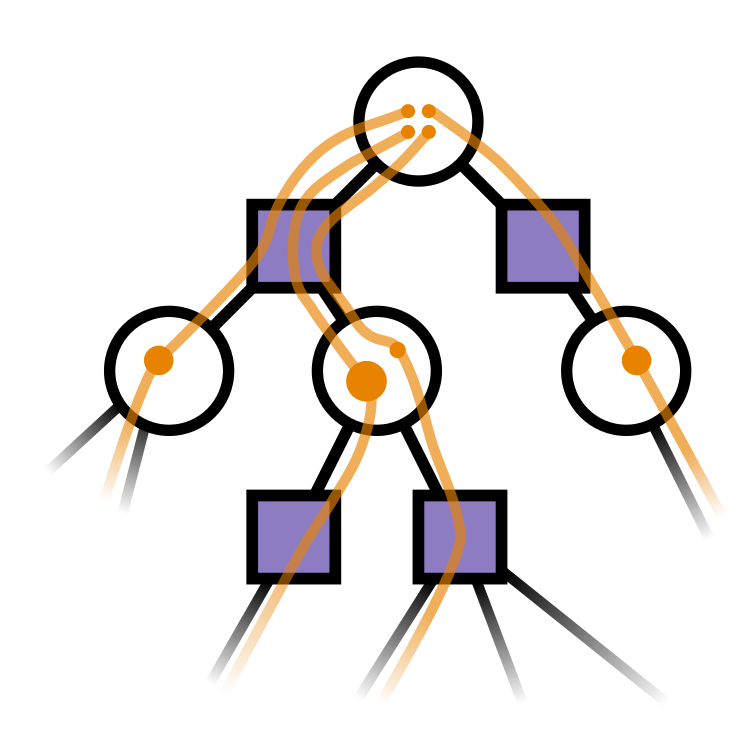
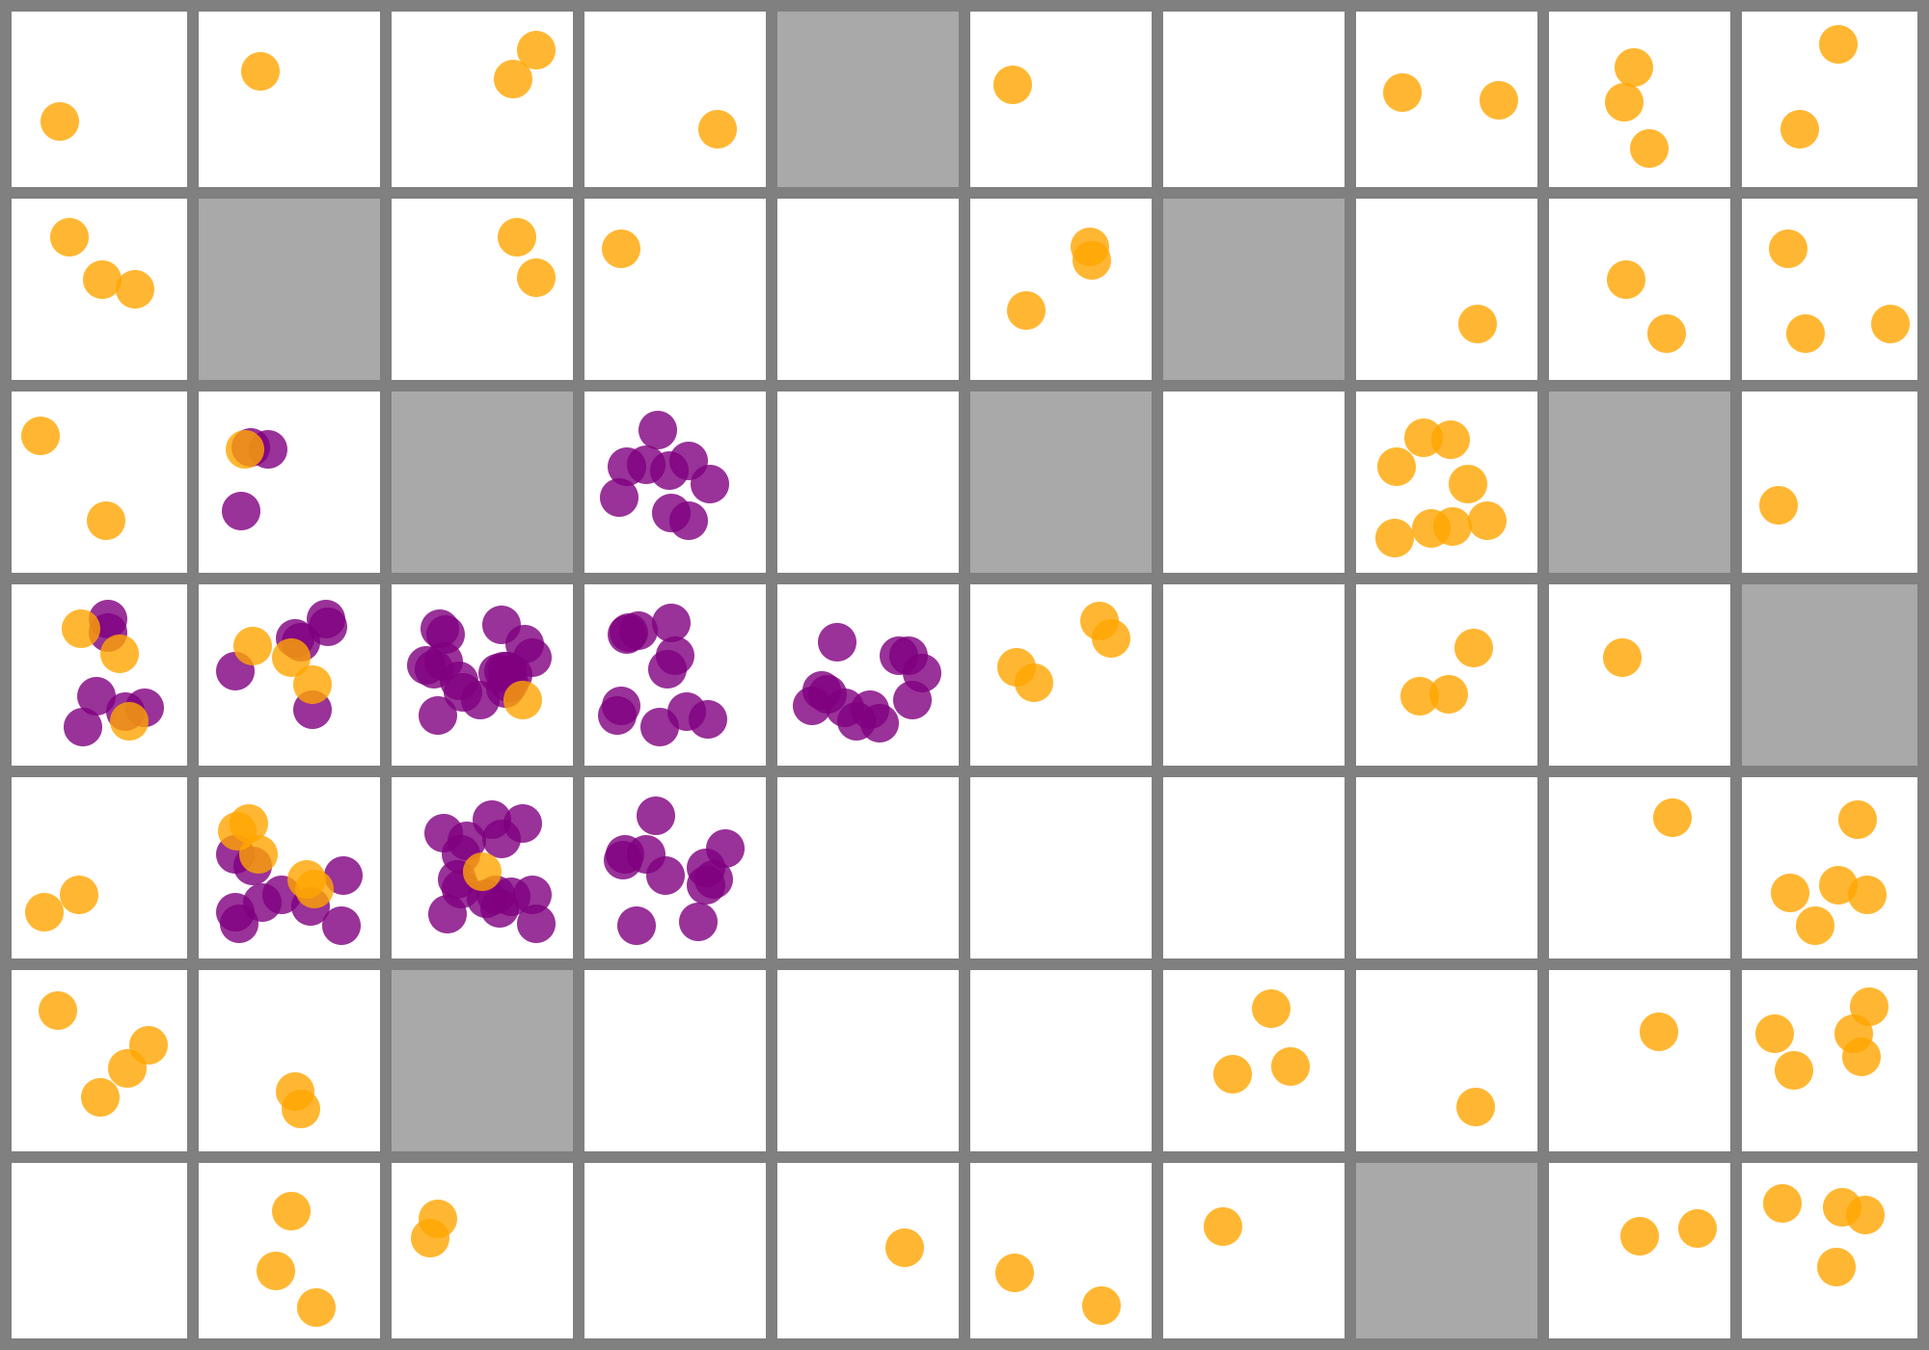
Belief Update:
\(O(|\mathcal{S}|^2) \rightarrow O(N)\)
Can we prove that particle-based POMDP planning is efficient?
Particle filter belief approximation
PF Approximation Accuracy
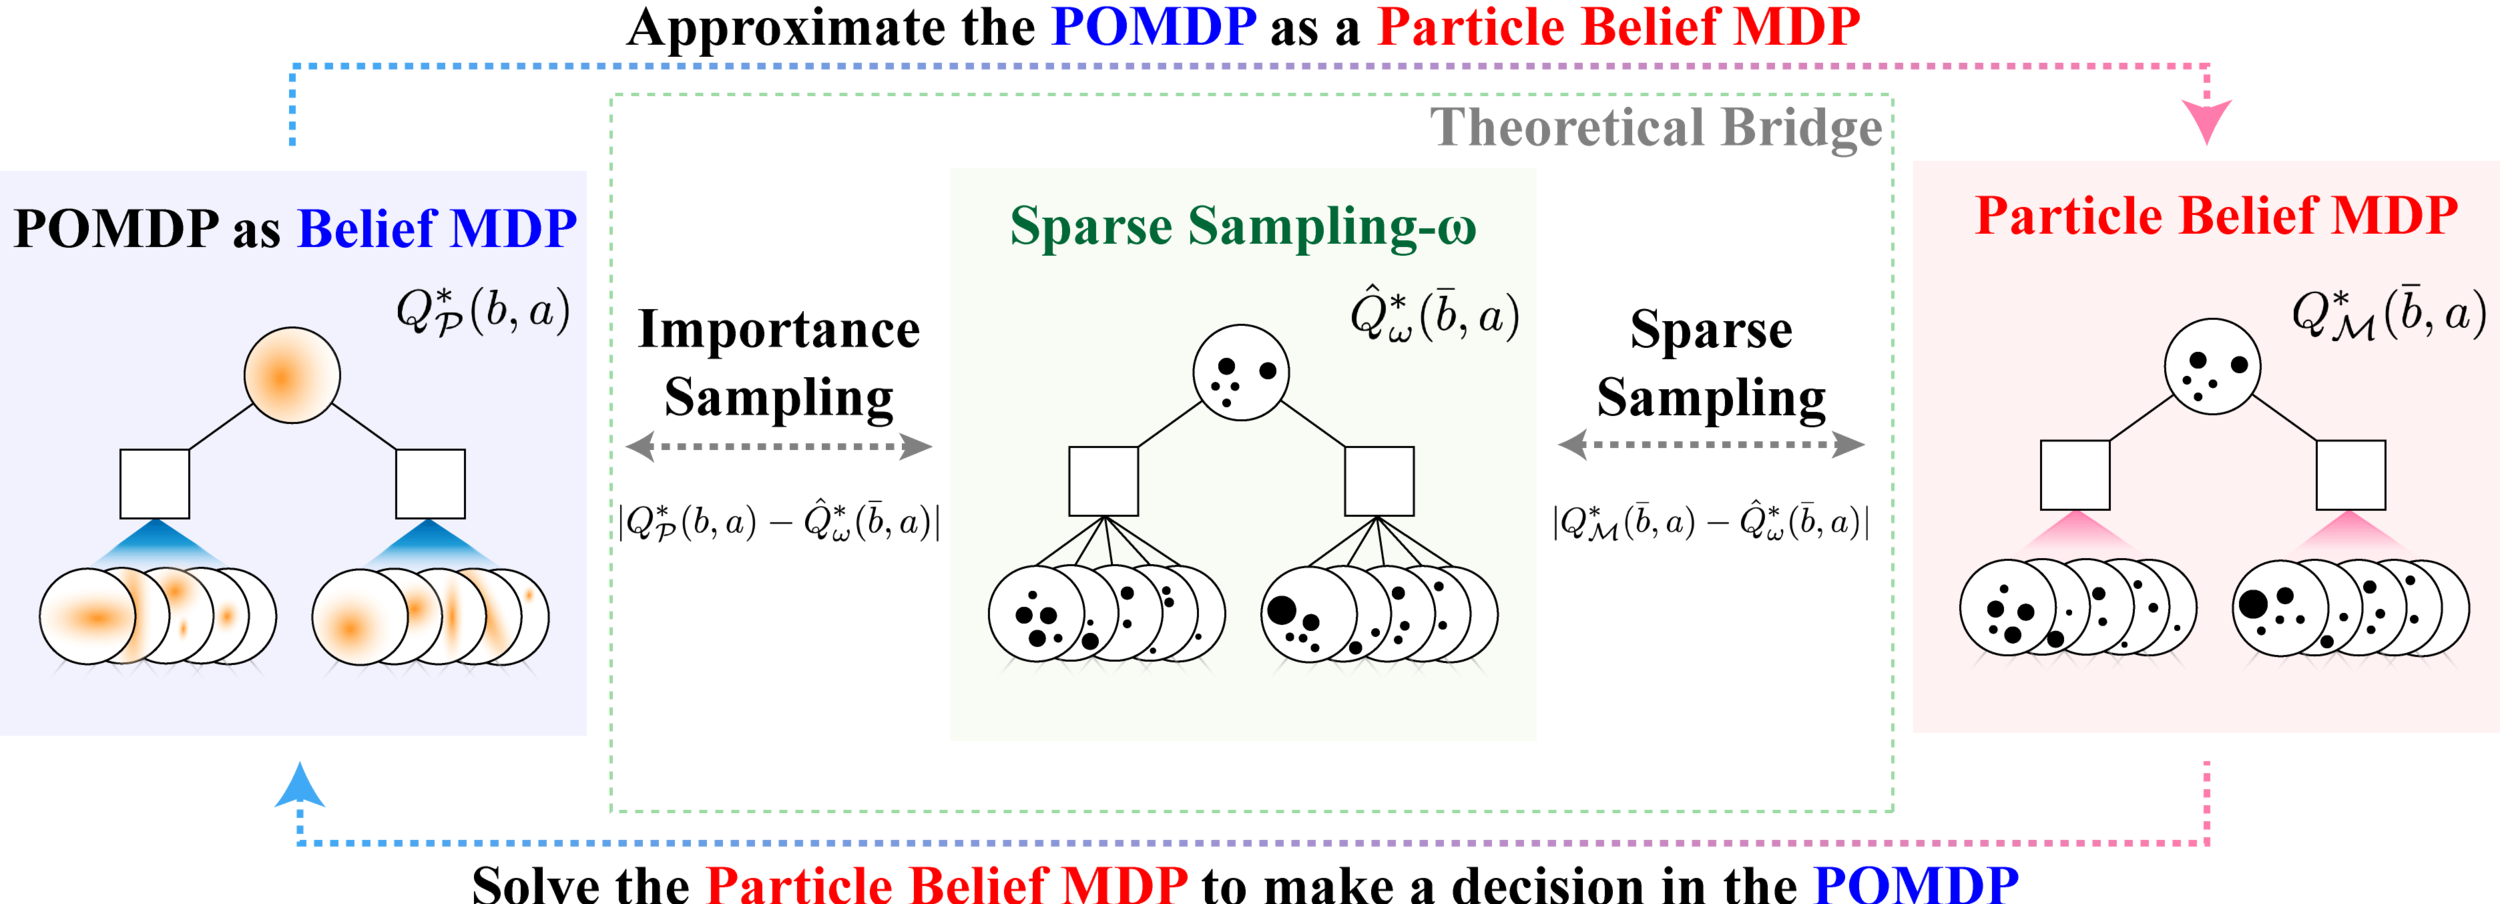
\[|Q_{\mathbf{P}}^*(b,a) - Q_{\mathbf{M}_{\mathbf{P}}}^*(\bar{b},a)| \leq \epsilon \quad \text{w.p. } 1-\delta\]
For any \(\epsilon>0\) and \(\delta>0\), if \(C\) (number of particles) is high enough,
[Lim, Becker, Kochenderfer, Tomlin, & Sunberg, JAIR 2023]
No direct dependence on \(|\mathcal{S}|\) or \(|\mathcal{O}|\)!*
*But this does depend on the Renyi divergence between \(P(s_t \mid s_0, a_{1:t-t})\) and \(P(s_t \mid s_0, a_{0:t-1}, o_{1:t})\), which Nisar and Jiho have noted can grow exponentially.

Why are POMDPs difficult?
- Curse of History
- Curse of dimensionality
- State space
- Observation space
- Action space
Tree size: \(O\left(\left(|A||O|\right)^D\right)\)
How far can we get with this?
Example: Navigation among pedestrians
Conventional
(Pedestrian most likely path)
Ours
(POMDP)
[Gupta, Hayes, & Sunberg, AAMAS 2022]
Average: 92 seconds
Average: 65 seconds
State:
- Vehicle physical state
- Human physical state
- Human intention

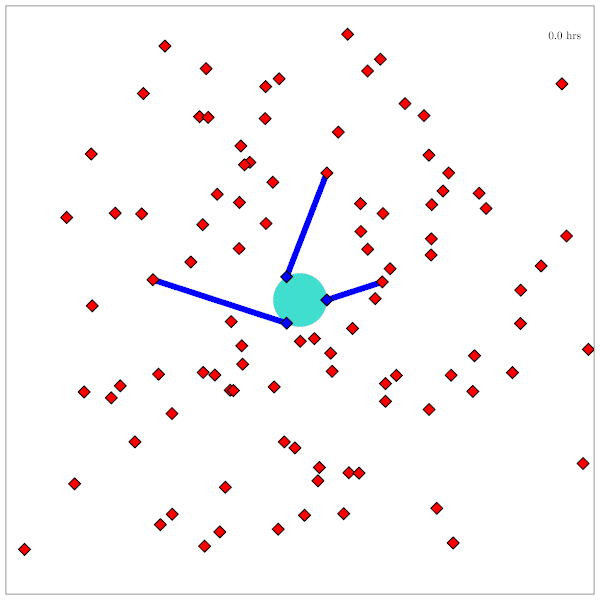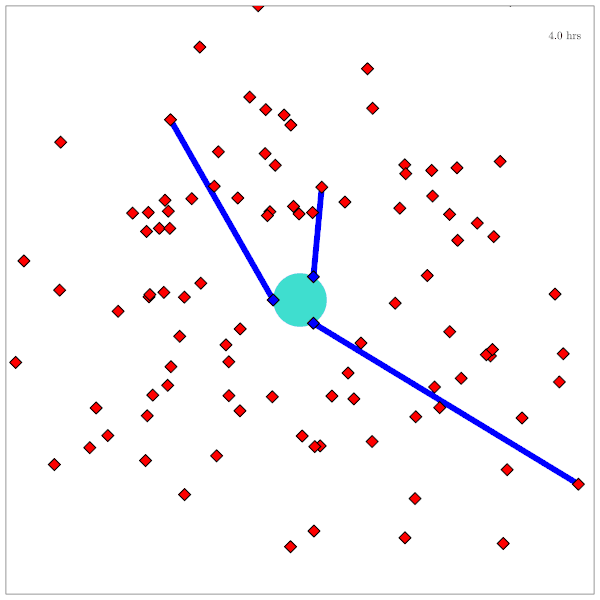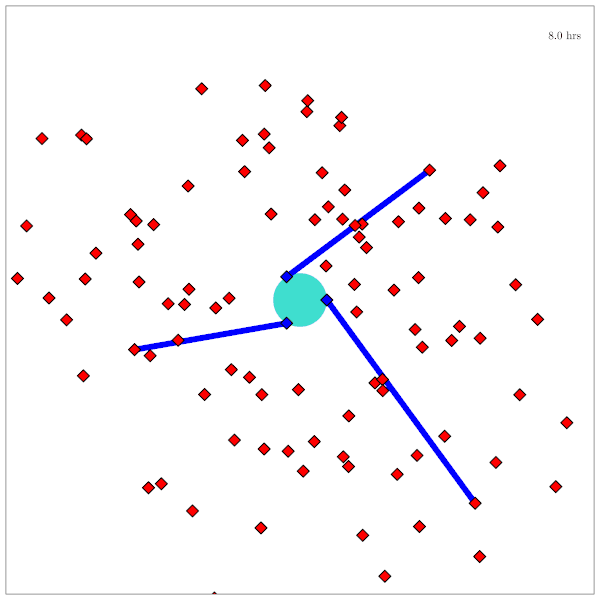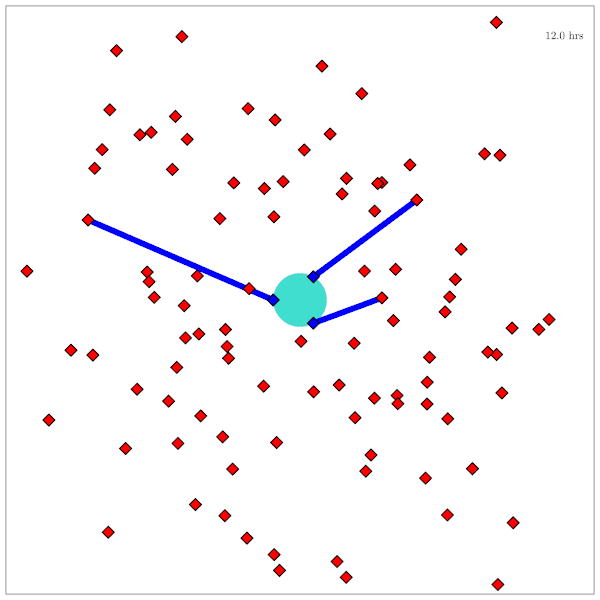
Example: Search
State:
- Vehicle physical state
- Human physical state
- Human intention
- Target physical state
[Gupta, et al. IROS 2026]
Same POMDP planner can be used with minor changes!
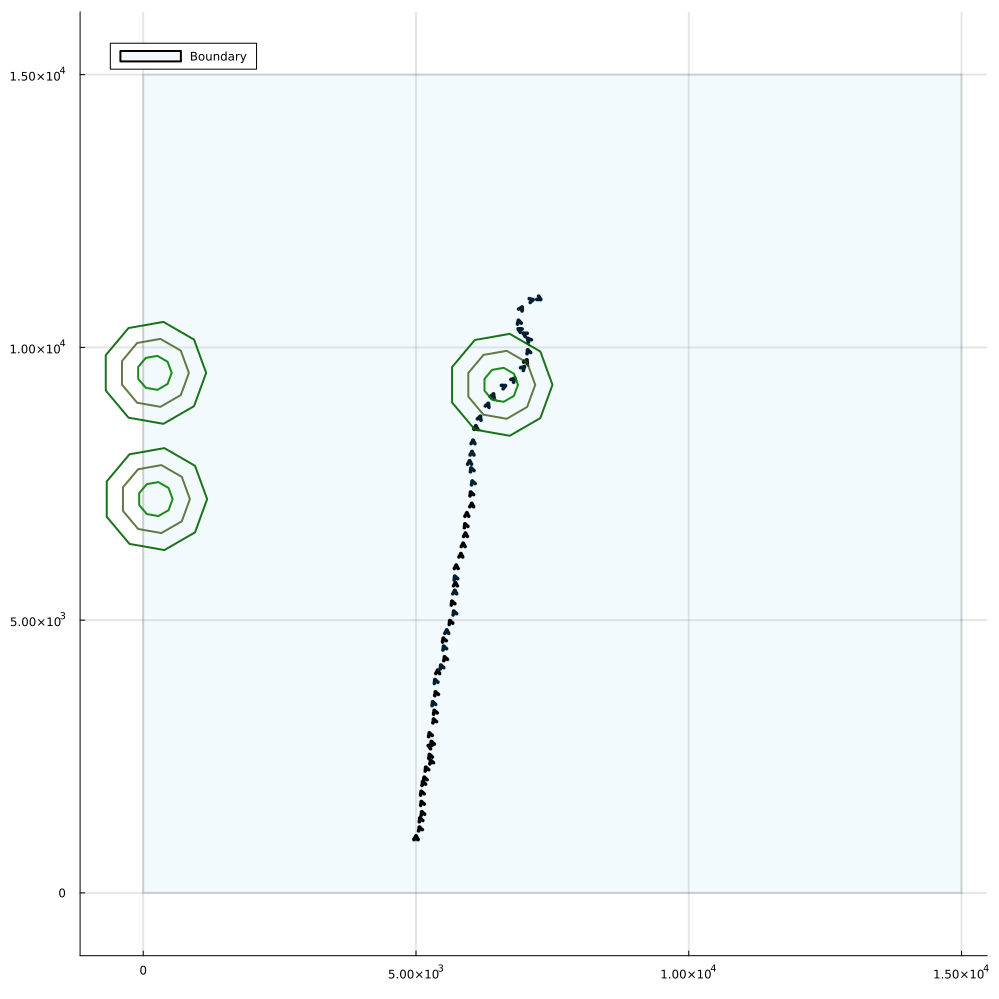
Example: Weather Science

[Moncton, Gupta, Sunberg, Frew, DDDAS 2024]
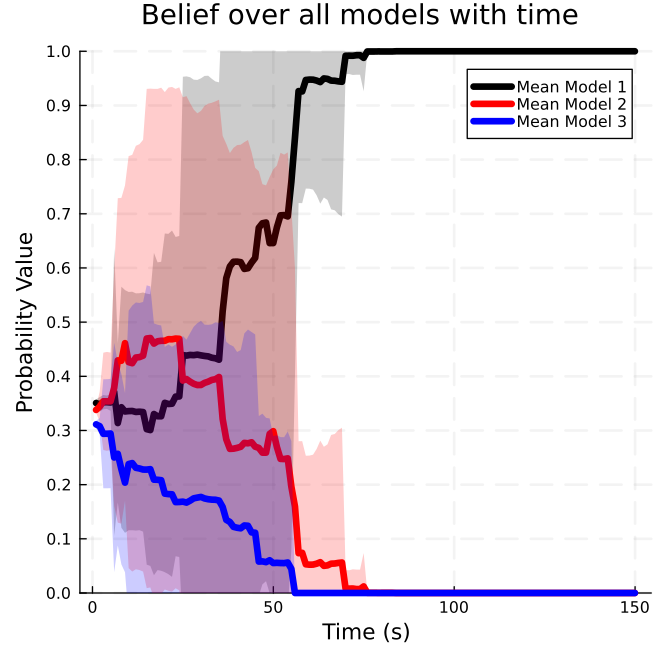
(Result for simplified dynamical system)
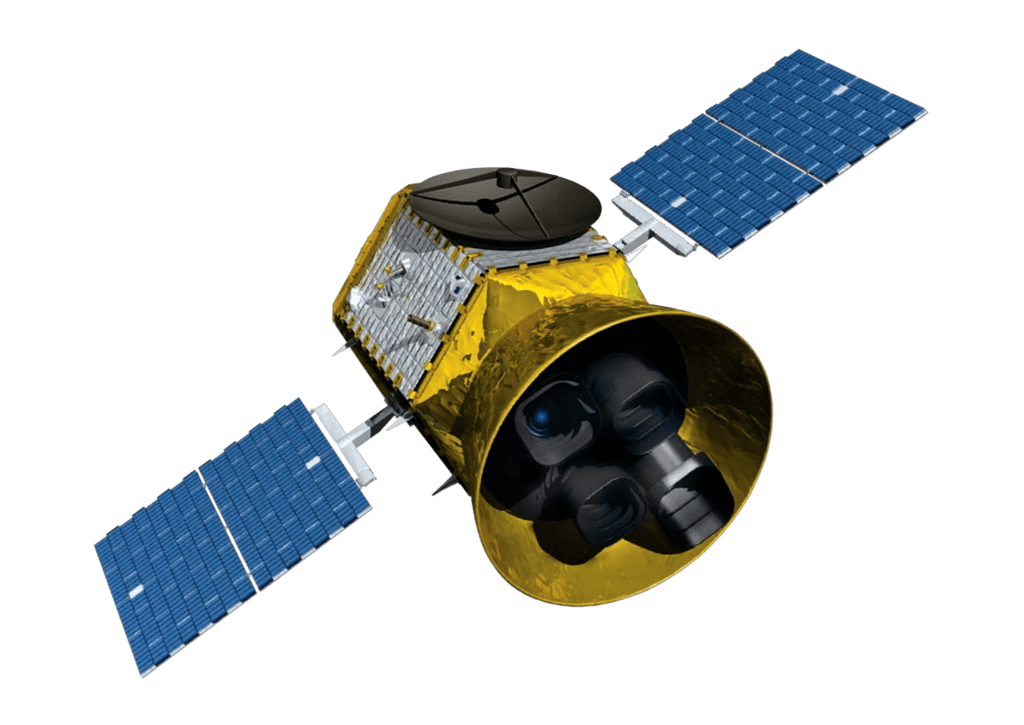
State:
- Position, velocity of object-of-interest
- Anomalies: navigation failure, suspicious maneuver, thruster failure, etc.
Innovation: Large language models allow analysts to quickly specify anomaly hypotheses
Catalog Maintenance Plan
Example: Space Domain Awareness
[Dagan et al., AAMAS 2025, AMOS 2025]
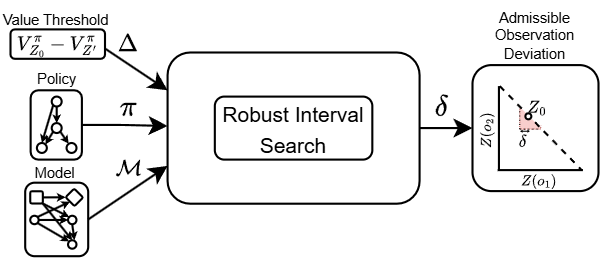
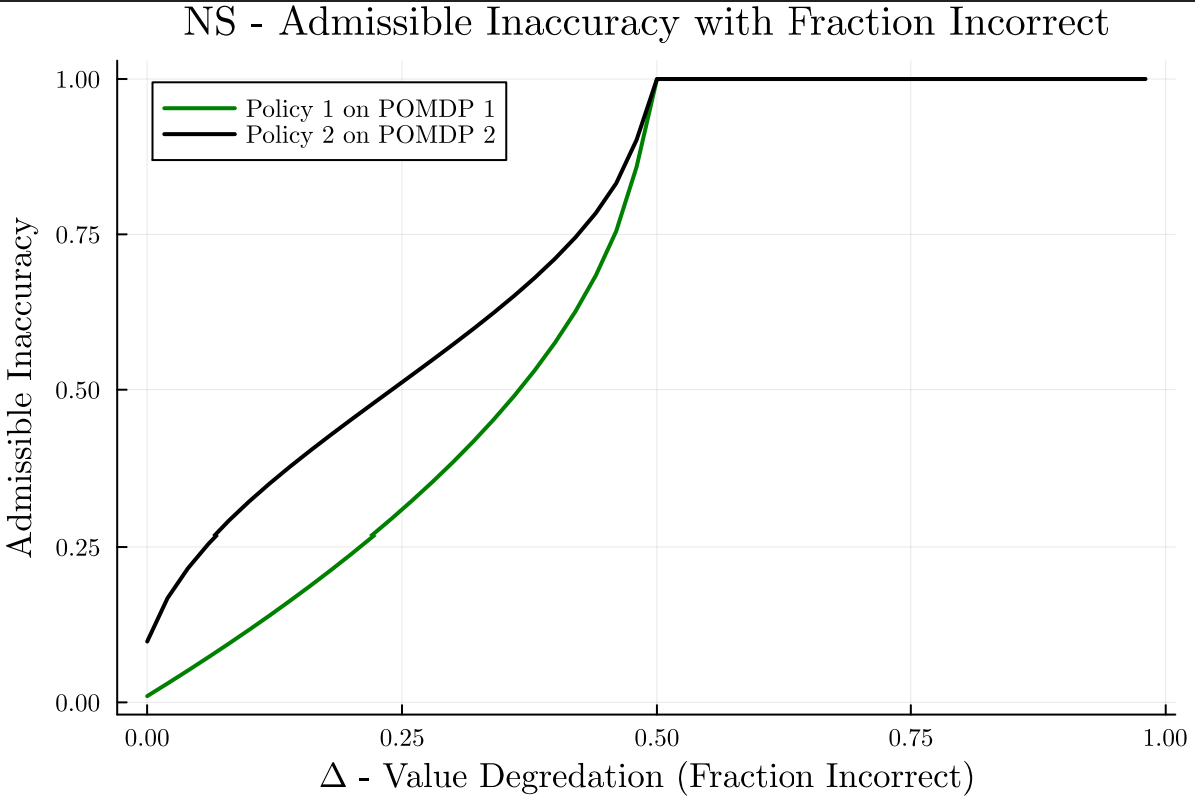
Observation robustness, \(\delta\)
Admissible Performance Decrease, \(\Delta\)
What if models are inaccurate?
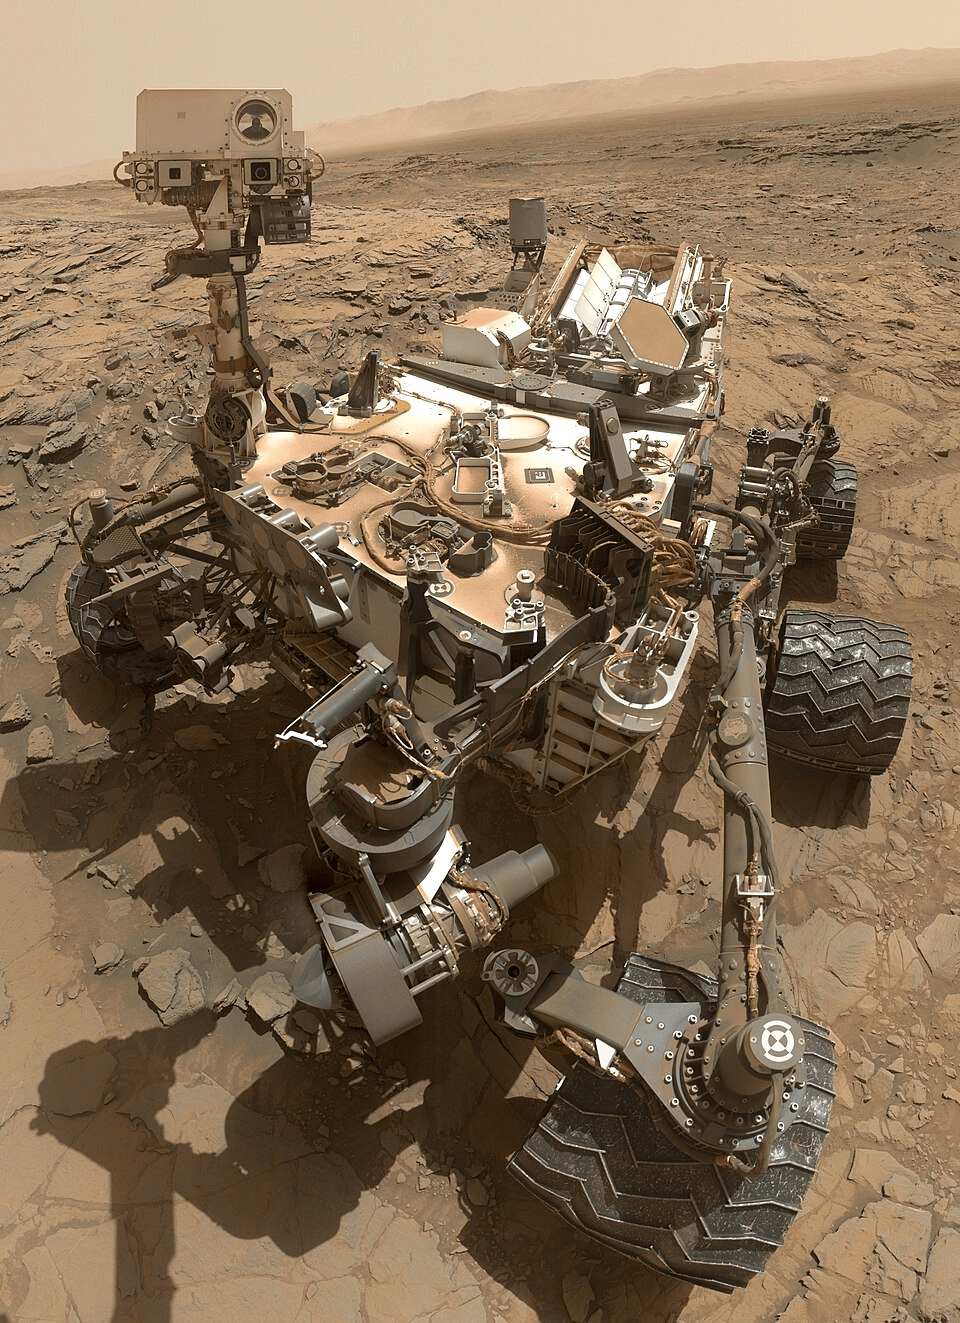
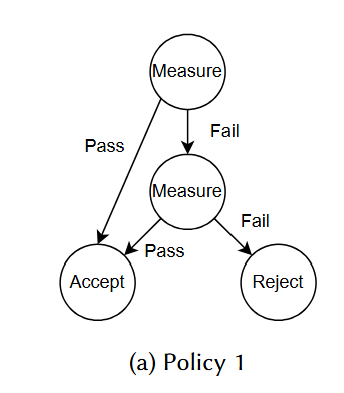
Measure Once
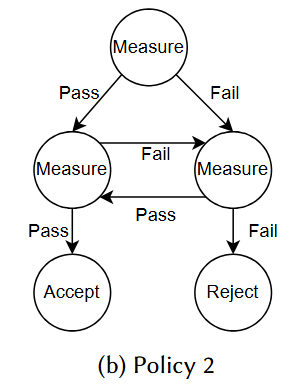
Measure Twice
Miscalibrated instrument


[Kraske et al. JAIR (Under Review)]
Single-Agent POMPDs
Motivating Applications
Multi-Agent Games
Autonomy and People
Open Questions
Multi-Agent Games
Autonomy and People
Open Questions
Motivating Applications
Single-Agent POMPDs
A Mathematical Model: The POMDP
(Partially Observable Markov Decision Process)
state observation decision reward
\(m_{t}\)
\(o_{t}\)
\(a_{t}\)
\(s_{t}\)
\(r_{t}\)
\(m_{t+1}\)
\(o_{t+1}\)
\(a_{t+1}\)
\(s_{t+1}\)
\(r_{t+1}\)
\(\cdots\)
\(\cdots\)
step t
step t+1
\(m_{t}\)
\(o_{t}\)
\(a_{t}\)
\(s_{t}\)
\(r_{t}\)
\(m_{t+1}\)
\(o_{t+1}\)
\(a_{t+1}\)
\(s_{t+1}\)
\(r_{t+1}\)
\(\cdots\)
\(\cdots\)
step t
step t+1
State: \(s_t \in \mathcal{S}\)
Action: \(a_t \in \mathcal{A}\)
Observation: \(o_t \in \mathcal{O}\)
Transition Distribution: \(T(s_{t+1} \mid s_t, a_t)\)
Observation Distribution: \(Z(o_{t} \mid s_{t})\)
Reward Function: \(r_t = R(s_t, a_t)\)
Memory: \(m_t\)
A Mathematical Model: The POSG
(Partially Observable Stochastic Game / Partially Observable Markov Game)
state observation decision reward
Agents: \(i \in \mathcal{I}\)
Each agent \(i\) has
Completely Changes Solutions!
\(m^{i}_{t}\)
\(o^{i}_{t}\)
\(a^{i}_{t}\)
\(r^{i}_{t}\)
\(s_{t}\)
\(m^{i}_{t+1}\)
\(o^{i}_{t+1}\)
\(a^{i}_{t+1}\)
\(r^{i}_{t+1}\)
\(s_{t+1}\)
\(\cdots\)
\(\cdots\)
step t
step t+1
\(o^{i}_{t}\)
\(m^{i}_{t}\)
\(a^{i}_{t}\)
\(r^{i}_{t}\)
Example: Naval Defense
A Blue USV defends a storage facility from a recently-observed Red attacker
Estimators Can Be Exploited
A Blue USV defends a storage facility from a recently-observed Red attacker
- Blue uses a Bayesian intent estimator
- This involves assumptions about Red
- Blue’s control architecture:
- POMDPs and all of my other work before 2024!
Estimators Can Be Exploited
A Blue USV defends a storage facility from a recently-observed Red attacker
- Blue uses a Bayesian intent estimator
- This involves assumptions about Red
- Blue commits to the best action given the estimate
Estimators Can Be Exploited
A Blue USV defends a storage facility from a recently-observed Red attacker
- Blue uses a Bayesian intent estimator
- This involves assumptions about Red
- Blue commits to the best action given the estimate
- 90% predicted success rate
Estimators Can Be Exploited
A Blue USV defends a storage facility from a recently-observed Red attacker
- Blue uses a Bayesian intent estimator
- This involves assumptions about Red
- Blue commits to the best action given the estimate
- If Red knows Blue’s estimator, Red can exploit it
Result: Blue’s success rate is 0% because Red deceived the estimator
- 90% predicted success rate
Game Theoretic Approach
A Blue USV defends a storage facility from a recently-observed Red attacker
- How can we model this bluffing mathematically?
Game Theoretic Approach
A Blue USV defends a storage facility from a recently-observed Red attacker
- How can we model this bluffing mathematically?
Game Theoretic Approach
A Blue USV defends a storage facility from a recently-observed Red attacker
- How can we model this bluffing mathematically?
- The Nash equilibrium is 50-50 for both agents.
Game Theoretic Approach
A Blue USV defends a storage facility from a recently-observed Red attacker
- How can we model this bluffing mathematically?
- The Nash equilibrium is 50-50 for both agents.
Result: Blue’s success rate is 50%
Game Theoretic Approach
A Blue USV defends a storage facility from a recently-observed Red attacker
- How can we model this bluffing mathematically?
- The Nash equilibrium is 50-50 for both agents.
Result: Blue’s success rate is 50%
Or, if Red cannot tolerate a 50% failure rate, they will be deterred!
Mixed policies for (fully observable) Markov Games
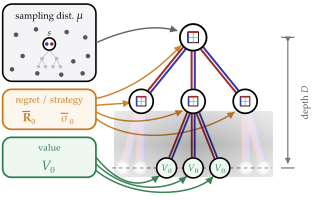
\underbrace{\|V_K-V^*\|_{p,\mu}}_{\text{Final Value Error}}
\le
\rho^K\underbrace{\|V_0-V^*\|_{p,\mu}}_{\text{Initial Value Error}}
+
\frac{1-\rho^K}{1-\rho}
\left(
\varepsilon_{\mathrm{mg}}
+
\varepsilon_{\mathrm{fit}}
\right)
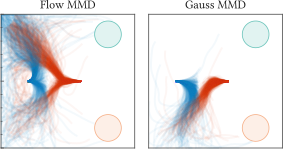
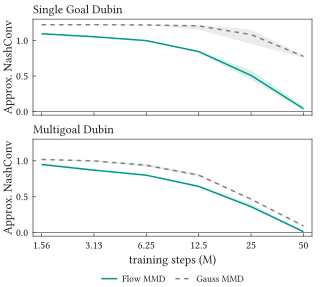
Simultaneous AlphaZero
Flow-Matching Magnetic Mirror Descent
[Becker & Sunberg, AAAI (Under Review)]
[Becker & Sunberg, AAMAS (Under Review)]

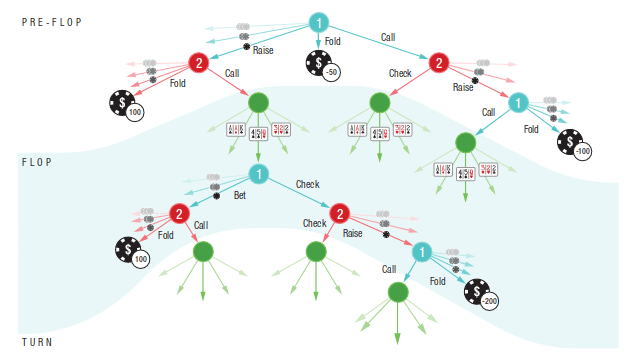
What about partial observability?
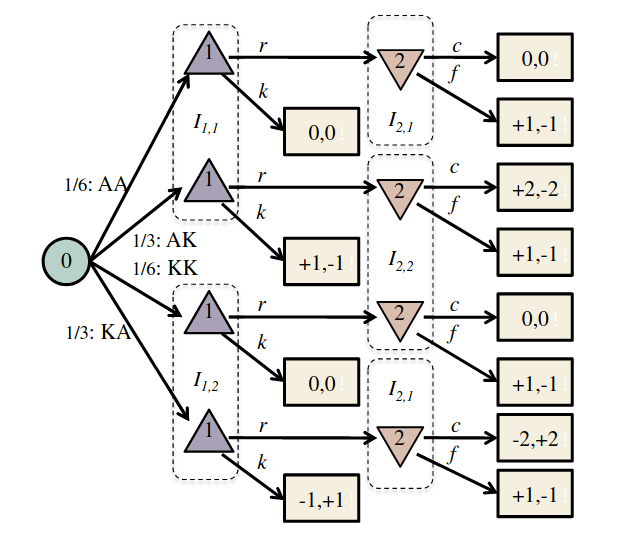
Image: Russel & Norvig, AI, a modern approach
P1: A
P1: K
P2: A
P2: A
P2: K
Instead of Beliefs, Information Sets
Tree Search Algorithms for POSGs
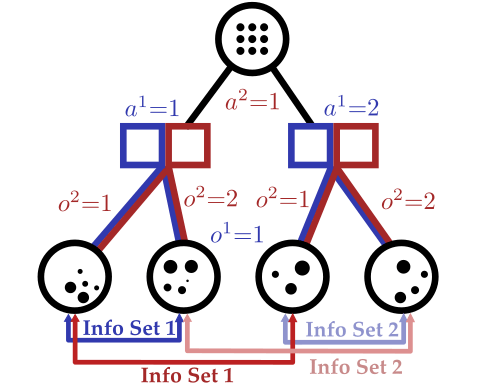
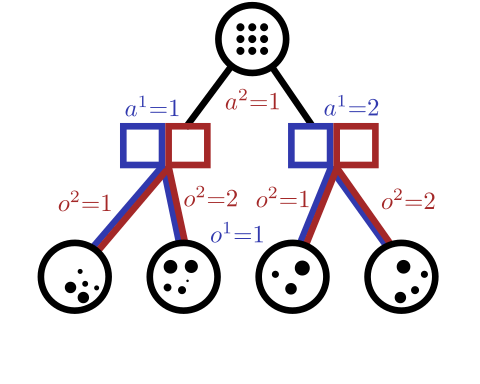
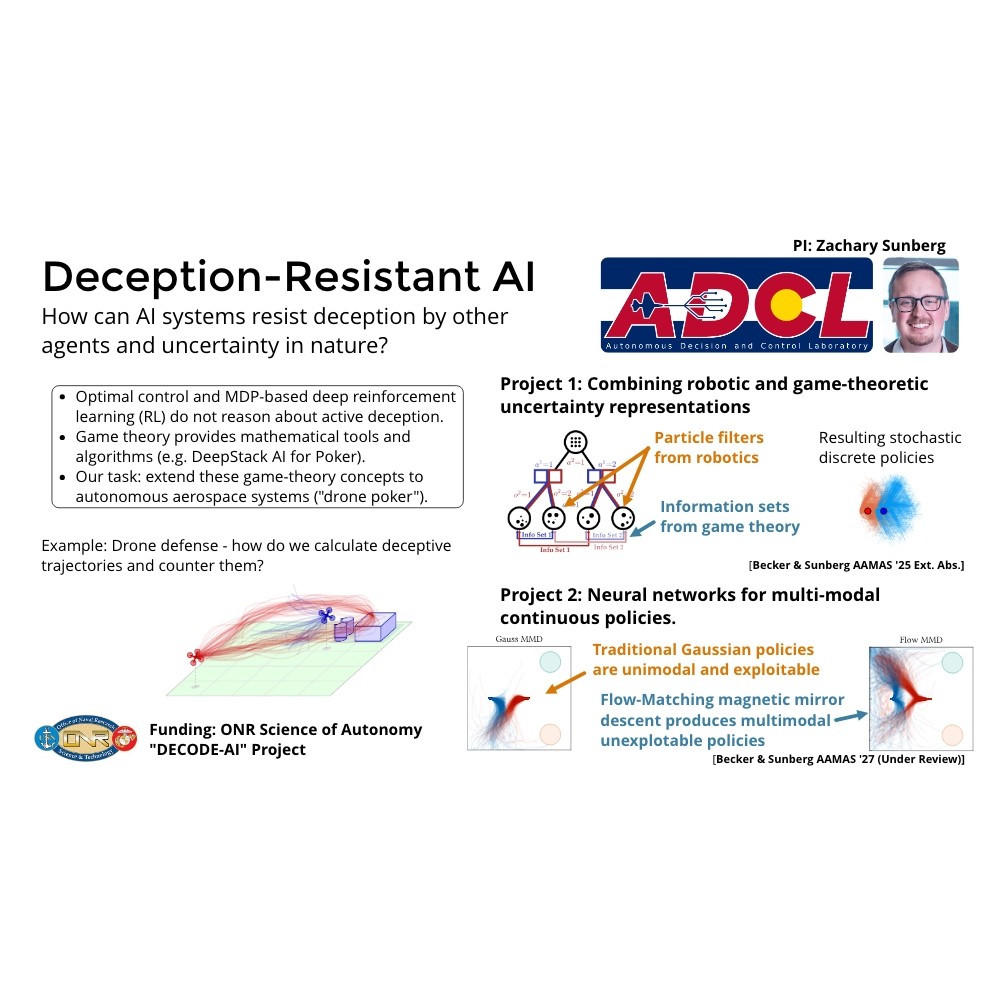
[Becker & Sunberg, AAMAS 25 (Ext. Abs.)]
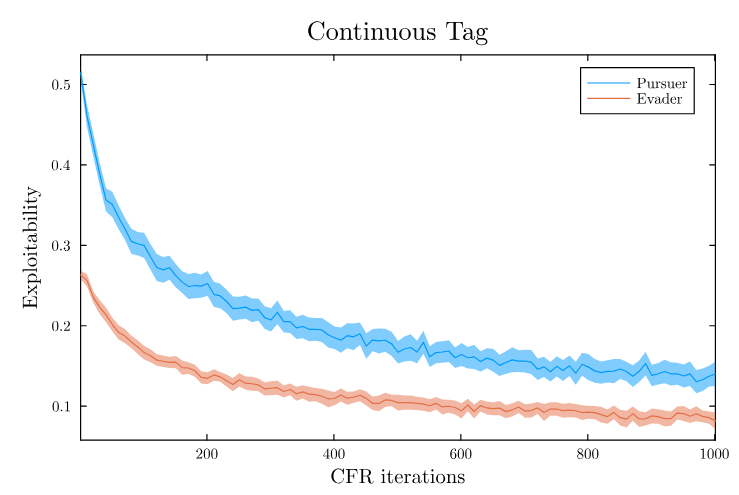
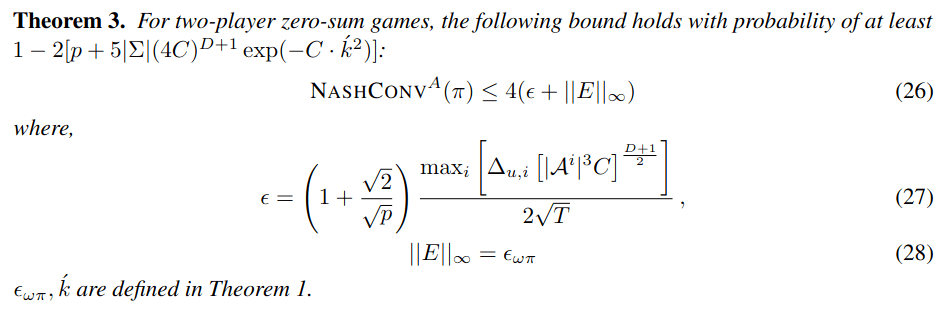
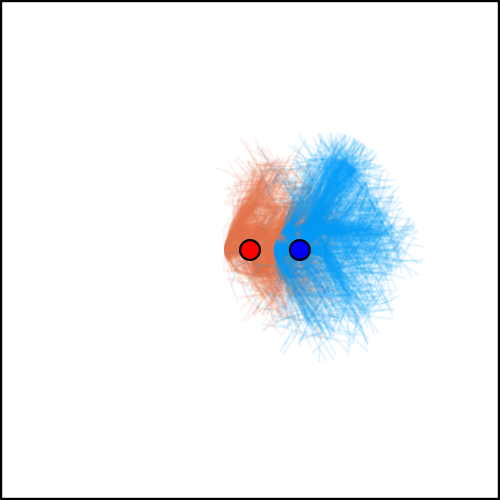
Transforming Decision Networks
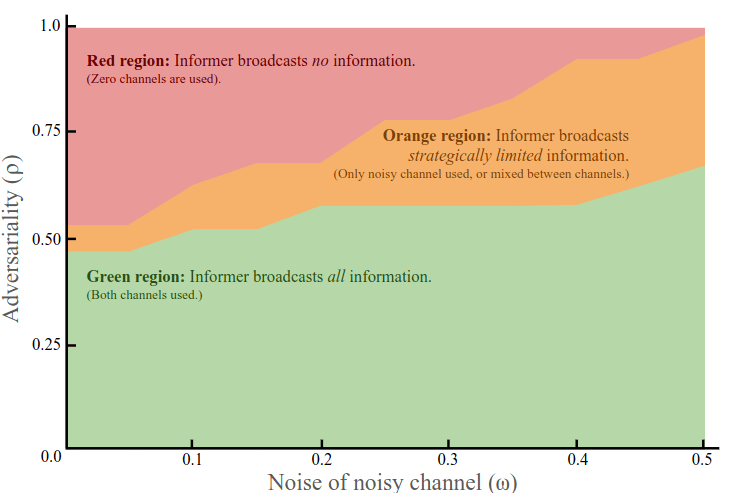
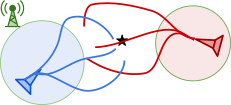
Biased Broadcast Game

[Krusniak & Sunberg, AAMAS (Under Review)]
Reasoning about games often involves transforming into a simpler problem, e.g. finding a best response by "egoizing" to a single-agent problem.
Transforming Decision Networks
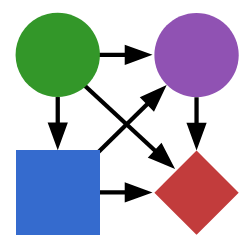
Decisions.jl
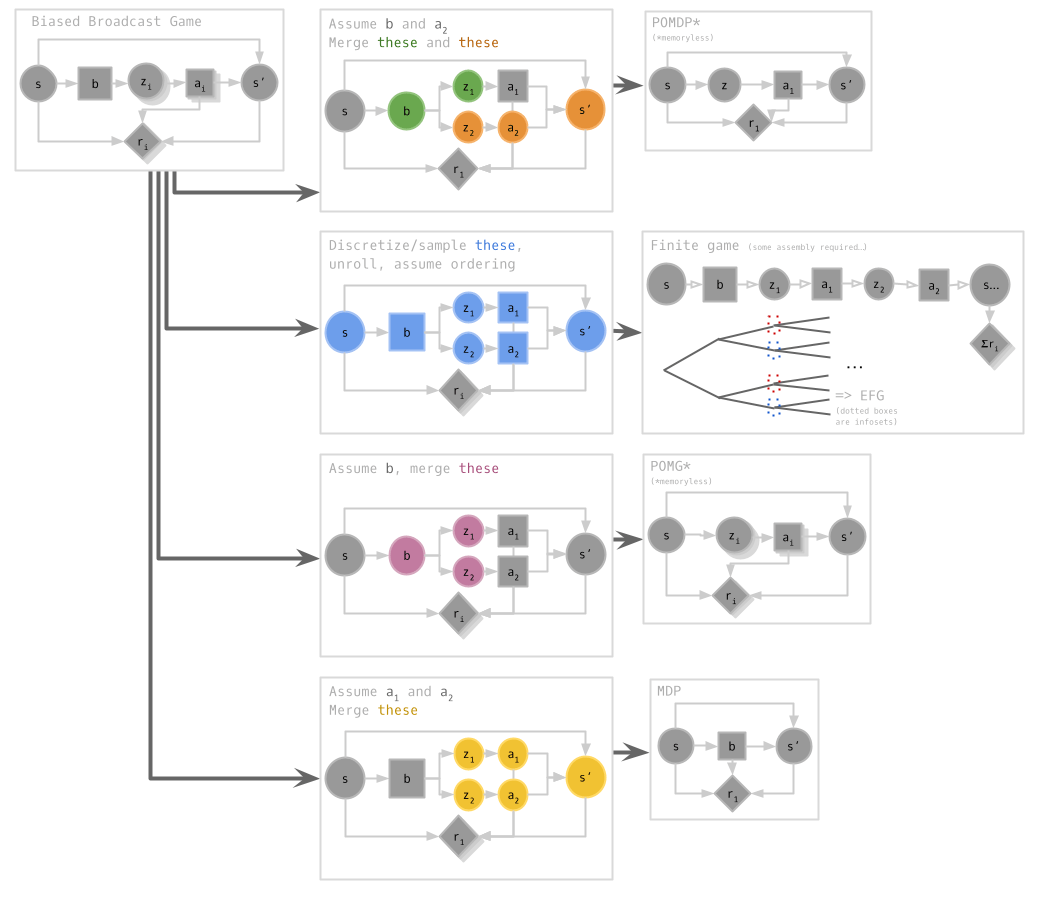
Biased Broadcast Game
POMDP
Extensive-Form Game
POSG
MDP
[Krusniak & Sunberg, AAMAS (Under Review)]
Multi-Agent Games
Motivating Applications
Single-Agent POMPDs
Autonomy and People
Open Questions
Autonomy and People
Motivating Applications
Single-Agent POMPDs
Multi-Agent Games
Open Questions
SAFARI: Search Autonomy For Aerial Robotic Intelligence
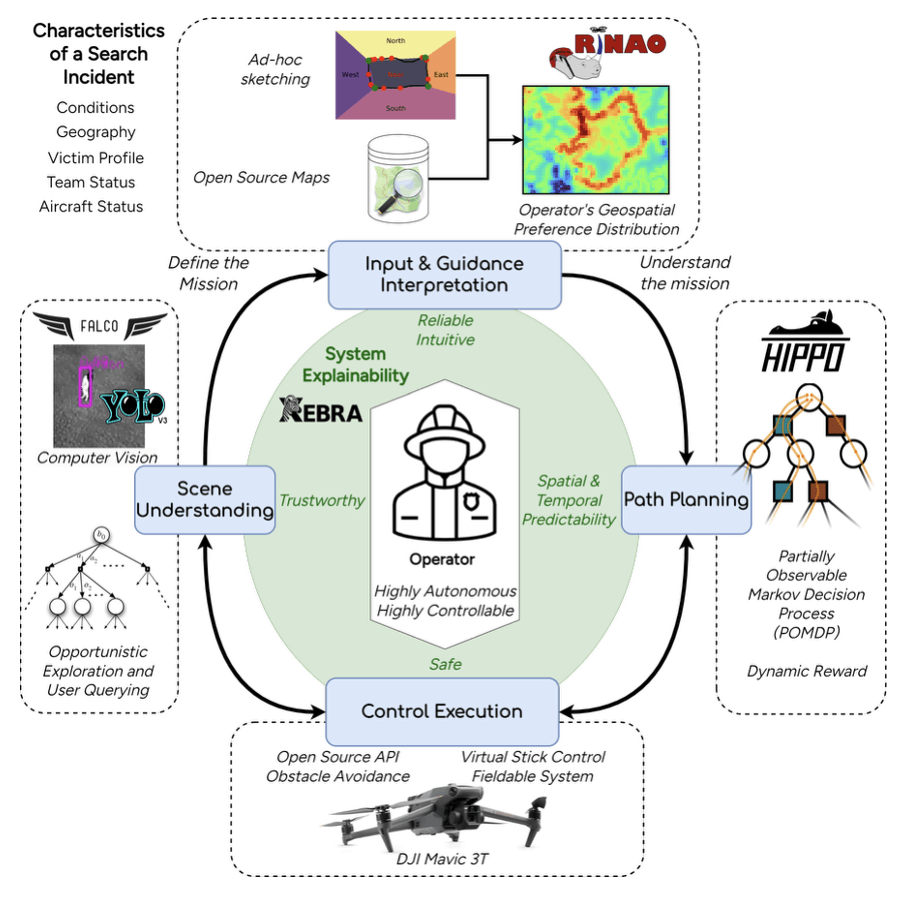
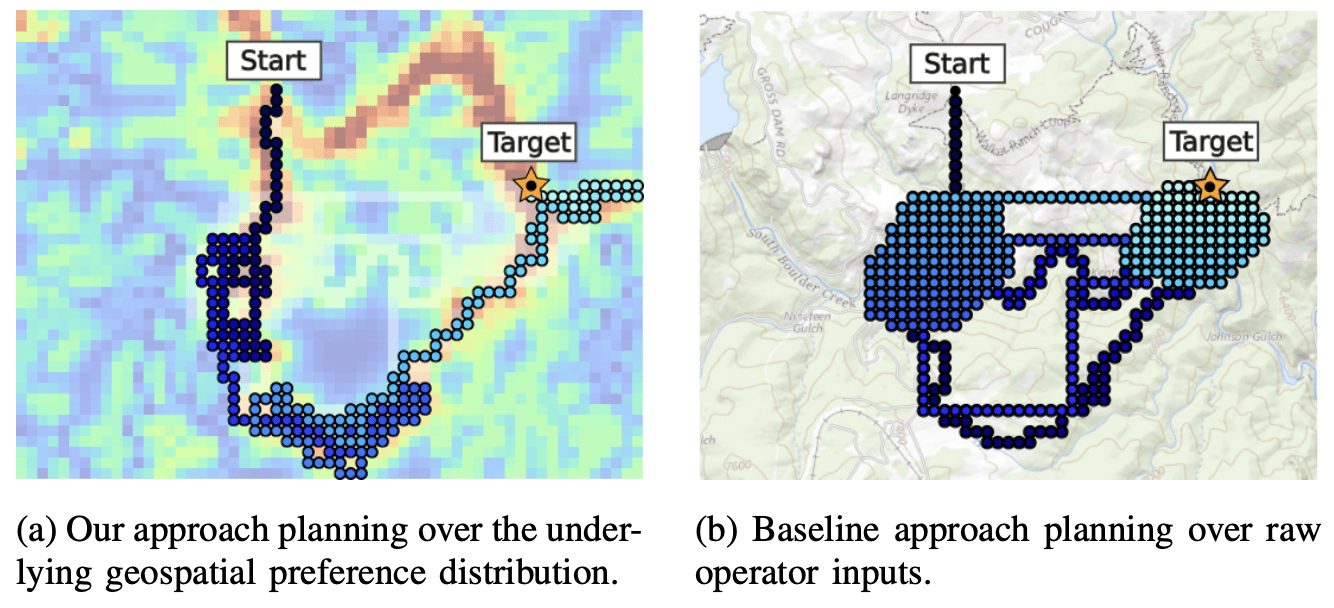
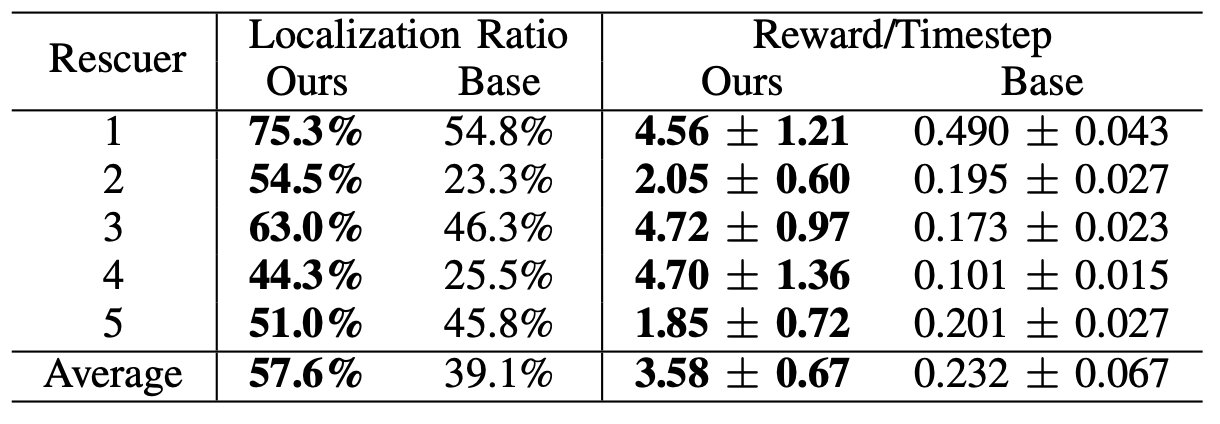
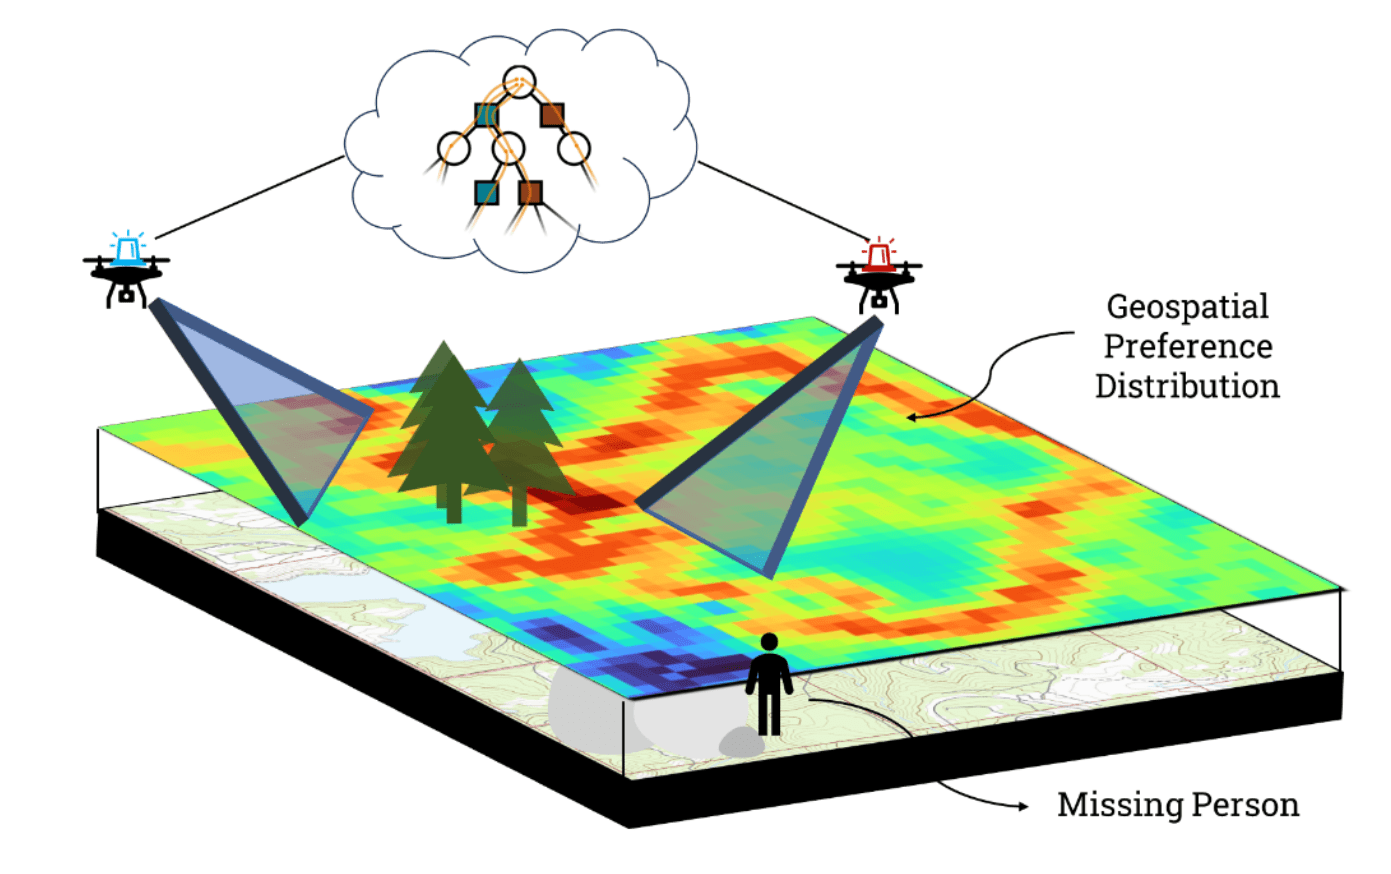


[Ray* & Laouar* et al., ICRA 2024]
SAFARI - Field Testing
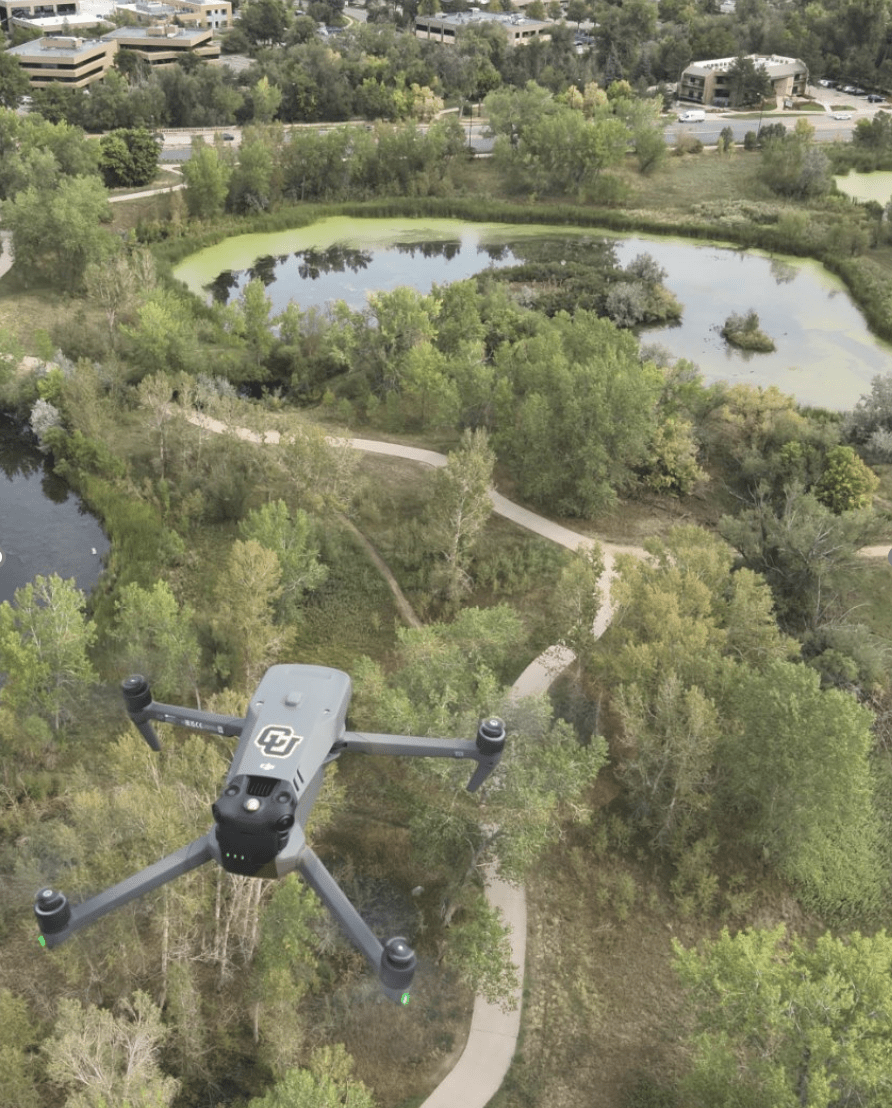
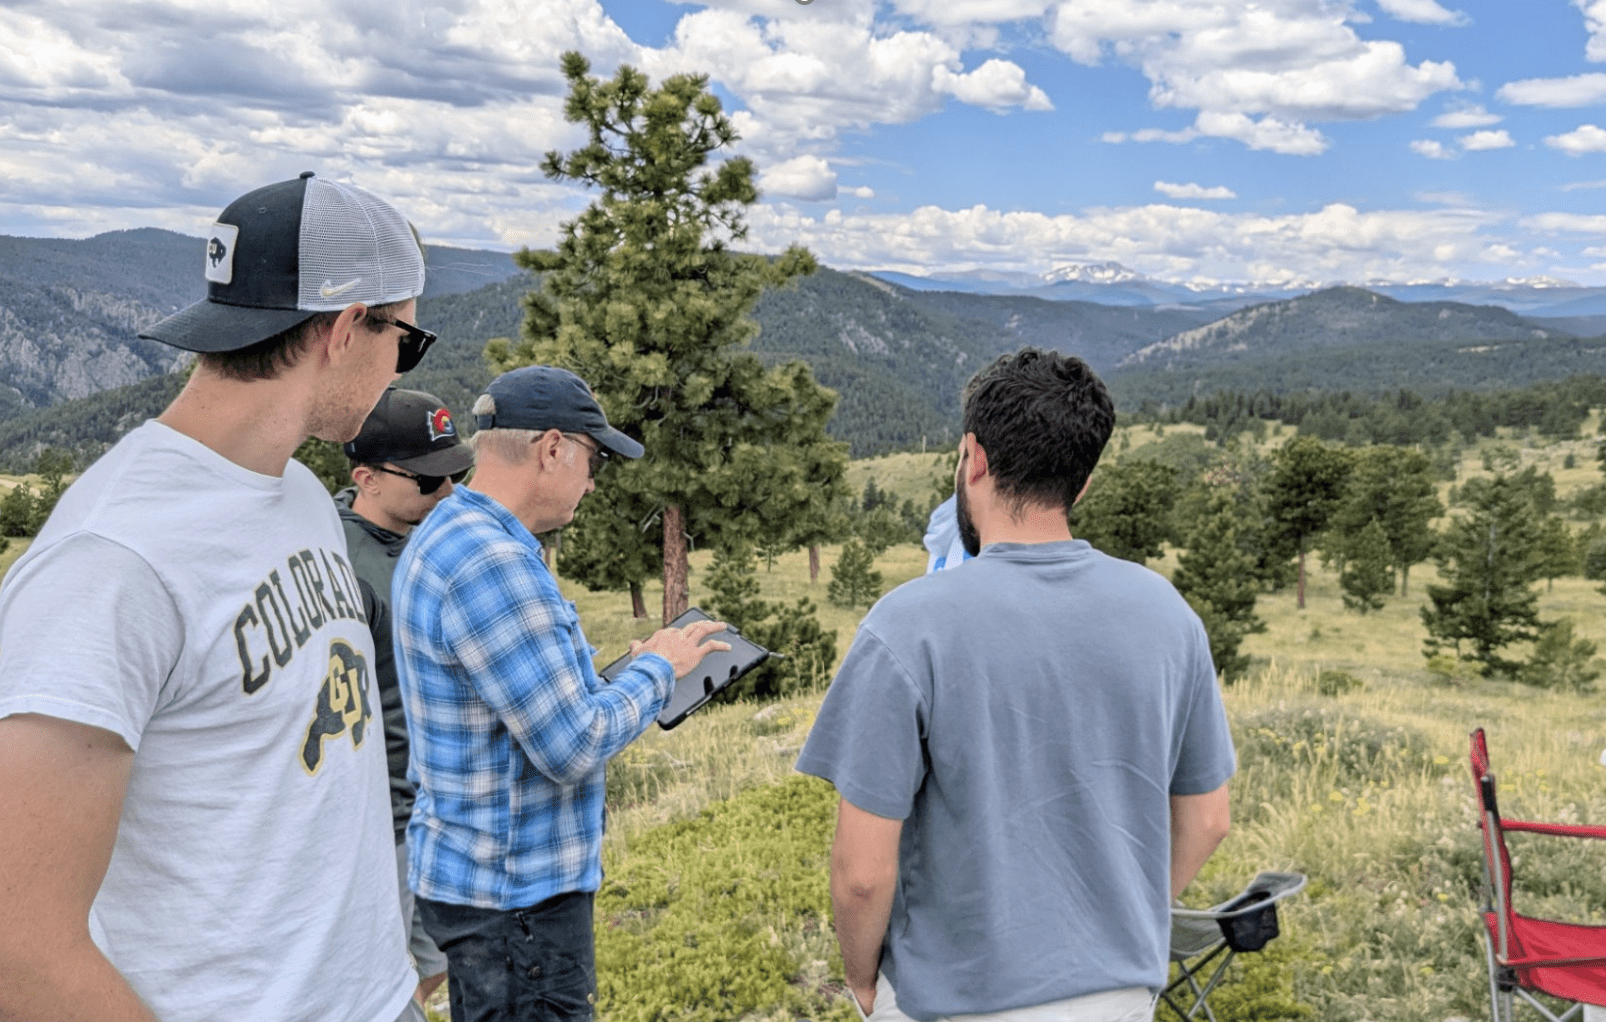
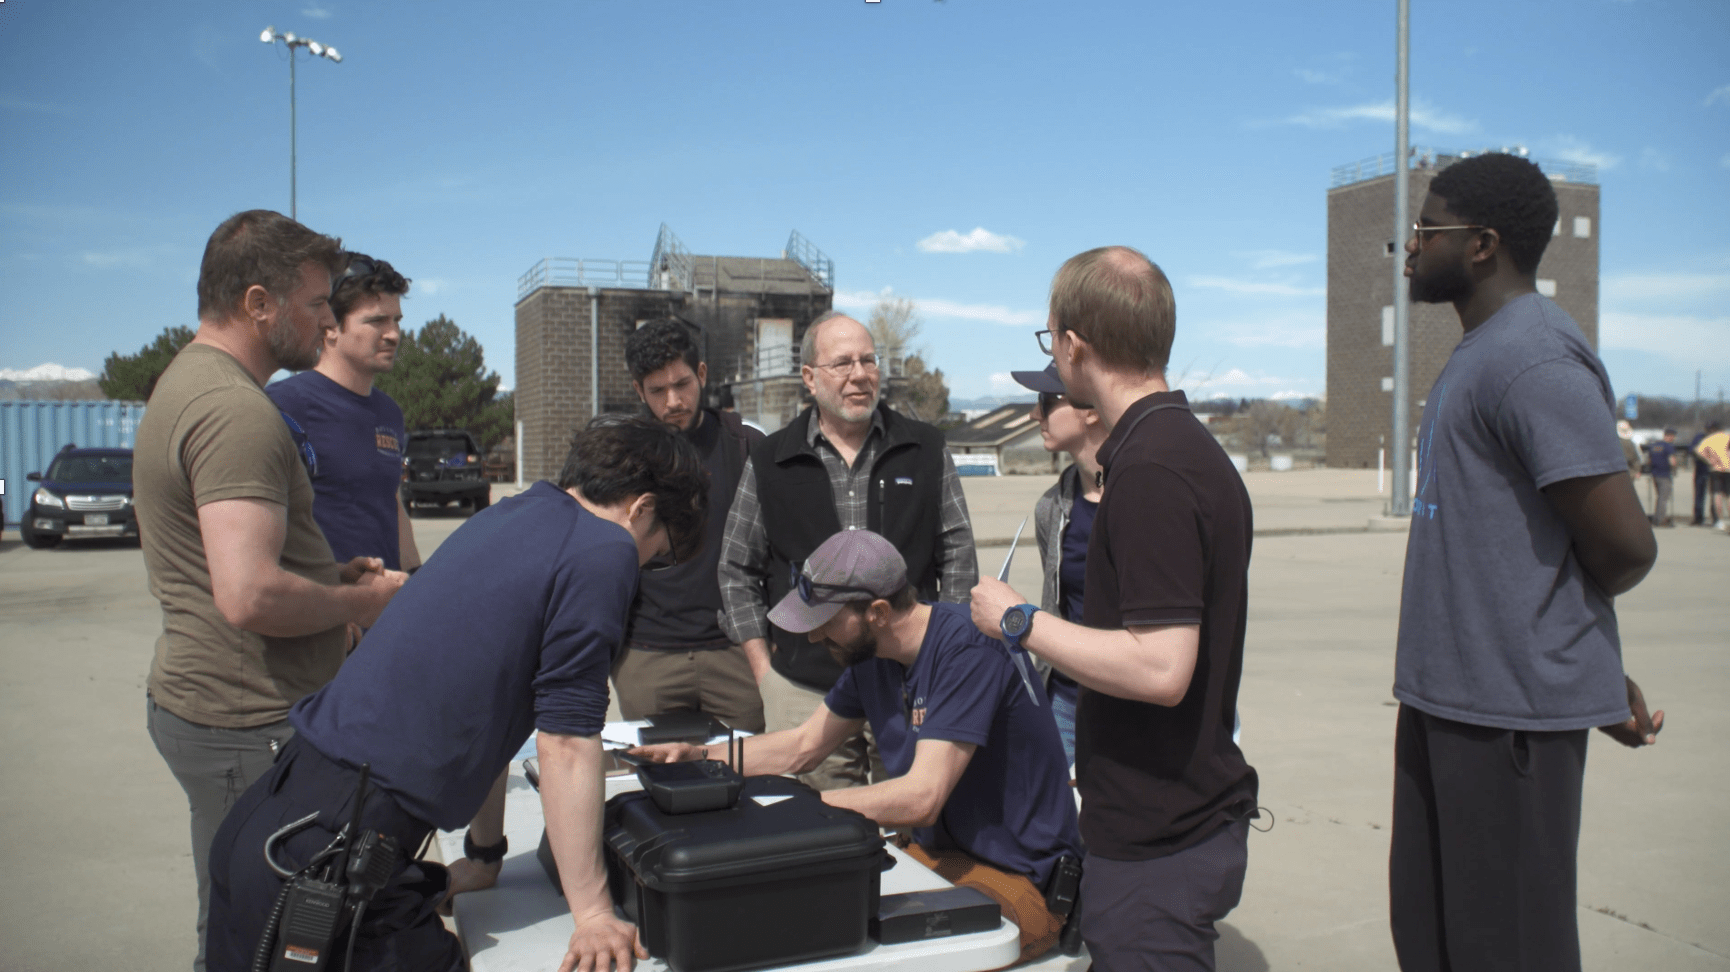
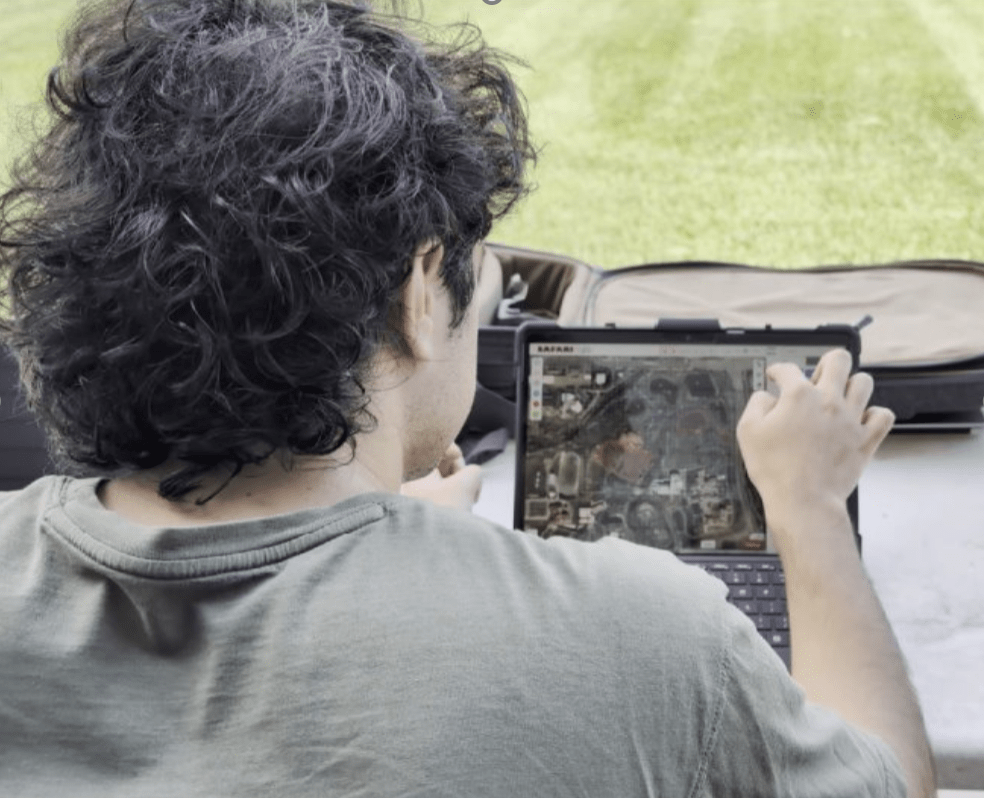
[Ray* & Laouar* et al., ICRA 2024]
Trust Stabilization Models
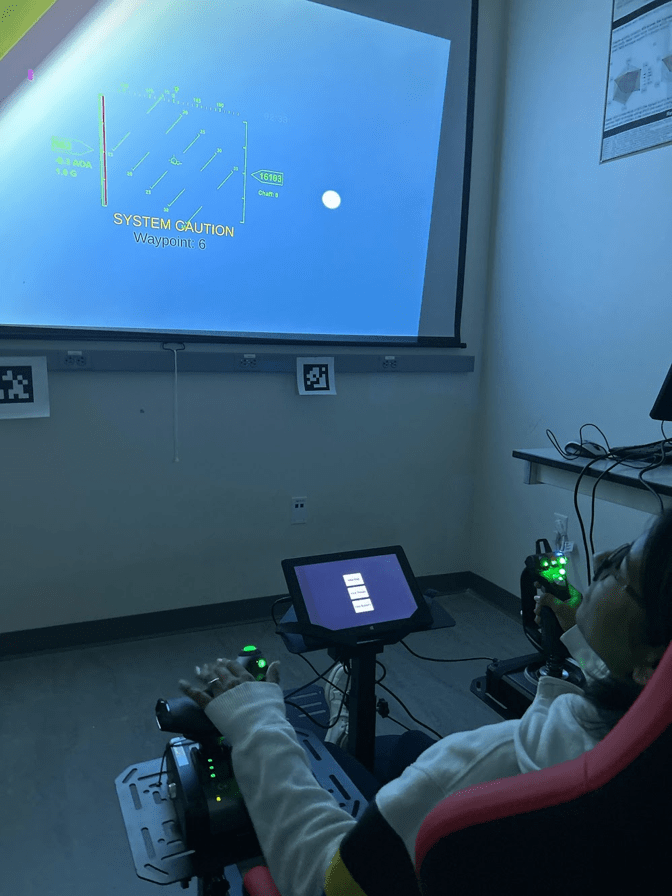
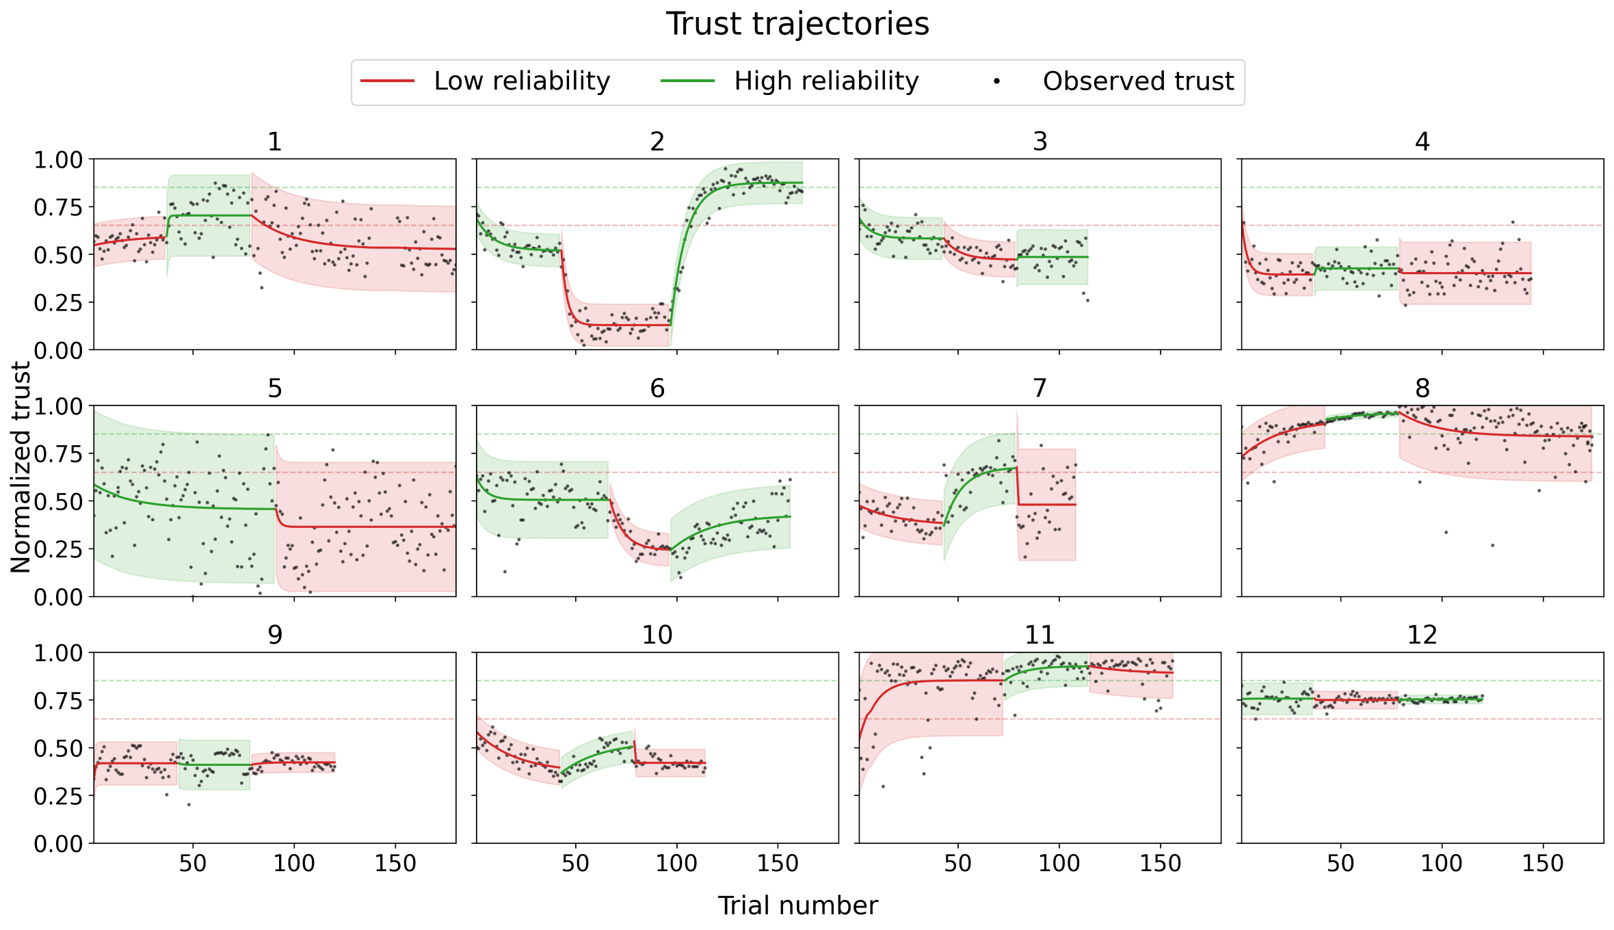
T(t) = (T_0 - T_f) e^{-t/\tau} + T_f + v_t
100+ trials per subject over weeks to months!


[Ventura et al., CHI (Under Review)]
Time constant \(\tau\)
Noise
SPACE: Which explanations are most efficient?
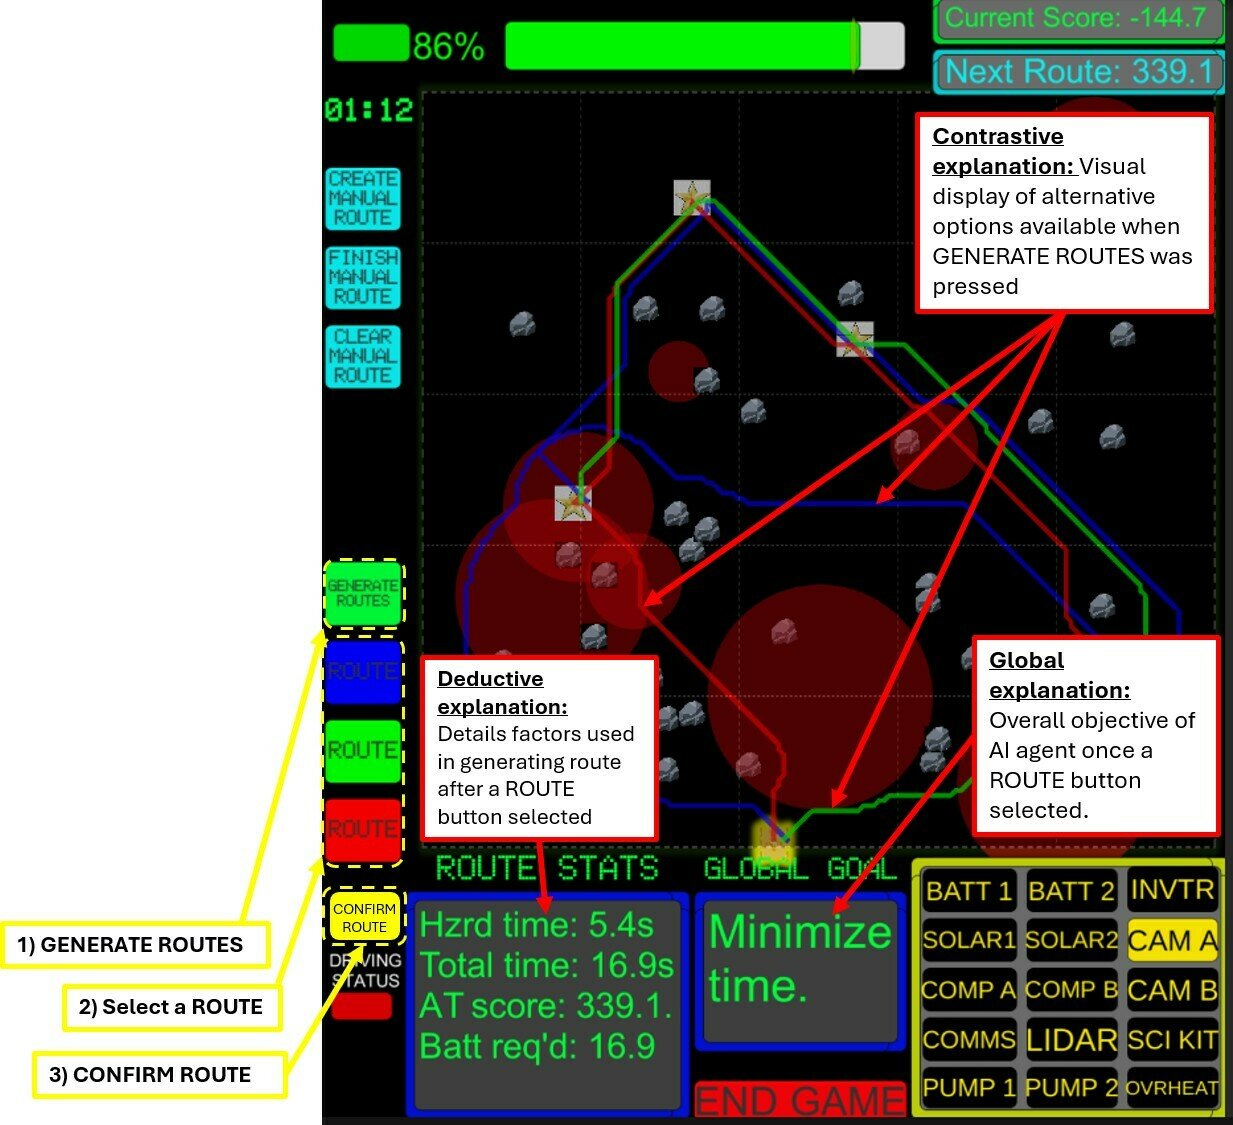
Supervisory Piloting of Autonomously Controlled Explorers
The SPACE simulator: a dual-task Human-Autonomy Teaming simulator used for testing Explainable AI methods


[Boyer et al., Human Factors 2026]
SPACE - Linear Mixed Effects "Dashboard"
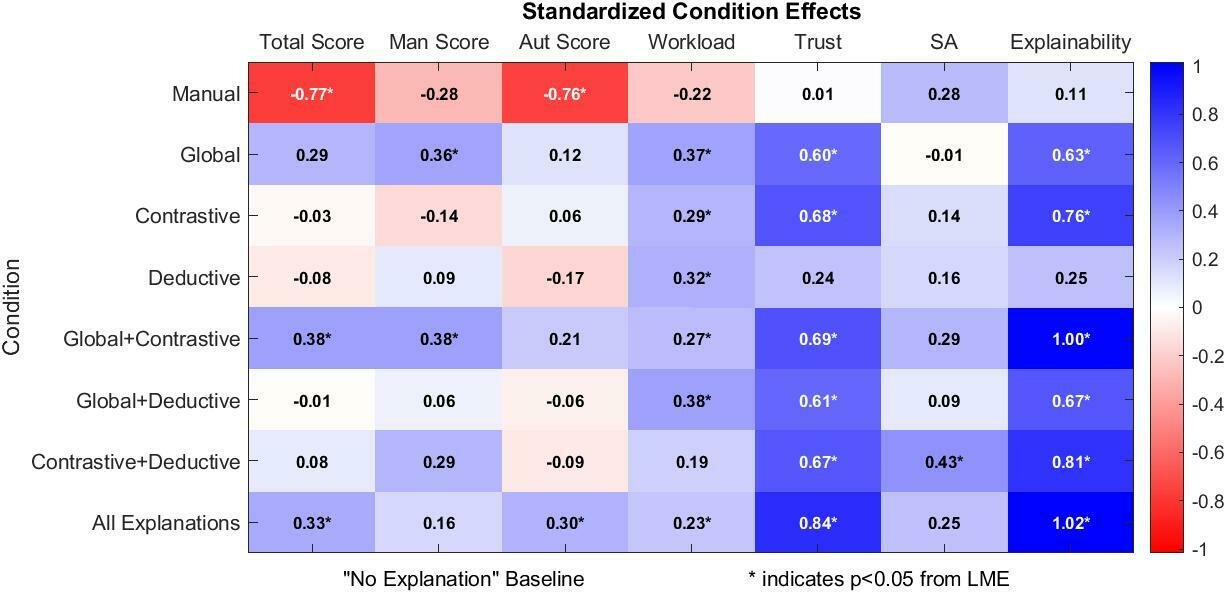
[Boyer et al., Human Factors 2026]
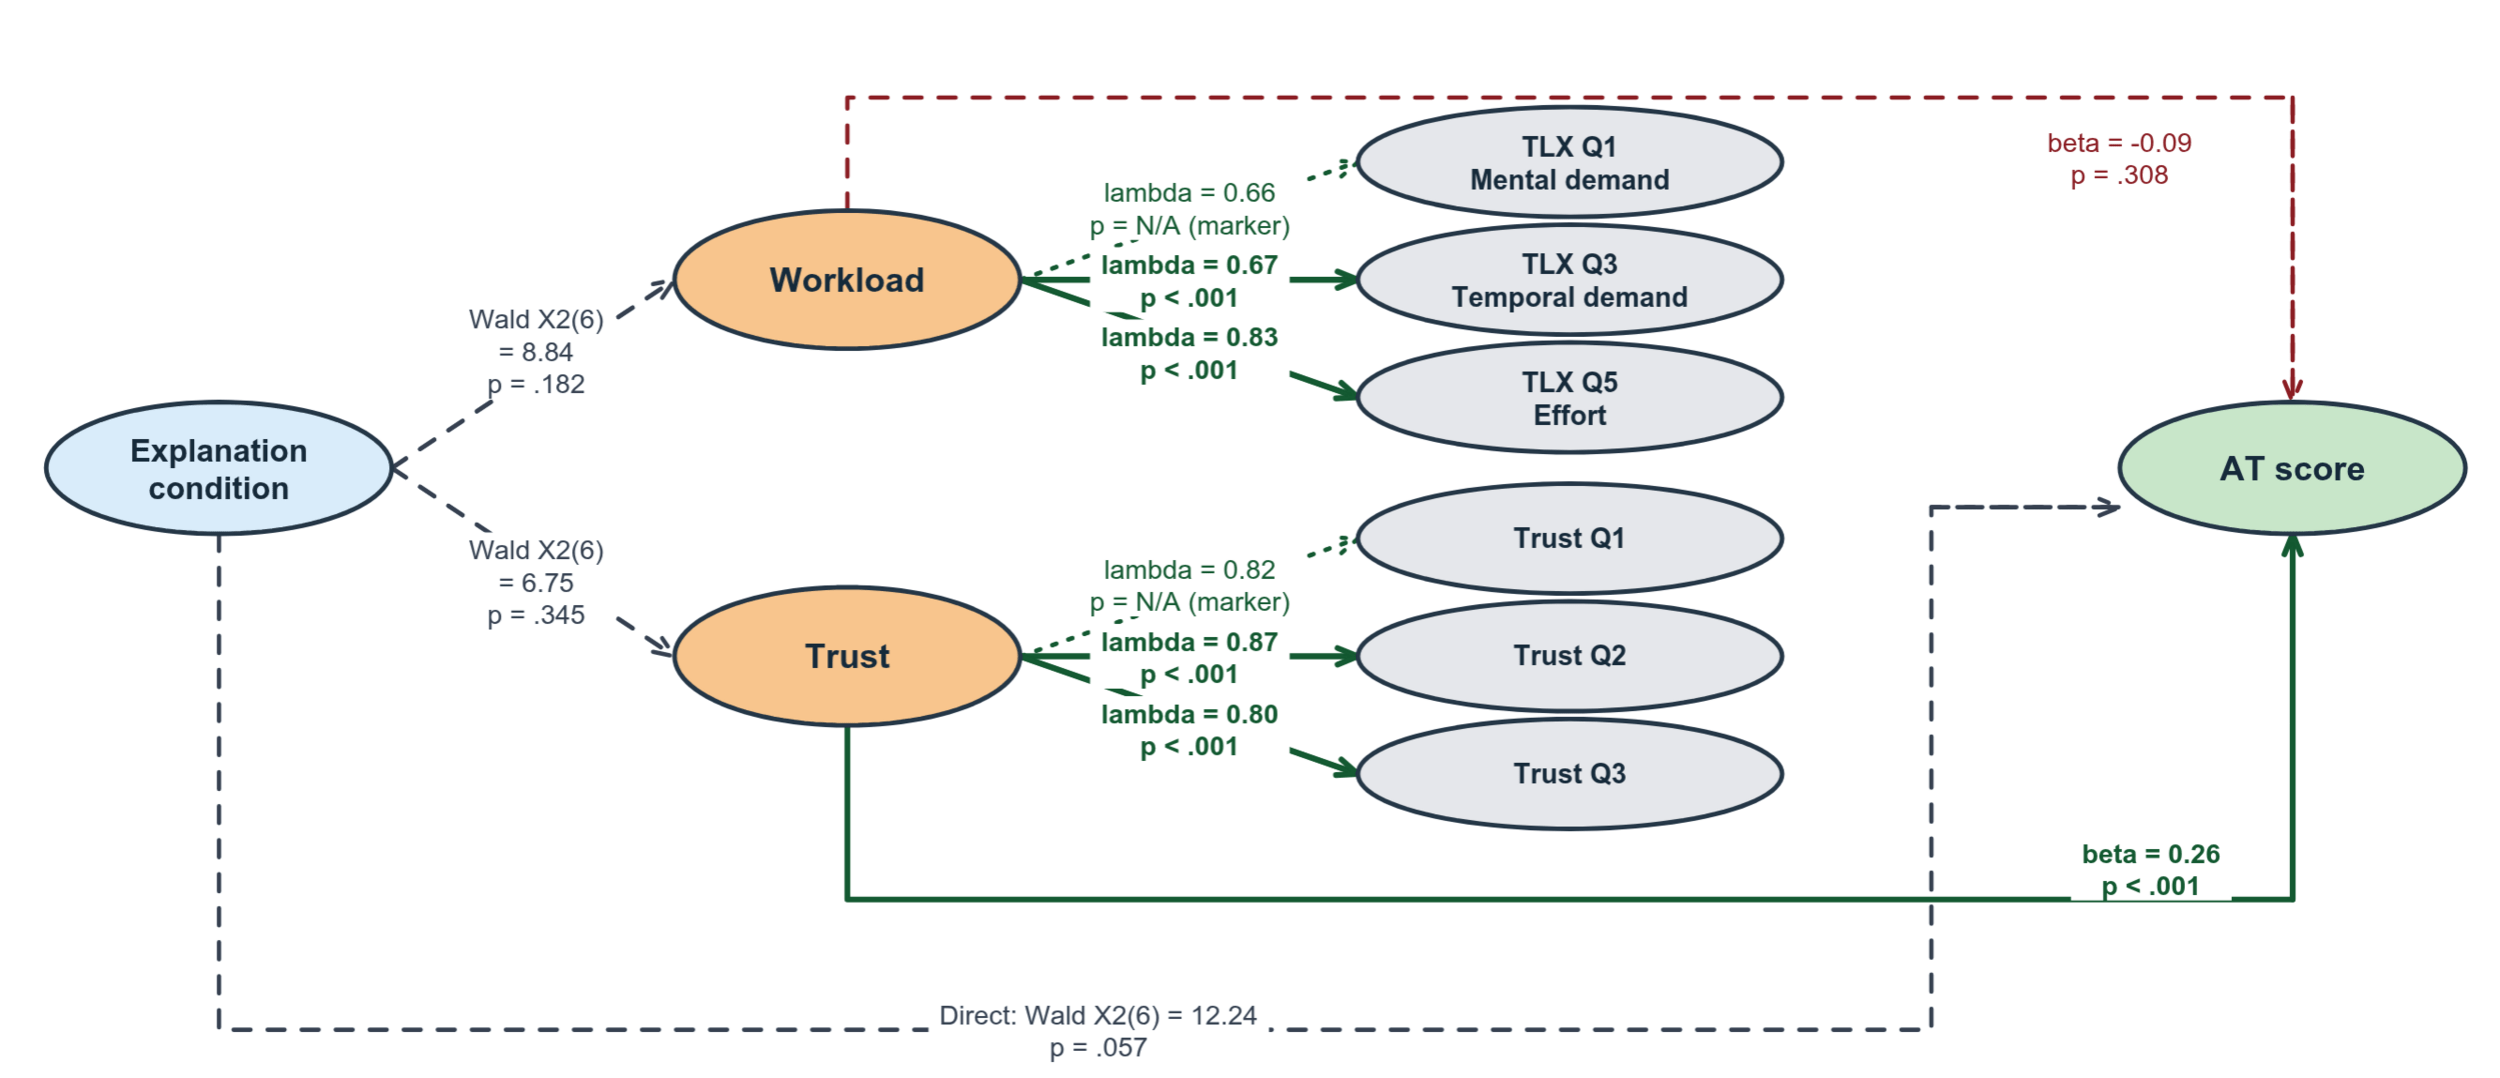
Preliminary: Probabilistic Graphical Models of Trust
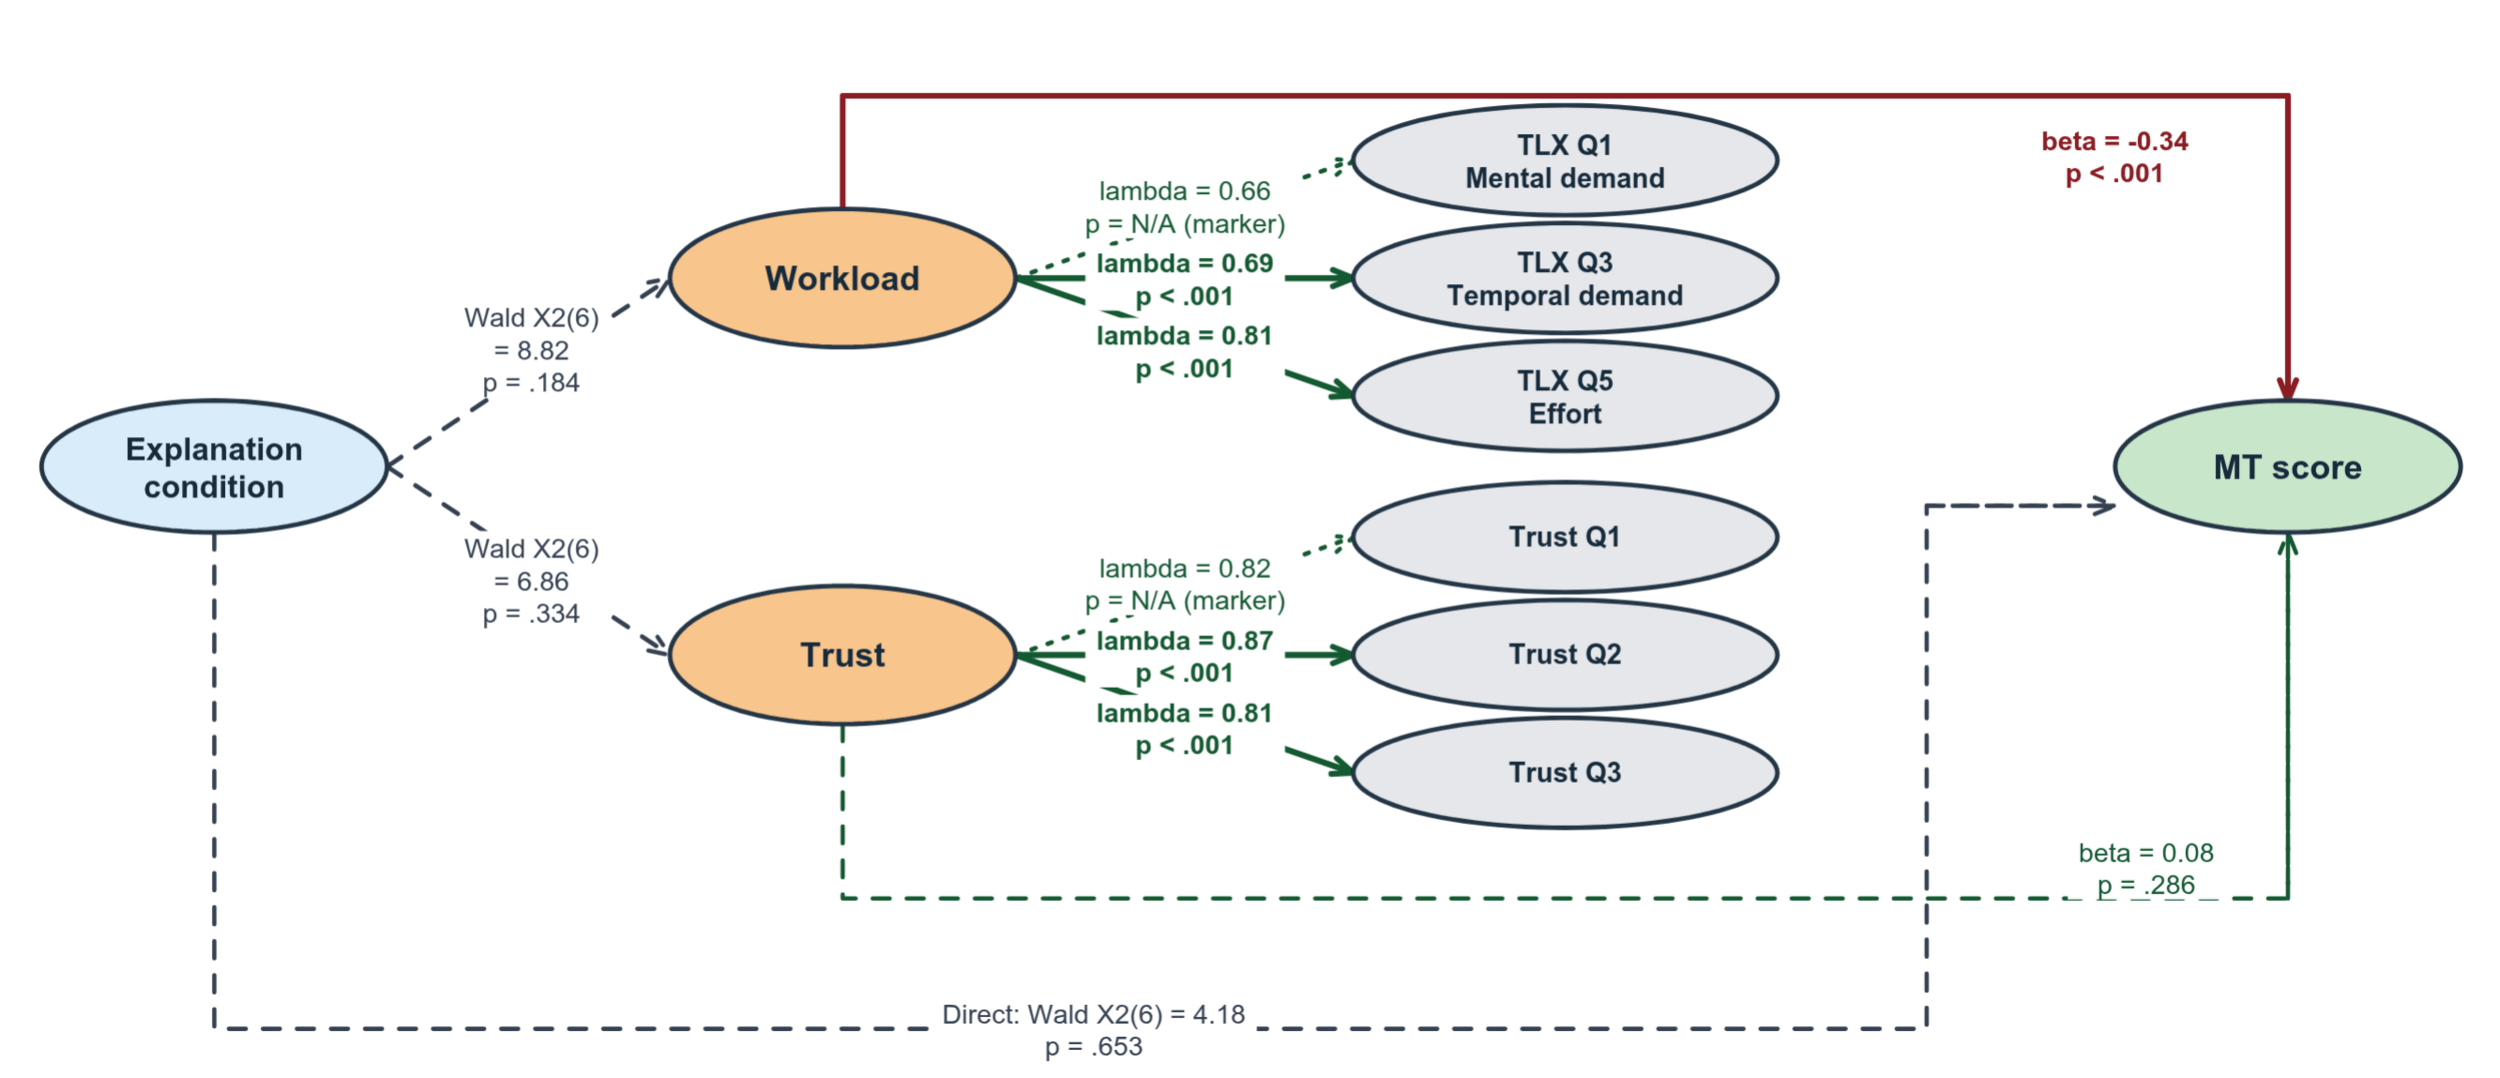
Workload correlated to manual task
Trust correlated to autonomy task
Models can be used in a dynamic decision network (POMDP or POSG)!
Autonomy and People
Motivating Applications
Single-Agent POMPDs
Multi-Agent Games
Open Questions
Open Questions
Motivating Applications
Single-Agent POMPDs
Multi-Agent Games
Autonomy and People
Open questions
- Can we deploy in real storms?
Can we model storm beliefs efficiently enough for online planning?
Where do we do the computing?
Open questions
- Can we deploy in real storms?
- How should we plan with world models?
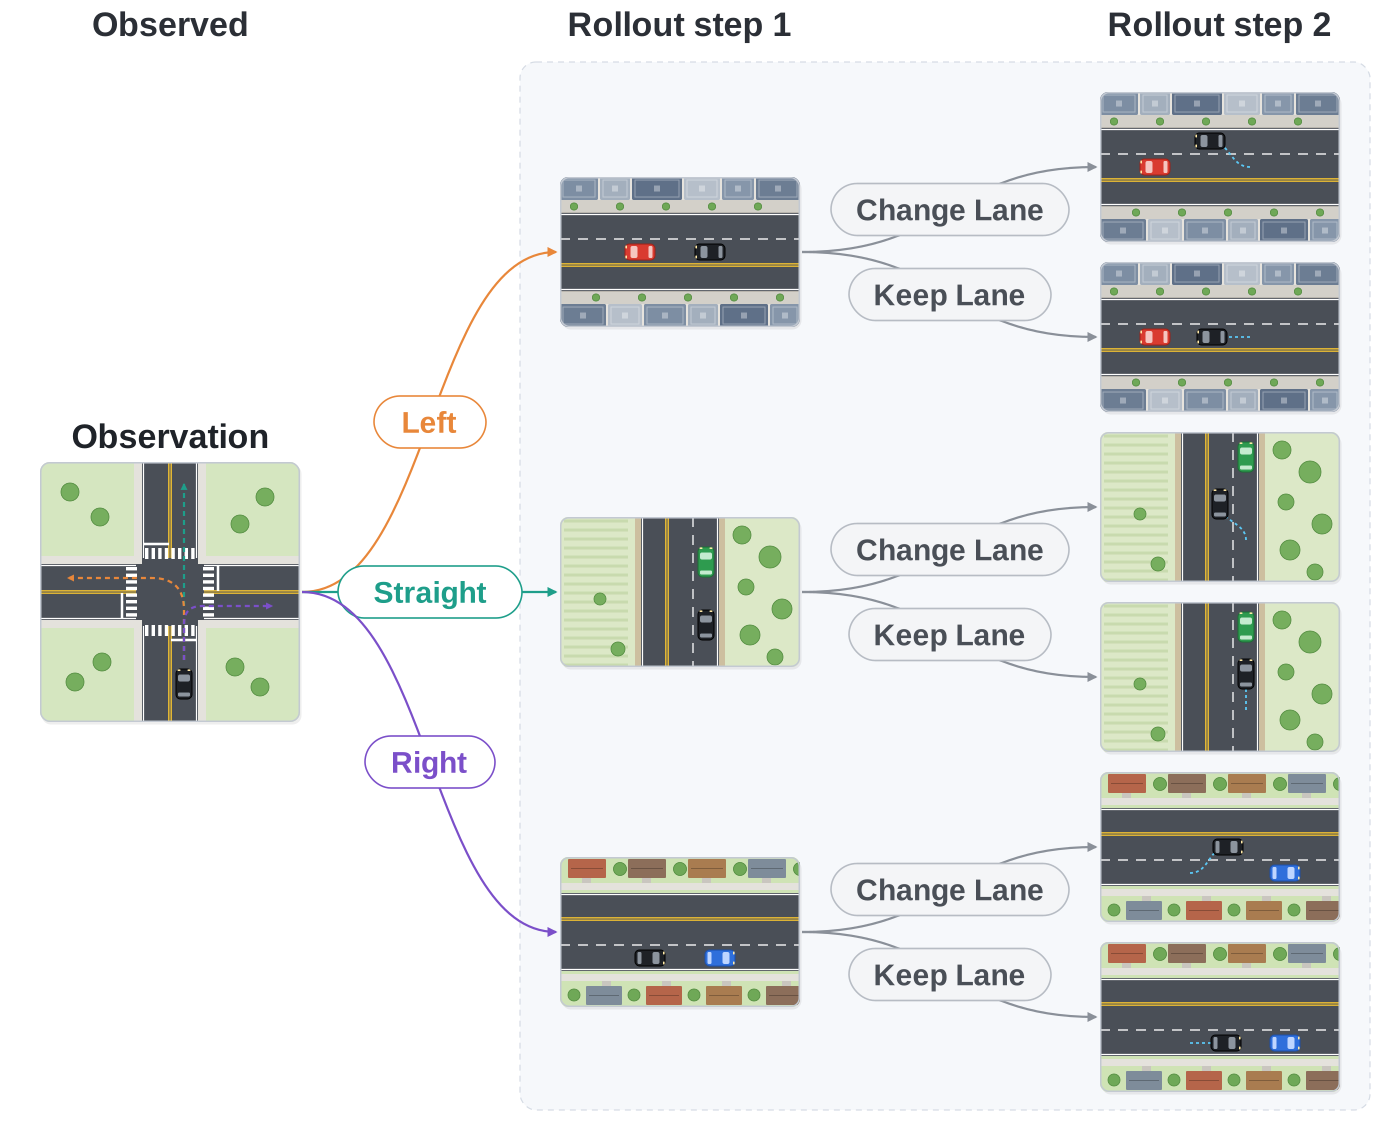
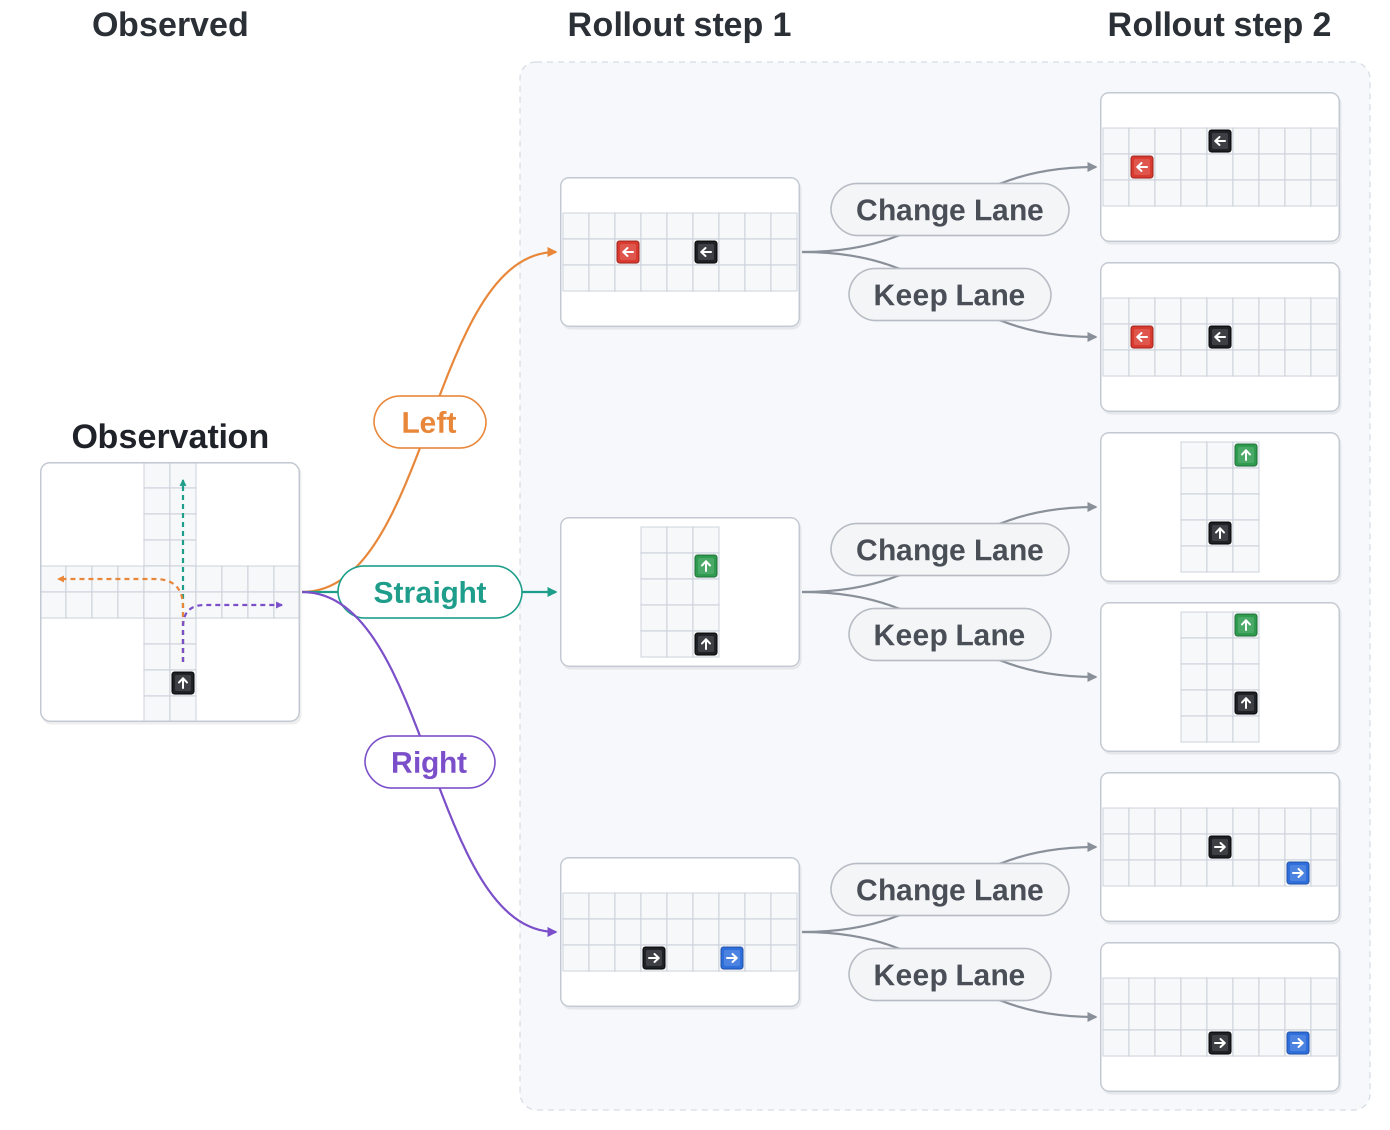
Observation reconstruction
Value-equivalent representations
or
Open questions
- Can we deploy in real storms?
- How should we plan with world models?
- Do POSGs admit reduced memory?
\(m^{i}_{t}\)
\(o^{i}_{t}\)
\(a^{i}_{t}\)
\(r^{i}_{t}\)
\(s_{t}\)
\(m^{i}_{t+1}\)
\(o^{i}_{t+1}\)
\(a^{i}_{t+1}\)
\(r^{i}_{t+1}\)
\(s_{t+1}\)
\(\cdots\)
\(\cdots\)
step t
step t+1
Beliefs do not work.
What goes here???
Open questions
- Can we deploy in real storms?
- How should we plan with world models?
- Do POSGs admit reduced memory?
- Will autonomy help people work better?
+
=
?
Image: NASA
Thank You!

Funding orgs: (all opinions are my own)
VADeR
Collaborators
Meteorology
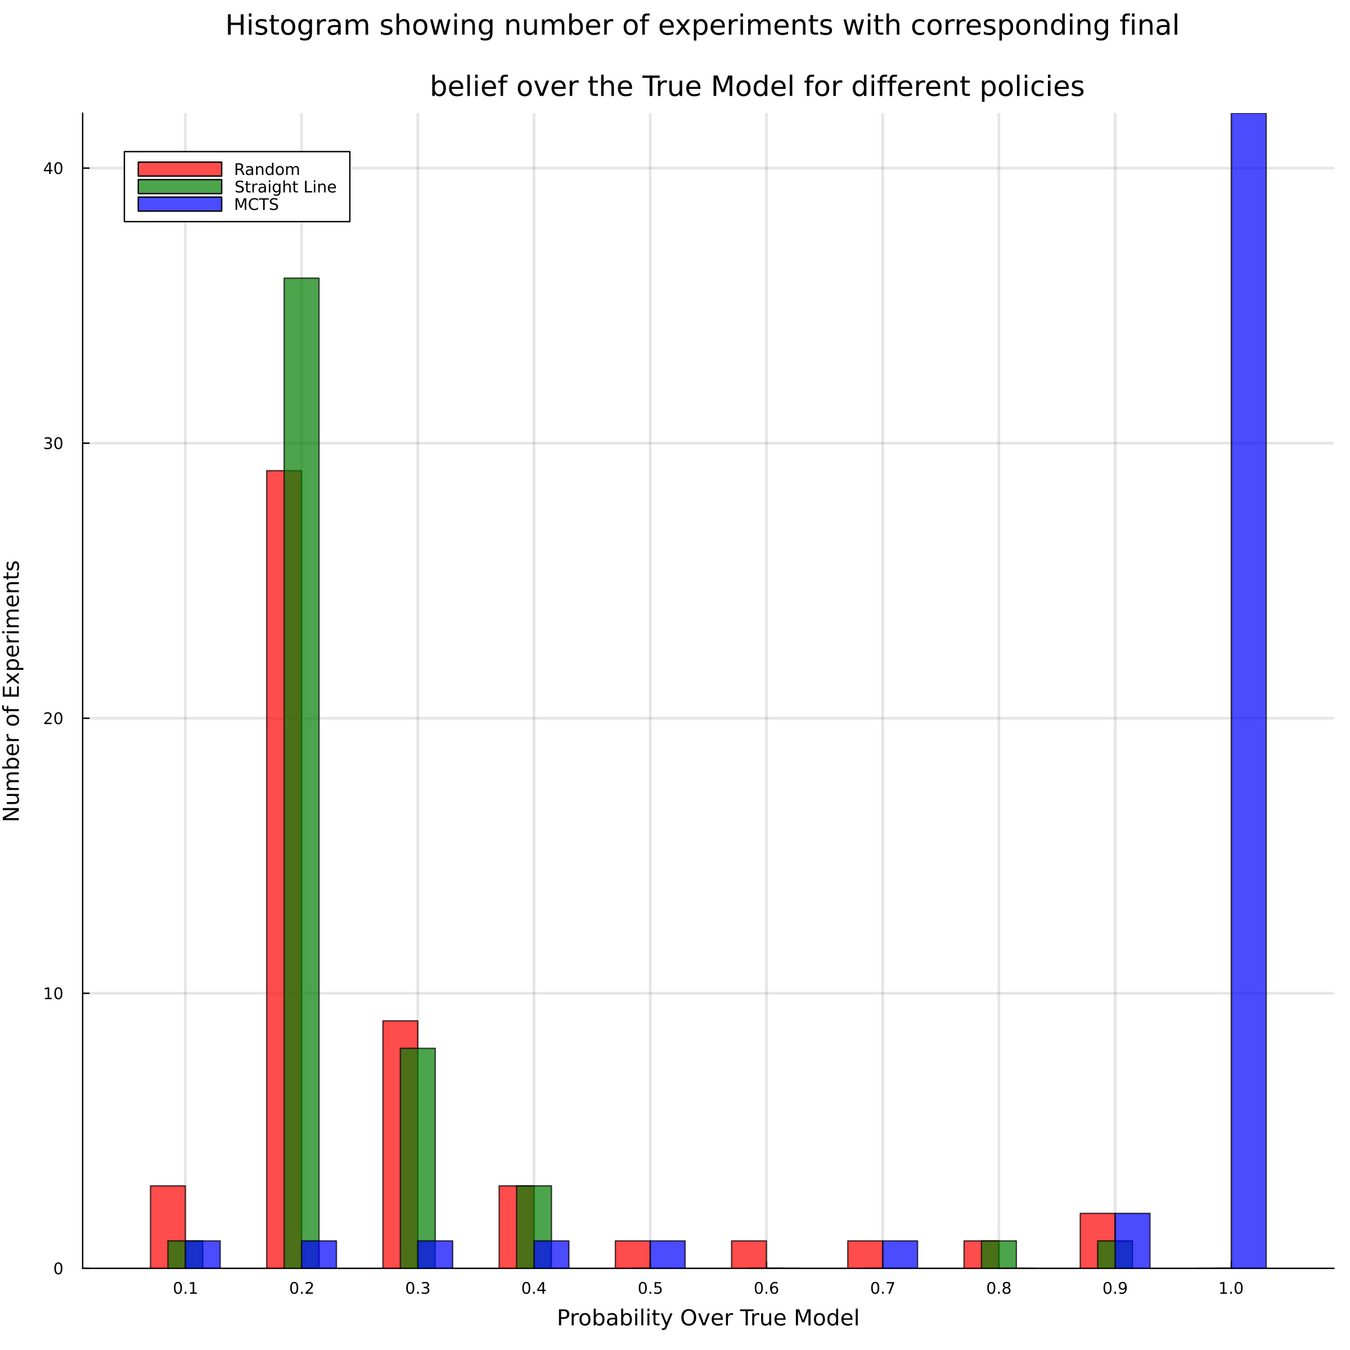
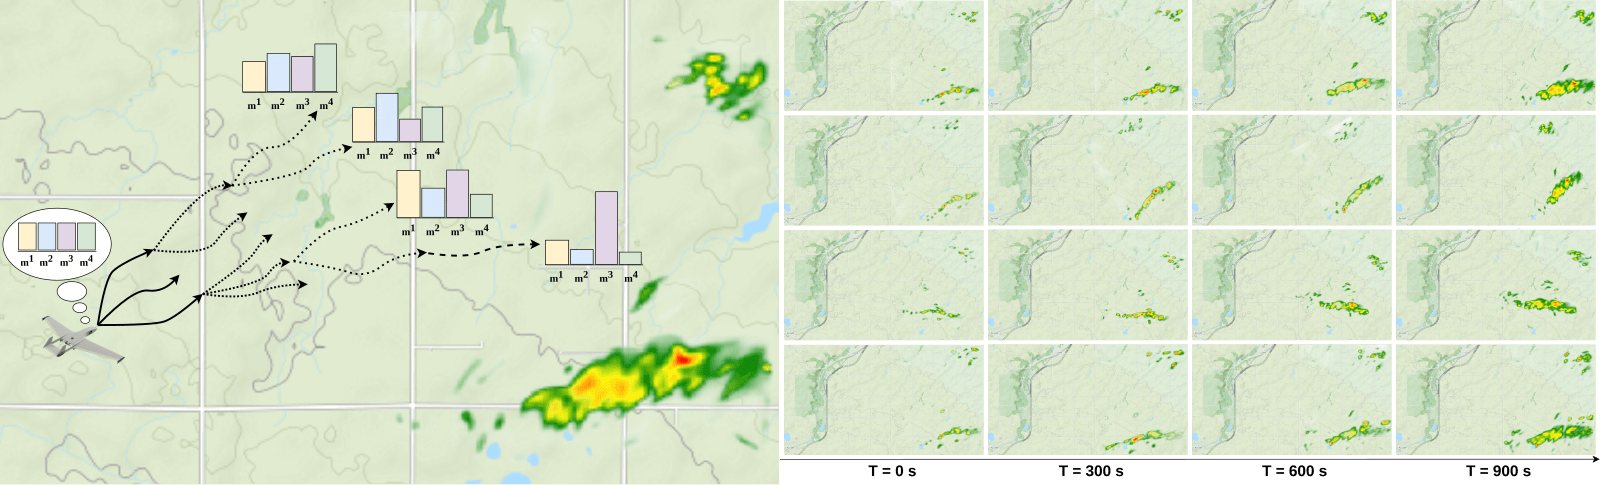
- State: (physical state of aircraft, which forecast is the truth)
- Action: (flight direction, drifter deploy)
- Reward: Terminal reward for correct weather prediction
Defense
- Ukraine is defending itself with semi-autonomous systems
- Needed [Ben F]: Visualization of multiple drone attack and defense trajectories
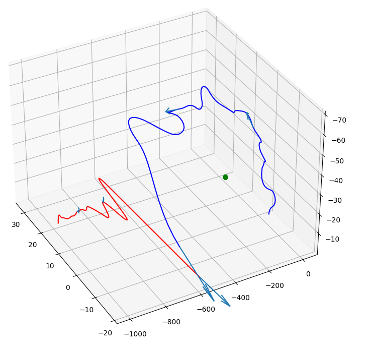
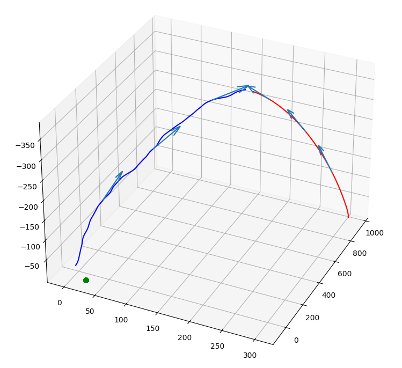
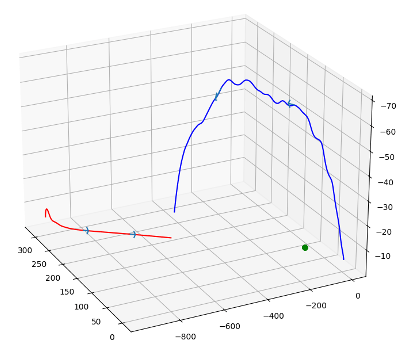
Trained defender vs potential, altitude, and parabola attackers
Tenure Talk
By Zachary Sunberg