Neural Network Function Approximation
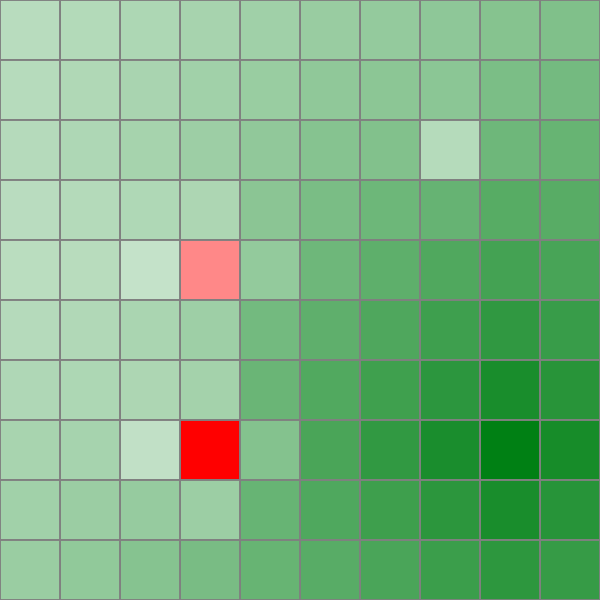
Do we really need to keep track of \(U(s)\) for every \(U\) separately?
Function Approximation
\(y \approx f_\theta(x)\)
Example: Linear Function Approximation:
\[f_\theta(x) = \theta^\top \beta(x)\]
e.g. \(\beta_i(x) = \sin(i \, \pi \, x)\)
Neural Network

\(h(x) = \sigma(Wx + b)\)
Neural Network
\(h(x) = \sigma(Wx + b)\)
Nonlinearities

Training
\[\theta^* = \argmin_\theta \sum_{(x,y) \in \mathcal{D}} l(f_\theta(x), y)\]
Stochastic Gradient Descent: \(\theta \gets \theta - \alpha \, \nabla_\theta\, l (f_\theta(x), y)\)
Chain Rule
Backprop


\[l(x, y_\text{true}) = \left(\theta_2 x + \theta_1 - y_\text{true}\right)^2\]
a “fast and furious” approach to training neural networks does not work and only leads to suffering. Now, suffering is a perfectly natural part of getting a neural network to work well, but it can be mitigated by being thorough, defensive, paranoid, and obsessed with visualizations of basically every possible thing. The qualities that in my experience correlate most strongly to success in deep learning are patience and attention to detail.
- Andrej Karpathy
Adaptive Step Size: RMSProp
Adaptive Step Size: ADAM

(Adaptive Moment Estimation)


\(\odot\) means elementwise multiplication.
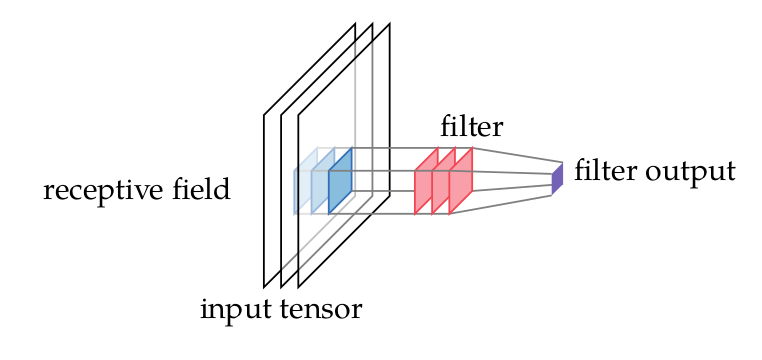
On Your Radar: ConvNets


On Your Radar: Regularization
e.g. Batch norm, layer norm, dropout

On Your Radar: Skip Connections (Resnets)
Resources
OpenAI Spinning up
075 Neural Network Function Approximation
By Zachary Sunberg