Neural Network Architectures for Sequential Inputs
Review from DMU: Neural Networks
\[\theta^* = \argmin_\theta \sum_{(x,y) \in \mathcal{D}} l(f_\theta(x), y)\]
Stochastic Gradient Descent: \(\theta \gets \theta - \alpha \, \nabla_\theta\, l (f_\theta(x), y)\)
Multi-Layered Perceptron (MLP)
\(h_i(x) = \sigma(W_i x + b_i)\)
\(\hat{y} = h_3(h_2(h_1(x)))\)
("misnomer" because original perceptron used step function)
Review: Why sequences are needed
In an MDP, for any \(k \geq 0\):
\[P(r_{t+k} \mid \pi, s_t, a_{t-1}, s_{t-1}, \ldots) = P(r_{t+k} \mid \pi, s_t)\text{,}\]
so there is always an optimal policy based on the state.
In a POMDP, there is no systematic way to simplify
\[P(r_{t+k} \mid \pi, o_t, a_{t-1}, o_{t-1}, \ldots)\text{,}\]
so an optimal policy may depend on the entire action-observation history.
A big MLP that takes the entire sequence in generally has too many parameters (and cannot handle variable length input)
Recurrent neural networks
Images: Pascanu 2013
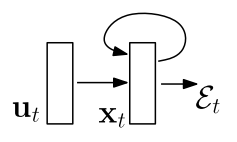
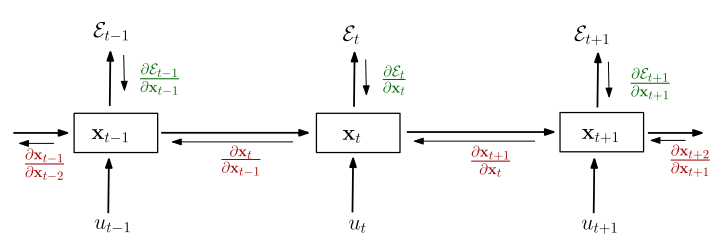
Input: \(u_t\)
State/Output: \(x_t\)
Cost: \(\mathcal{E}_t\)
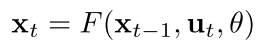
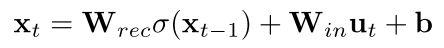
Problem: Vanishing/exploding gradients
Important papers:
- Hochreiter, Sepp. Untersuchungen zu dynamischen neuronalen Netzen. Diploma thesis, TU Munich, 1991.)
- Bengio, Yoshua, Patrice Simard, and Paolo Frasconi. "Learning long-term dependencies with gradient descent is difficult." IEEE transactions on neural networks 5.2 (1994) [11k cit.]
- Pascanu, Razvan, Tomas Mikolov, and Yoshua Bengio. "On the difficulty of training recurrent neural networks." International conference on machine learning, 2013. [6.5k cit.]
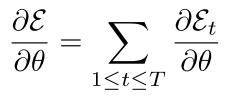
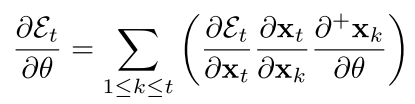
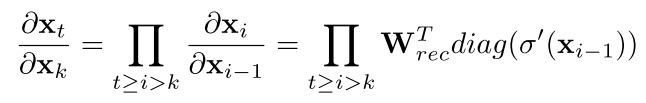
(\(\frac{\partial^+x_k}{\partial \theta}\) is partial with \(x_{k-1}\) held constant)
Generally, informally: If \(\sigma' \in [0,1]\) (e.g. sigmoid), product can become very small, even numerically zero.
Formally, for the linear case (\(\sigma = \text{identity}\))
- Largest eigenvalue of \(W_{rec}\) < 1: sufficient for vanishing
- Largest eigenvalue of \(W_{rec}\) > 1: necessary for exploding
Long Short Term Memory (LSTM)
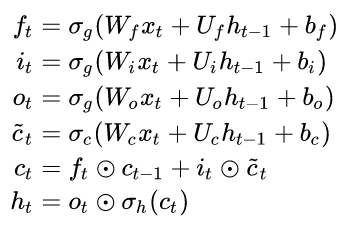
Input: \(x_t\)
Output: \(h_t\)
Cell state: \(c_t\)
Forget gate
Input Gate
Output Gate
Hochreiter, S. and Schmidhuber, J. (1997). Long Short-Term Memory. 1780, 1735–1780.
By Guillaume Chevalier - File:The_LSTM_Cell.svg, CC BY-SA 4.0, https://commons.wikimedia.org/w/index.php?curid=109362147
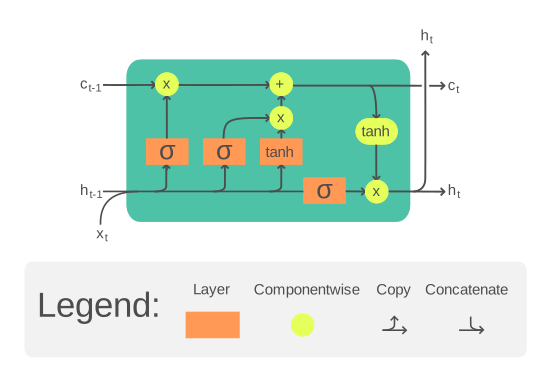
\(f_t\)
\(i_t\)
\(o_t\)
\(\tilde{c}_t\)
Gated Recurrent Unit (GRU)
By Jeblad - Own work, CC BY-SA 4.0, https://commons.wikimedia.org/w/index.php?curid=66225938

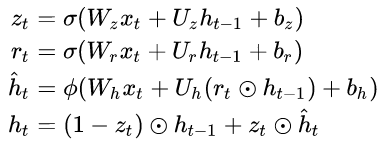
Input: \(x_t\)
Output: \(\hat{y}_t\) (\(h_t\))
Recurrent State: \(h_t\)
Update gate
Reset gate
Fewer parameters than LSTM
Transformer Overview
Vaswani, Ashish, et al. "Attention is all you need." Advances in neural information processing systems 30 (2017).
Excellent Blog Post: https://dugas.ch/artificial_curiosity/GPT_architecture.html
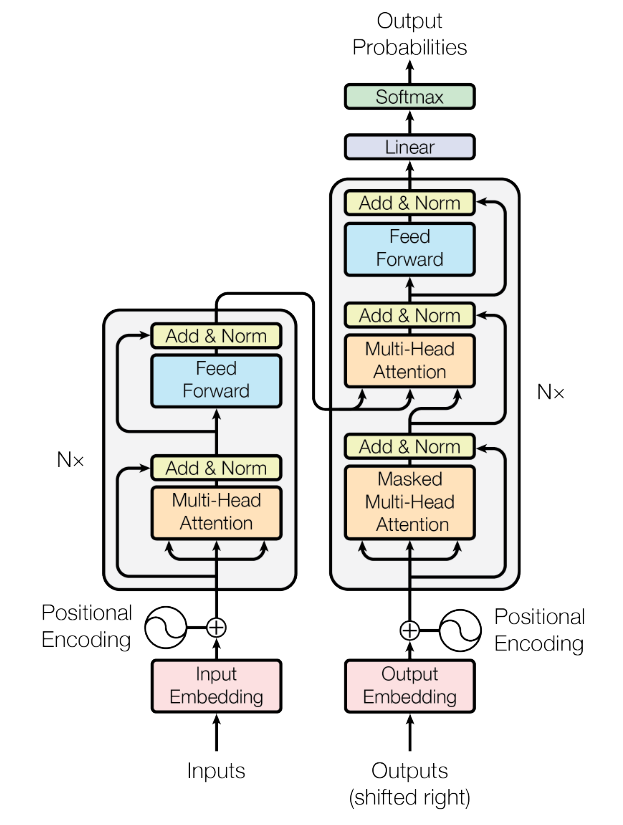
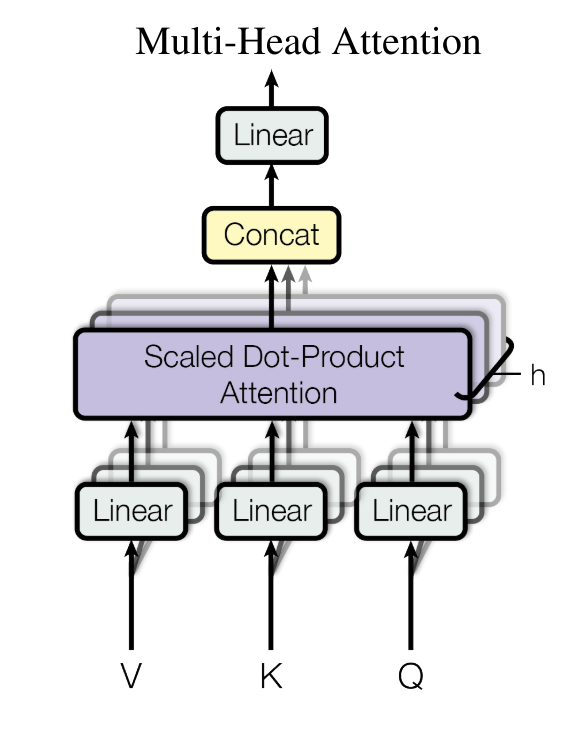
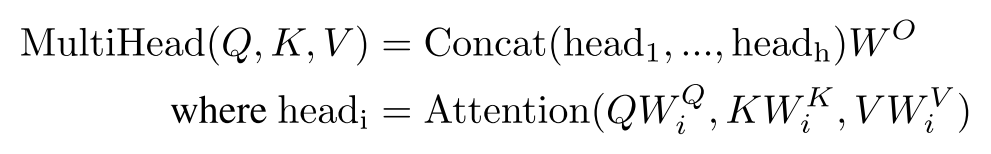
- Multi-Head Attention
- Skip Connections
- Embeddings
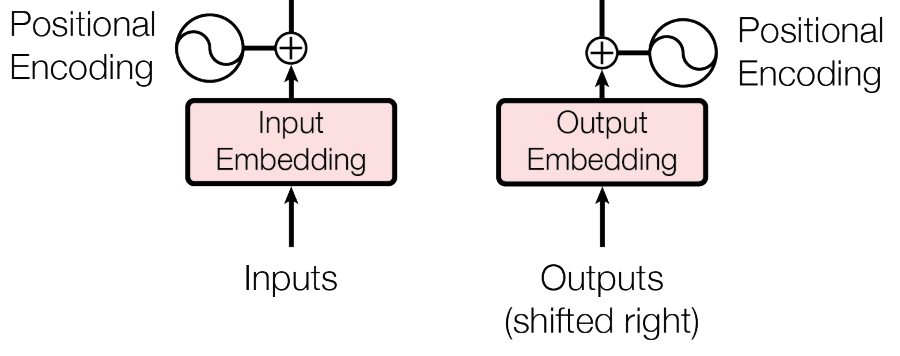
- Positional Encodings
- Layer Norm
Skip Connections (Resnets)
Word (Token) Embeddings
- Address the vanishing/exploding gradient problem
- Ensemble effect
Positional Encodings
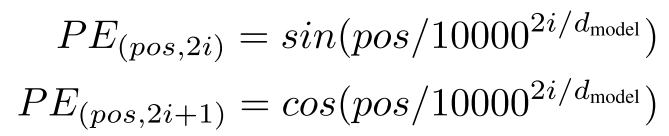
Layer Norm
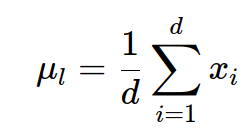
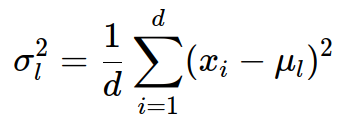
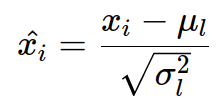
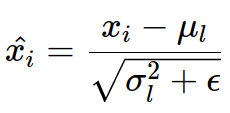
or
Attention: Fully differentiable key-value lookup
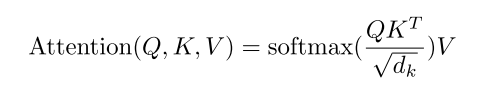
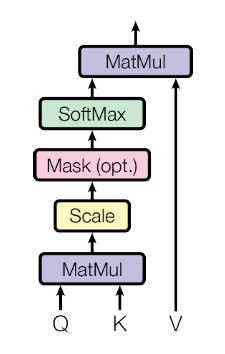
Attention: Fully differentiable key-value lookup
Transformers: Putting it all together
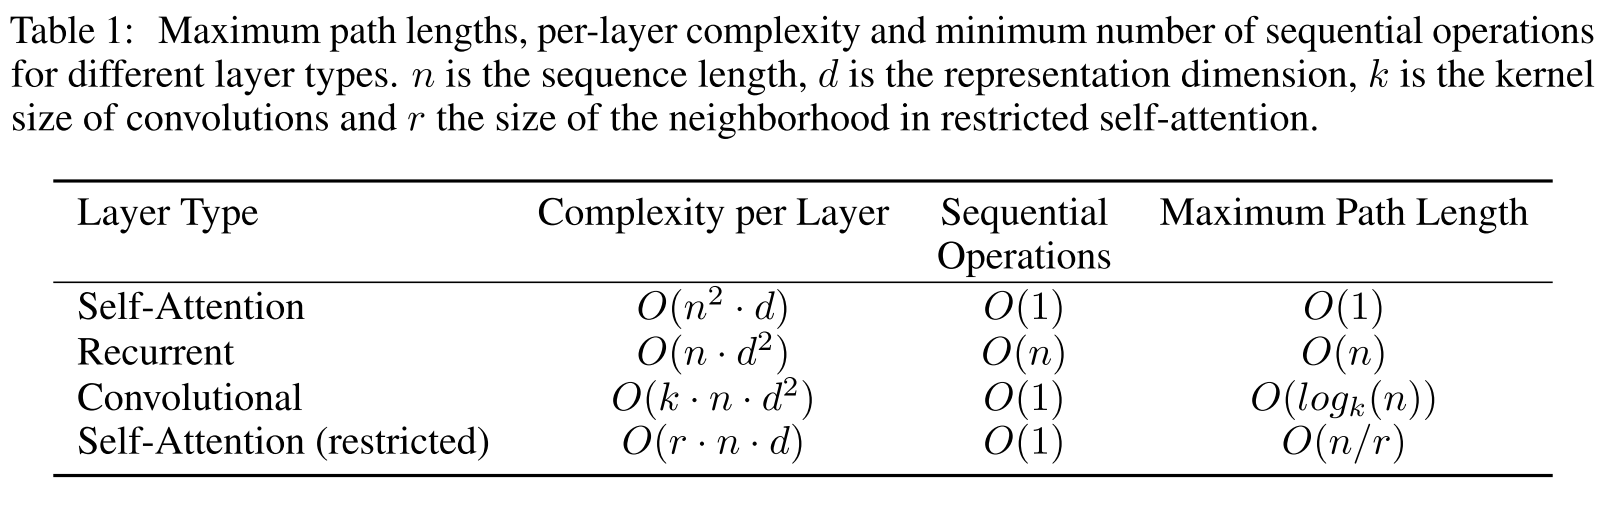
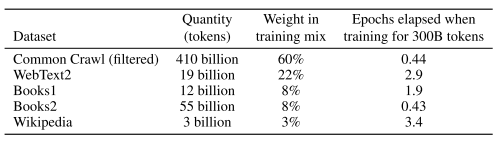
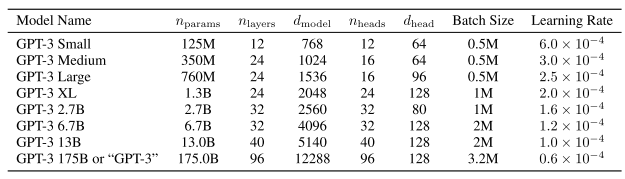
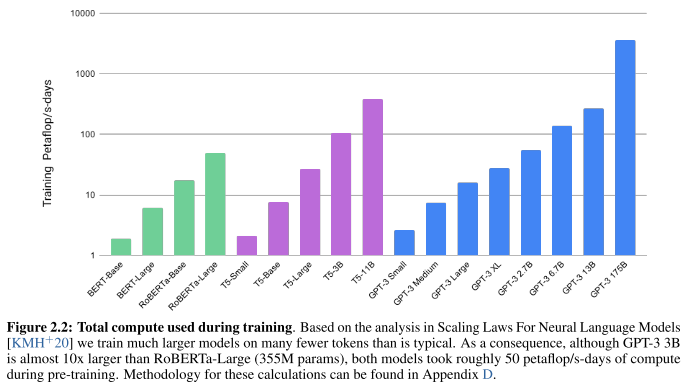
GPT-3
Brown, T. B., Mann, B., Ryder, N., Subbiah, M., Kaplan, J., Dhariwal, P., Neelakantan, A., Shyam, P., Sastry, G., Askell, A., Agarwal, S., Herbert-Voss, A., Krueger, G., Henighan, T., Child, R., Ramesh, A., Ziegler, D. M., Wu, J., Winter, C., … Amodei, D. (2020). Language models are few-shot learners. Advances in Neural Information Processing Systems, 2020-December.

Decision Transformer
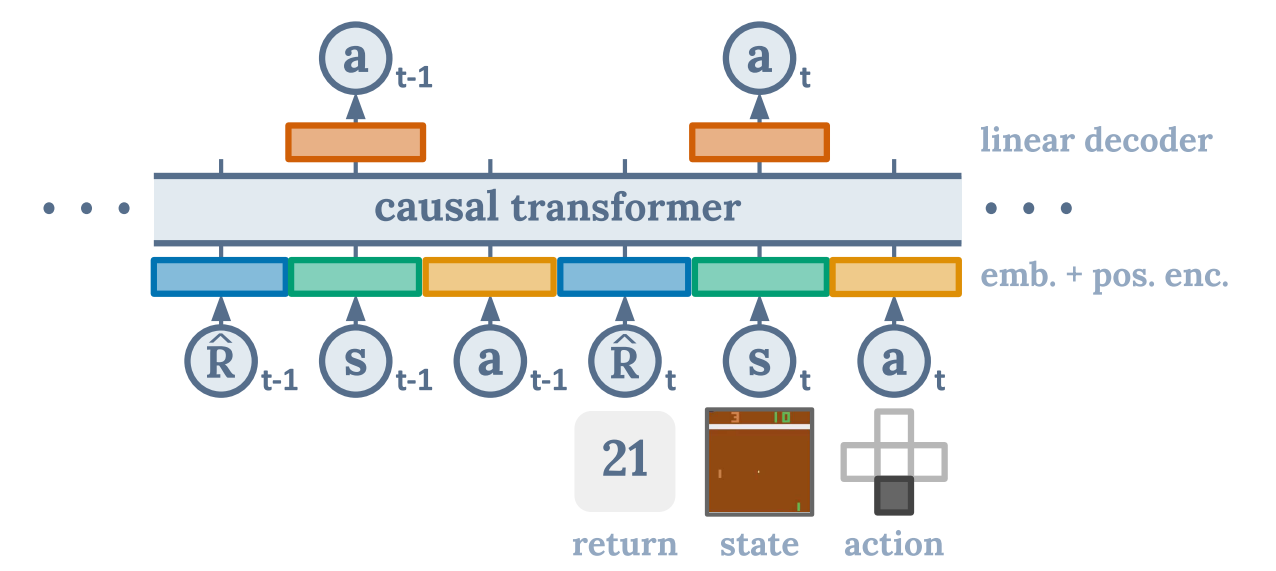
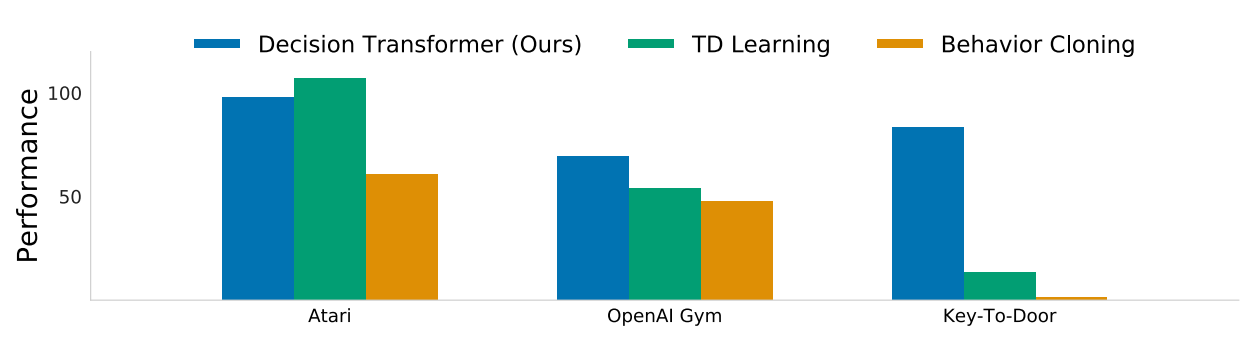
Chen, L., Lu, K., Rajeswaran, A., Lee, K., Grover, A., Laskin, M., Abbeel, P., Srinivas, A., & Mordatch, I. (2021). Decision Transformer: Reinforcement Learning via Sequence Modeling. Advances in Neural Information Processing Systems, 18, 15084–15097.
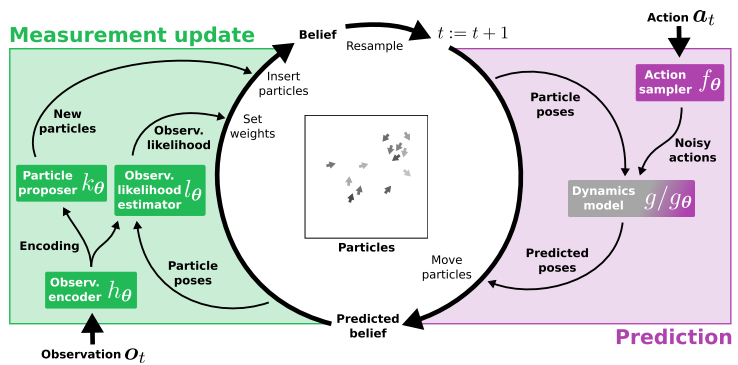
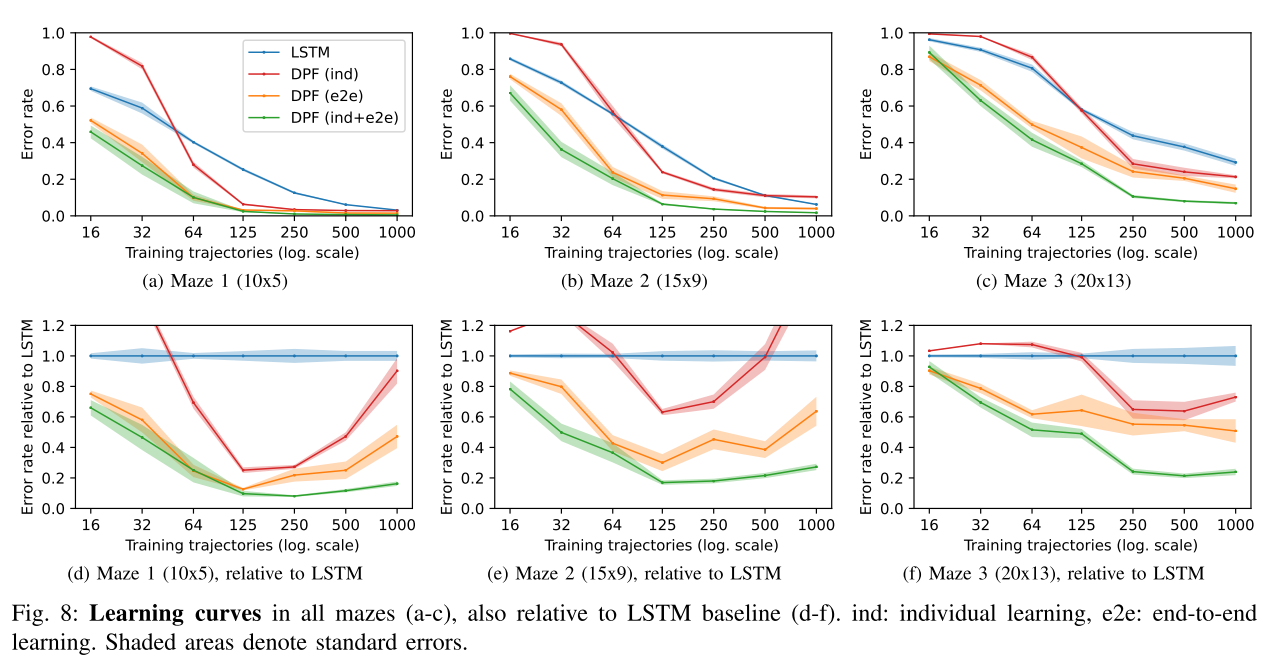
Differentiable Particle Filters
Jonschkowski, R., Rastogi, D., & Brock, O. (2018, June). Differentiable Particle Filters: End-to-End Learning with Algorithmic Priors. Proceedings of Robotics: Science and Systems. https://doi.org/10.15607/RSS.2018.XIV.001
My Thoughts
- Transformers work really well for interpreting structured data that is communicated in a time series (Language is a way of serializing ideas)
- State estimation is NOT usually the hardest part of a POMDP, so just use filtering if you have a decent model (?)
- Use an algorithmic prior when you are learning.
- In tasks where you have to interpret language, transformers are probably the way to go.