Large Language Models: From "Attention is all you need" to ChatGPT
DMU++ | August 28, 2025
AI was used to augment searches and verify connections between papers.
From "Attention is all you need" to ChatGPT
2017: Attention is all you need
2018: GPT-1
2019: GPT-2
2020: GPT-3
2022: InstructGPT
2022: ChatGPT
2023: GPT-4
2025: GPT-5
Attention Is All You Need
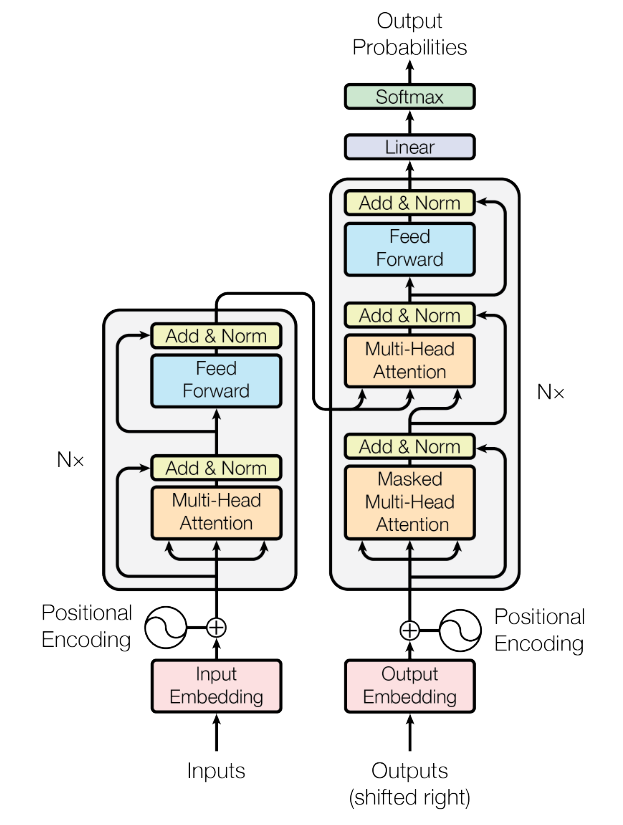
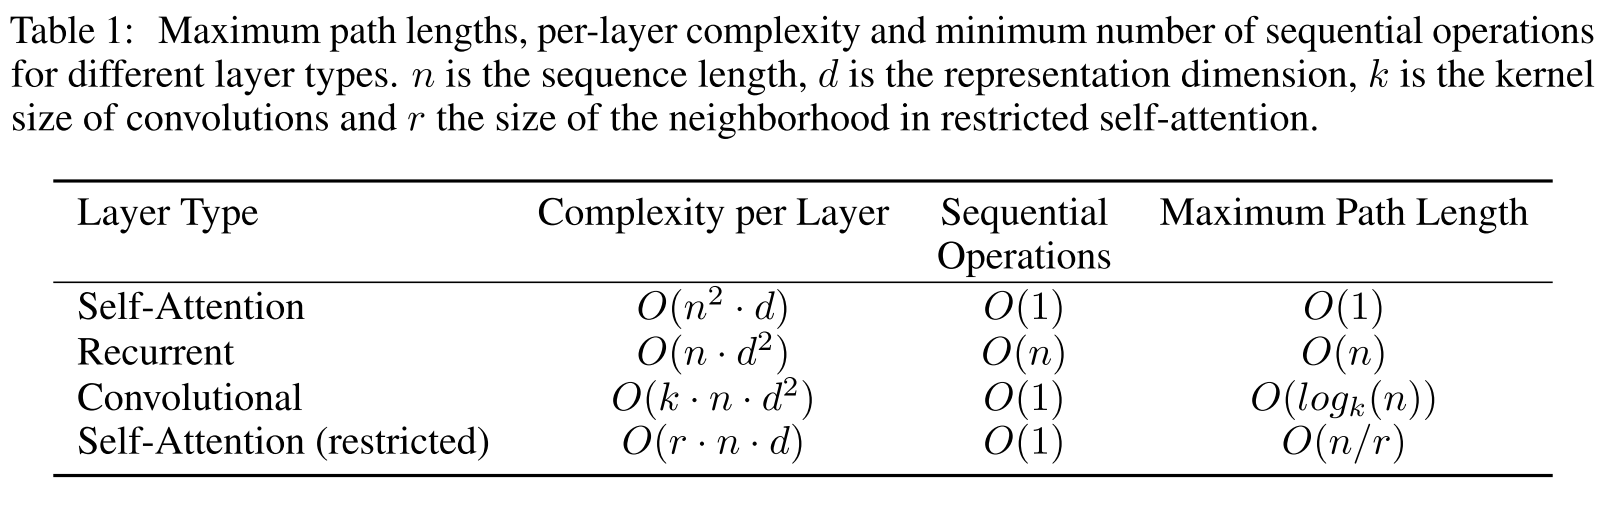
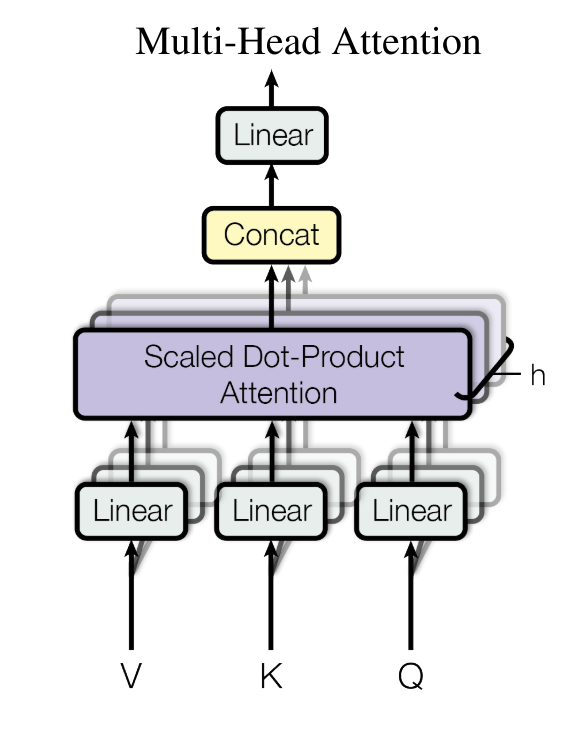
- 2017
- Language Translation
- Cited by 191747 (~70/day)
- 213M params
- 10^18 FLOPs to train
GPT-1
- Improving Language Understanding by Generative Pre-Training
- 117M Parameters
- Open AI; 2018; 15,510 citations
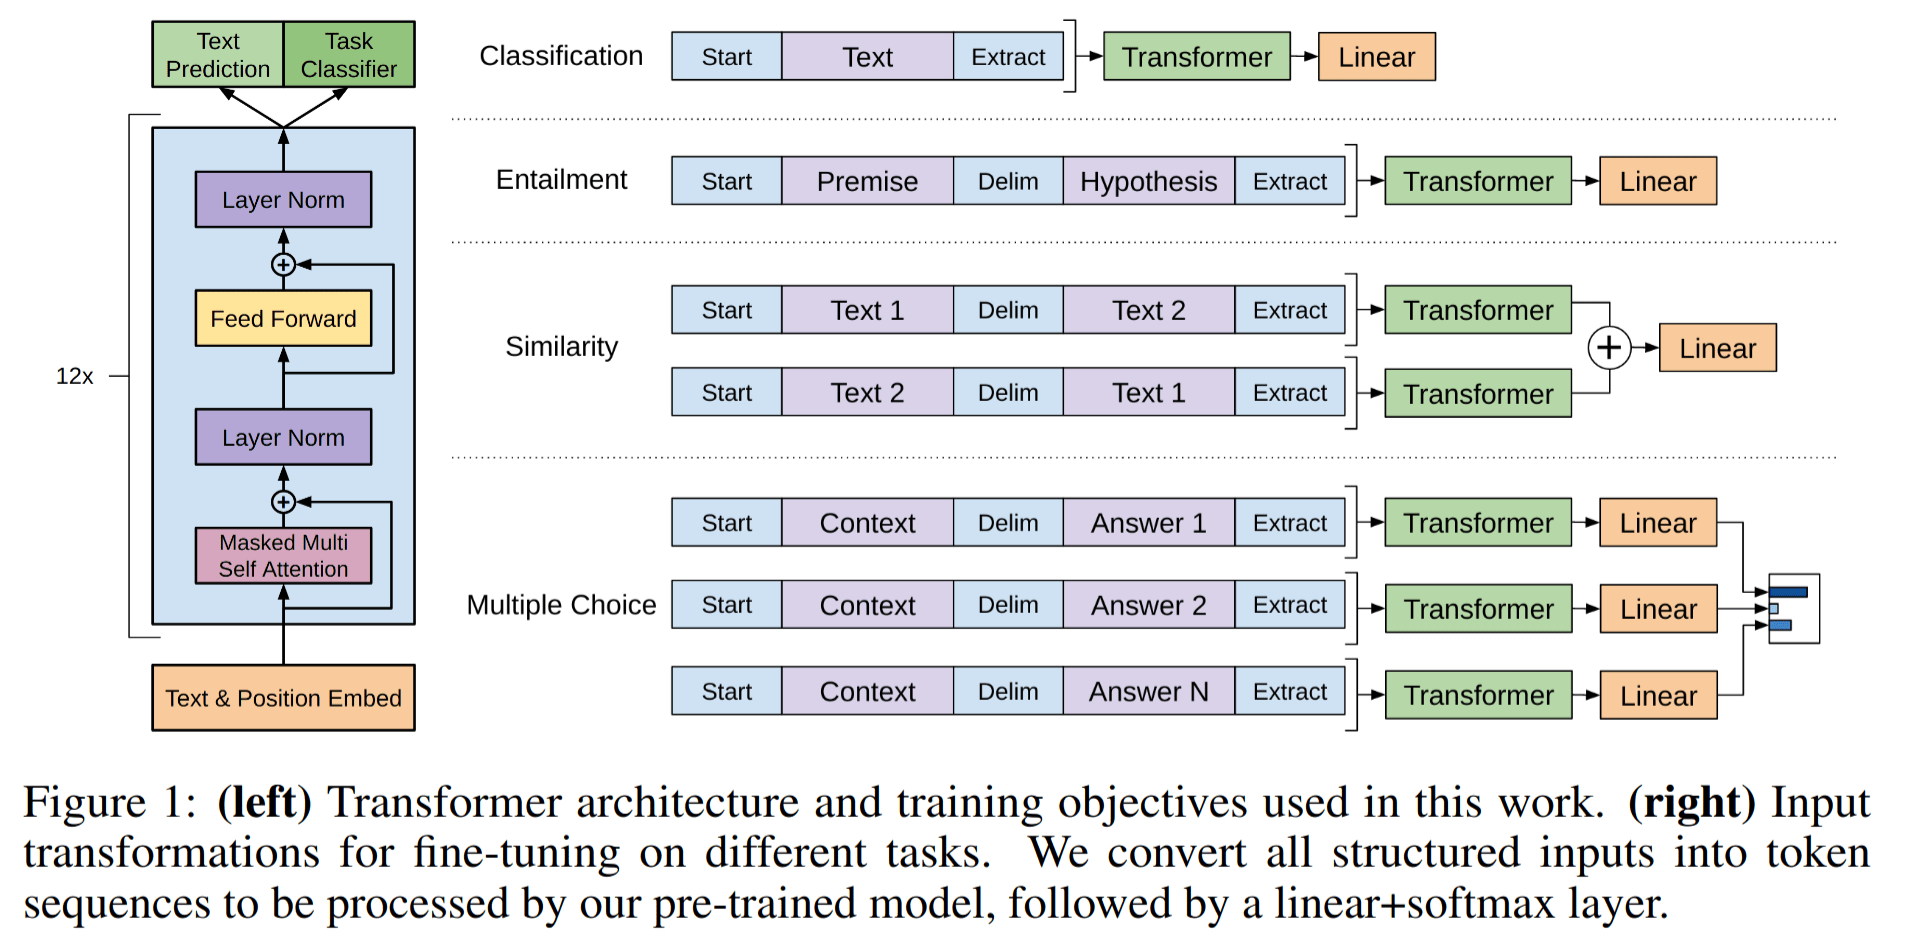
AIAYN (213M)
GPT-1 (117M)
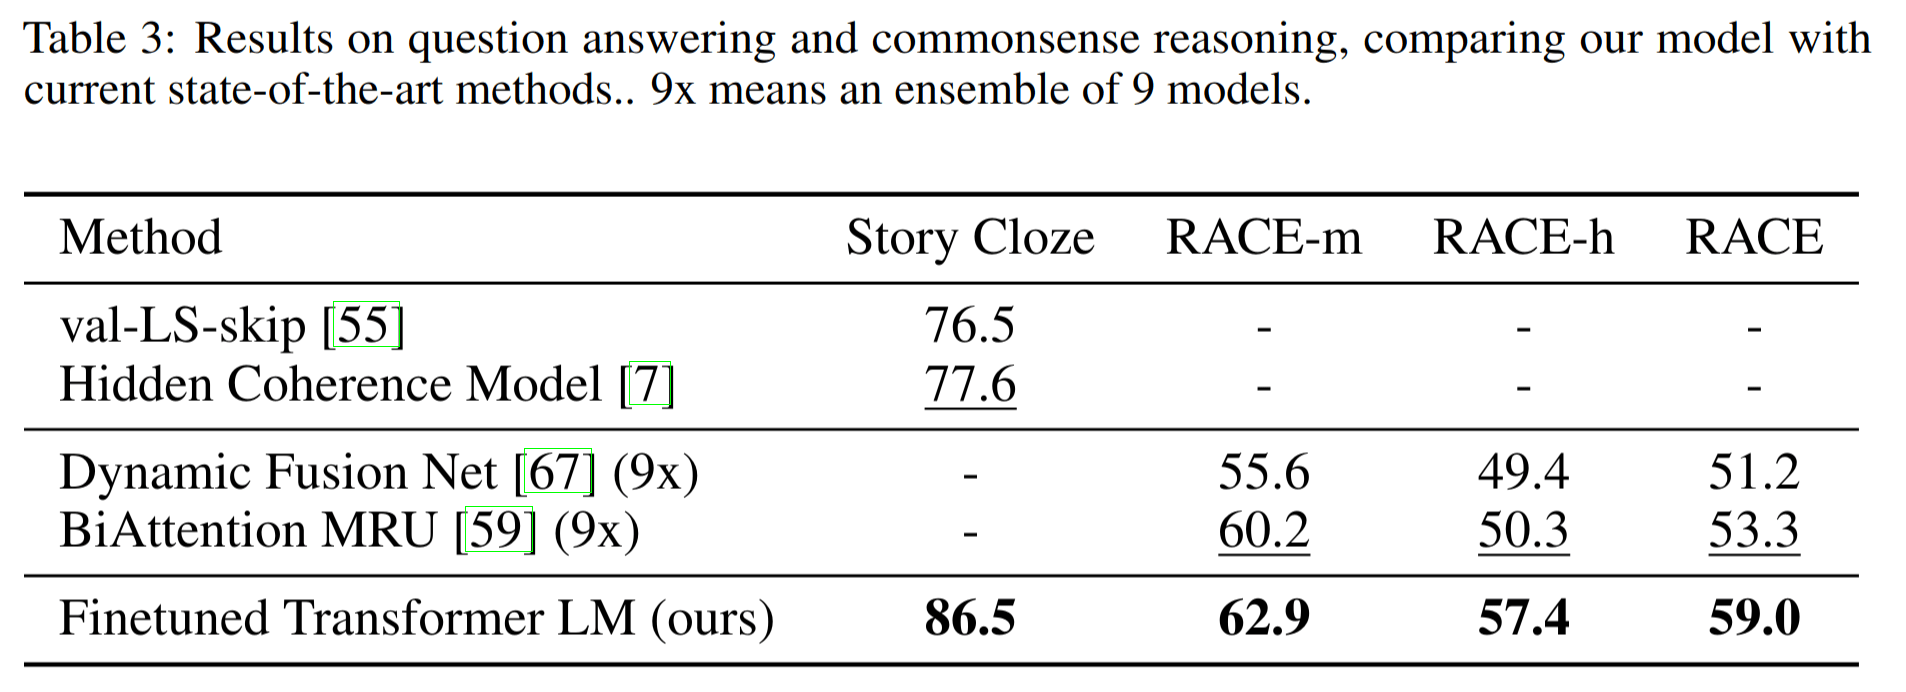
Main idea: train transformer to predict text, then fine-tune linear layers for task
GPT-1
GPT-1 (117M)
GPT-2
- Improving Language Understanding by Generative Pre-Training
- 1.5 B Parameters
- Open AI; 2019; 15,510 citations
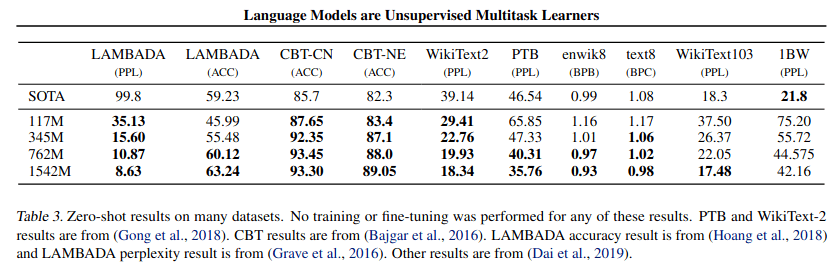
Main idea: Zero-shot transfer
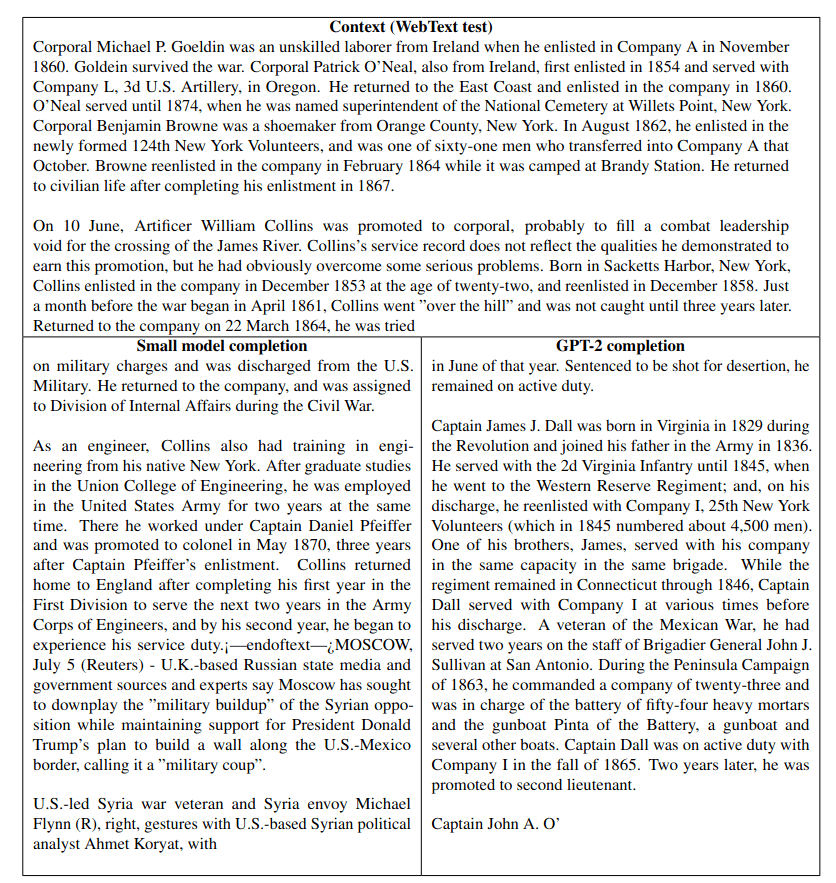
GPT-2
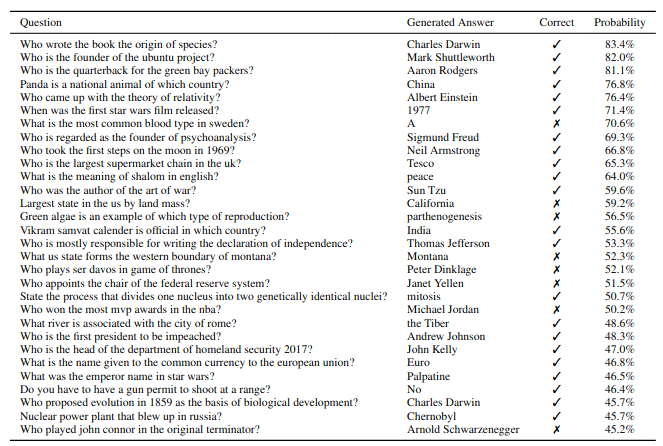
GPT-2
GPT-3
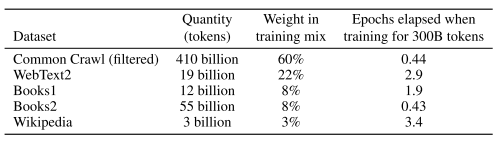
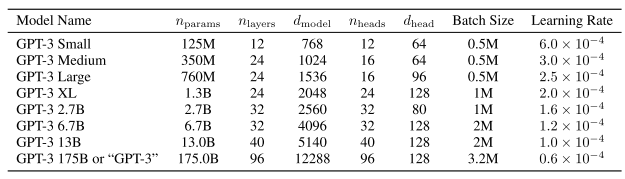
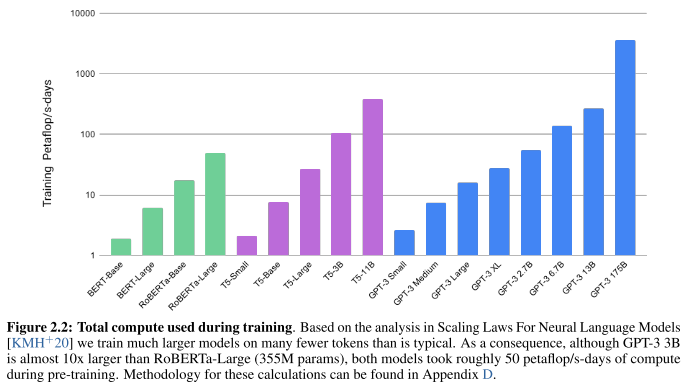

- Language Models are Few-Shot Learners
- 175B Parameters
- Open AI; 2020; 53081 citations
Main Idea: Scale Up
Scaling
- Scaling Laws for Neural Language Models
- Senior Author: Dario Amodei (Anthropic)
- Open AI; 2020; 4411 citations
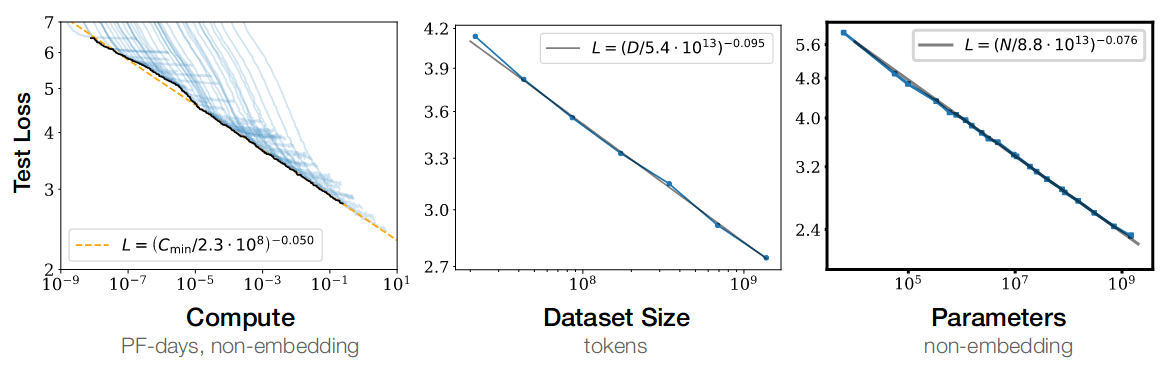
Scaling
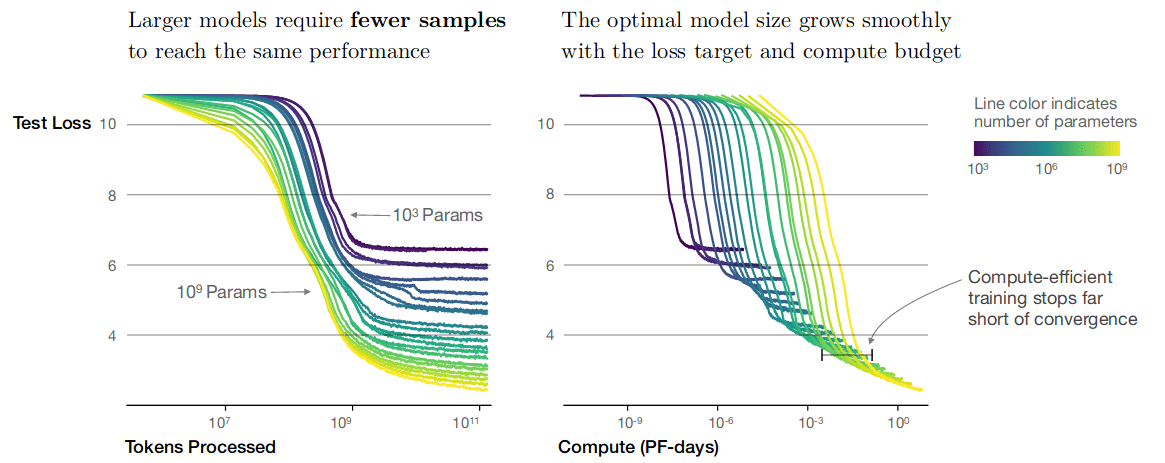
Scaling
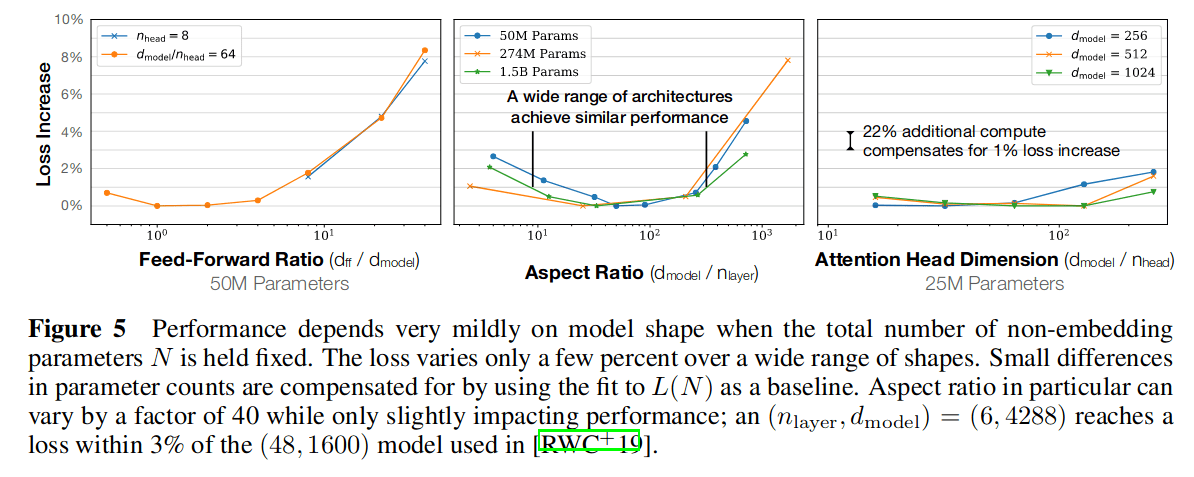
Scaling
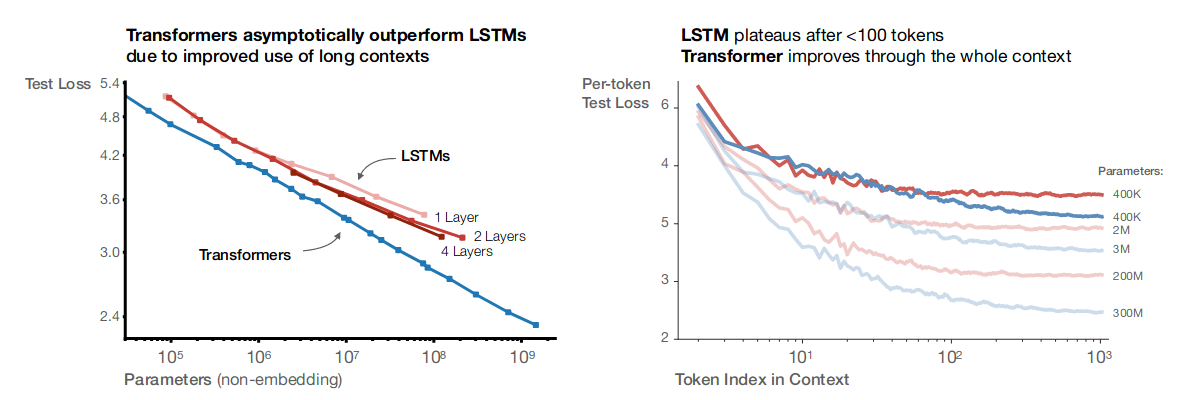
Scaling
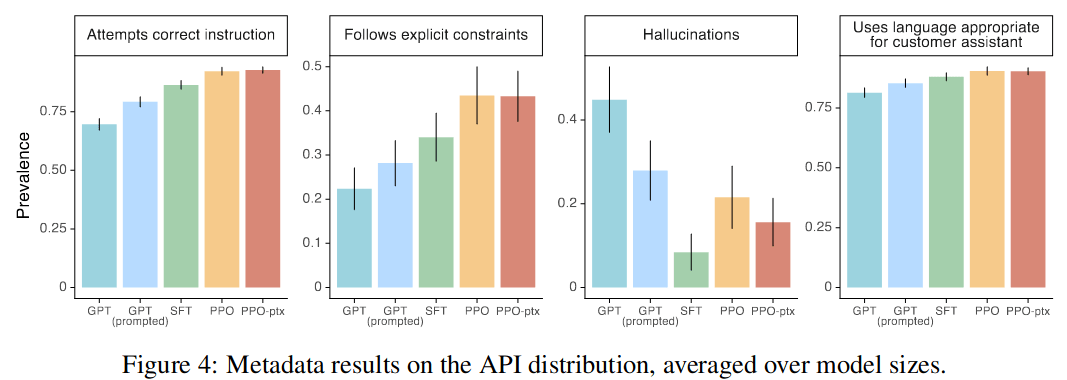
InstructGPT
- Training language models to follow instructions with human feedback
- OpenAI, 2022
- 1.3B
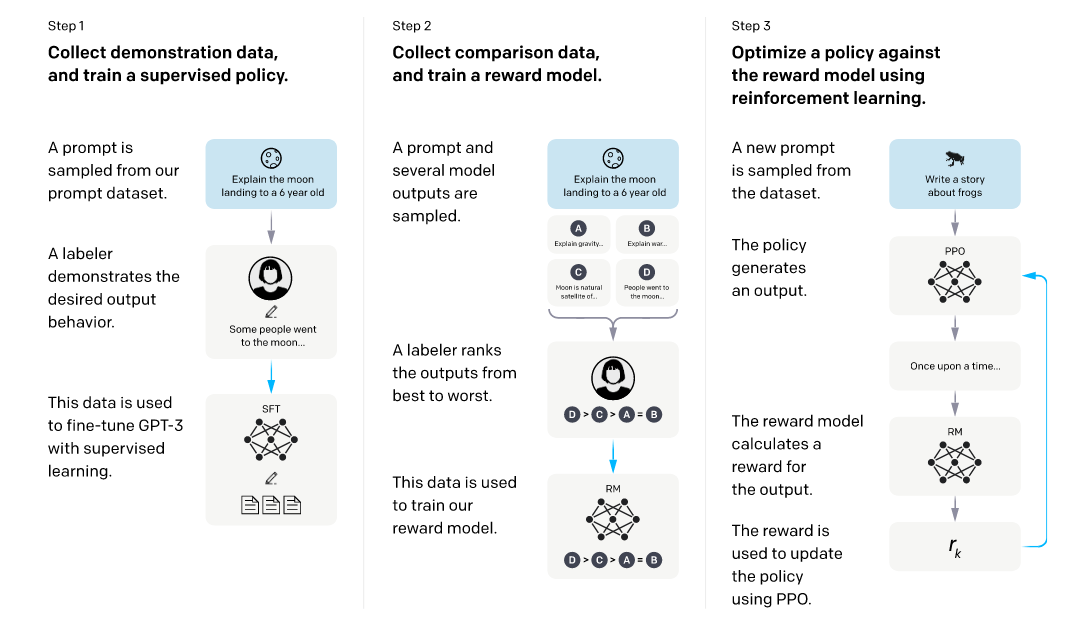
InstructGPT
ChatGPT
GPT-4 and GPT-5 have increasingly less information publicly available: GPT-5 System card